Fractionnement des données externes pour la récupération

Développement d'applications LLM avec LangChain

Jonathan Bennion

AI Engineer & LangChain Contributor

Étapes du développement RAG

Flux de travail général RAG : chargeur de documents, séparateur de documents, processus de stockage et de récupération.

Division de documents : diviser un document en plusieurs parties Divisez les documents pour qu'ils s'adaptent à {{1}}la fenêtre contextuelle d'un LLM

Développement d'applications LLM avec LangChain

En parlant de fractionnement...

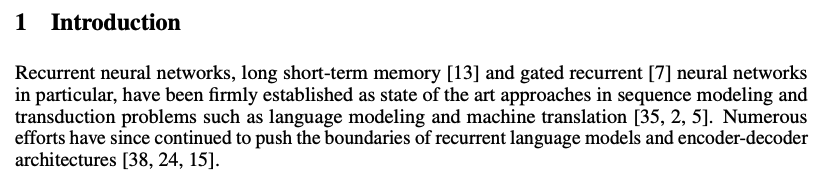
Le premier paragraphe de l’introduction de l’article Attention is All You Need.

Ligne 1 :

Recurrent neural networks, long short-term memory [13] and gated recurrent [7] neural networks

Ligne 2 :

in particular, have been firmly established as state of the art approaches in sequence modeling and
1 https://arxiv.org/abs/1706.03762
Développement d'applications LLM avec LangChain

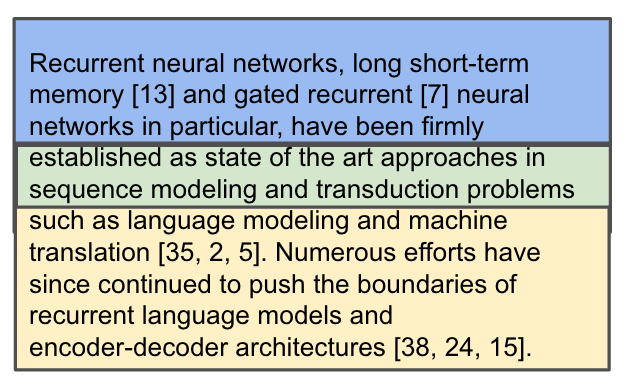
Chevauchement de morceaux

Le premier paragraphe de l’introduction de l’article Attention is All You Need divisé en deux segments avec un chevauchement de segments.

Développement d'applications LLM avec LangChain

Quelle est la meilleure stratégie pour diviser un document ?
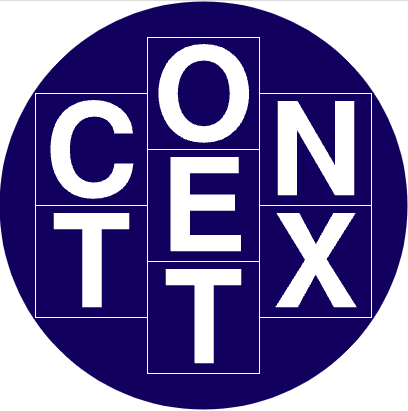
Le mot « context » découpé lettre par lettre.

  1. CharacterTextSplitter
  2. RecursiveCharacterTextSplitter
  3. Beaucoup d'autres
1 Wikipedia Commons
Développement d'applications LLM avec LangChain
quote = '''One machine can do the work of fifty ordinary humans.\nNo machine can do
the work of one extraordinary human.'''
len(quote)
103
chunk_size = 24
chunk_overlap = 3
1 Elbert Hubbard
Développement d'applications LLM avec LangChain
from langchain_text_splitters import CharacterTextSplitter


ct_splitter = CharacterTextSplitter( separator='.', chunk_size=chunk_size, chunk_overlap=chunk_overlap)
docs = ct_splitter.split_text(quote) print(docs)
print([len(doc) for doc in docs])
['One machine can do the work of fifty ordinary humans',
 'No machine can do the work of one extraordinary human']

[52, 53]

Divisez sur le séparateur de sorte que < chunk_size, mais {{6}}cela peut ne pas toujours fonctionner.

Développement d'applications LLM avec LangChain
from langchain_text_splitters import RecursiveCharacterTextSplitter


rc_splitter = RecursiveCharacterTextSplitter( separators=["\n\n", "\n", " ", ""], chunk_size=chunk_size, chunk_overlap=chunk_overlap)
docs = rc_splitter.split_text(quote) print(docs)
Développement d'applications LLM avec LangChain

RecursiveCharacterTextSplitter

  • separators=["\n\n", "\n", " ", ""]
['One machine can do the',
 'work of fifty ordinary',
 'humans.',
 'No machine can do the',
 'work of one',
 'extraordinary human.']
  1. Essayez de diviser par paragraphe : "\n\n"
  2. Essayez de diviser par phrase : "\n"
  3. Essayez de diviser par mots : " "
Développement d'applications LLM avec LangChain

RecursiveCharacterTextSplitter avec HTML

from langchain_community.document_loaders import UnstructuredHTMLLoader 
from langchain_text_splitters import RecursiveCharacterTextSplitter


loader = UnstructuredHTMLLoader("white_house_executive_order_nov_2023.html") data = loader.load()
rc_splitter = RecursiveCharacterTextSplitter( chunk_size=chunk_size, chunk_overlap=chunk_overlap, separators=['.'])
docs = rc_splitter.split_documents(data) print(docs[0])
Document(page_content="To search this site, enter a search term [...]
Développement d'applications LLM avec LangChain

Passons à la pratique !

Développement d'applications LLM avec LangChain

Preparing Video For Download...