Préparer les données pour le modélisme
Machine Learning pour le marketing en Python

Karolis Urbonas
Head of Analytics & Science, Amazon
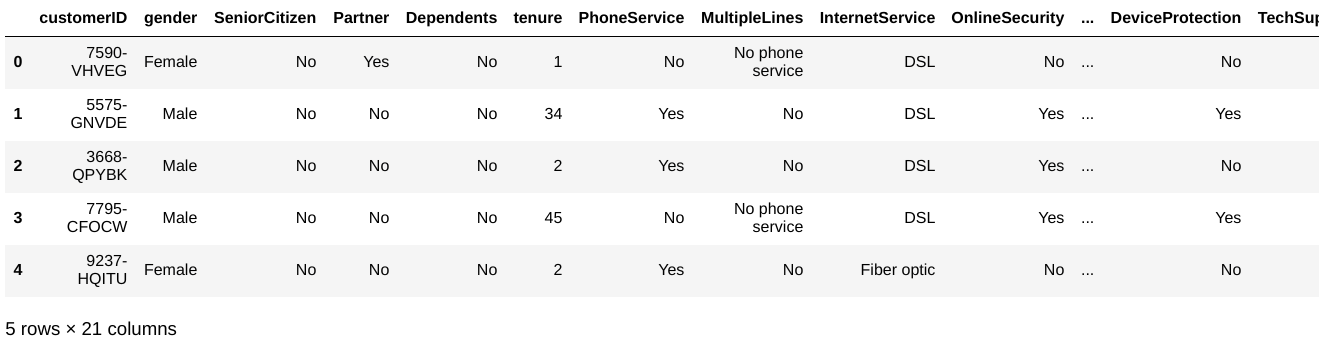
Échantillon de données
telco_raw.head()
Types de données
telco_raw.dtypes
customerID           object
gender               object
SeniorCitizen        object
Partner              object
Dependents           object
tenure                int64
PhoneService         object
MultipleLines        object
InternetService      object
OnlineSecurity       object
OnlineBackup         object
DeviceProtection     object
TechSupport          object
StreamingTV          object
StreamingMovies      object
Contract             object
PaperlessBilling     object
PaymentMethod        object
MonthlyCharges      float64
TotalCharges        float64
Churn                object
Séparer colonnes catégorielles et numériques
Séparer l'identifiant et la cible dans des listes
custid = ['customerID']
target = ['Churn']
Séparer les colonnes catégorielles et numériques en listes
categorical = telco_raw.nunique()[telcom.nunique()<10].keys().tolist()categorical.remove(target[0])numerical = [col for col in telco_raw.columns if col not in custid+target+categorical]
Encodage one-hot
Voici une colonne typiquement de type catégoriel
| Couleur |
|---|
| Rouge |
| Blanc |
| Bleu |
| Rouge |
Résultat de l'encodage one-hot
Voici le résultat après encodage one-hot.
| Couleur | Rouge | Blanc | Bleu | |
|---|---|---|---|---|
| Rouge | ----------> | 1 | 0 | 0 |
| Blanc | ----------> | 0 | 1 | 0 |
| Bleu | ----------> | 0 | 0 | 1 |
| Rouge | ----------> | 1 | 0 | 0 |
Encodage one-hot des variables catégorielles
Encoder en one-hot les variables catégorielles
telco_raw = pd.get_dummies(data=telco_raw, columns=categorical, drop_first=True)
Mettre à l'échelle les variables numériques
# Import StandardScaler library from sklearn.preprocessing import StandardScaler# Initialize StandardScaler instance scaler = StandardScaler()# Fit the scaler to numerical columns scaled_numerical = scaler.fit_transform(telco_raw[numerical])# Build a DataFrame scaled_numerical = pd.DataFrame(scaled_numerical, columns=numerical)
Réunir le tout
# Drop non-scaled numerical columns telco_raw = telco_raw.drop(columns=numerical, axis=1)# Merge the non-numerical with the scaled numerical data telco = telco_raw.merge(right=scaled_numerical, how='left', left_index=True, right_index=True )
Passons à la pratique du prétraitement !
Machine Learning pour le marketing en Python

