Traitement du texte Twitter

Analyzing Social Media Data in R

Vivek Vijayaraghavan

Data Science Coach

Aperçu de la leçon

  • Pourquoi traiter le texte des tweets ?
  • Étapes du traitement de texte des tweets
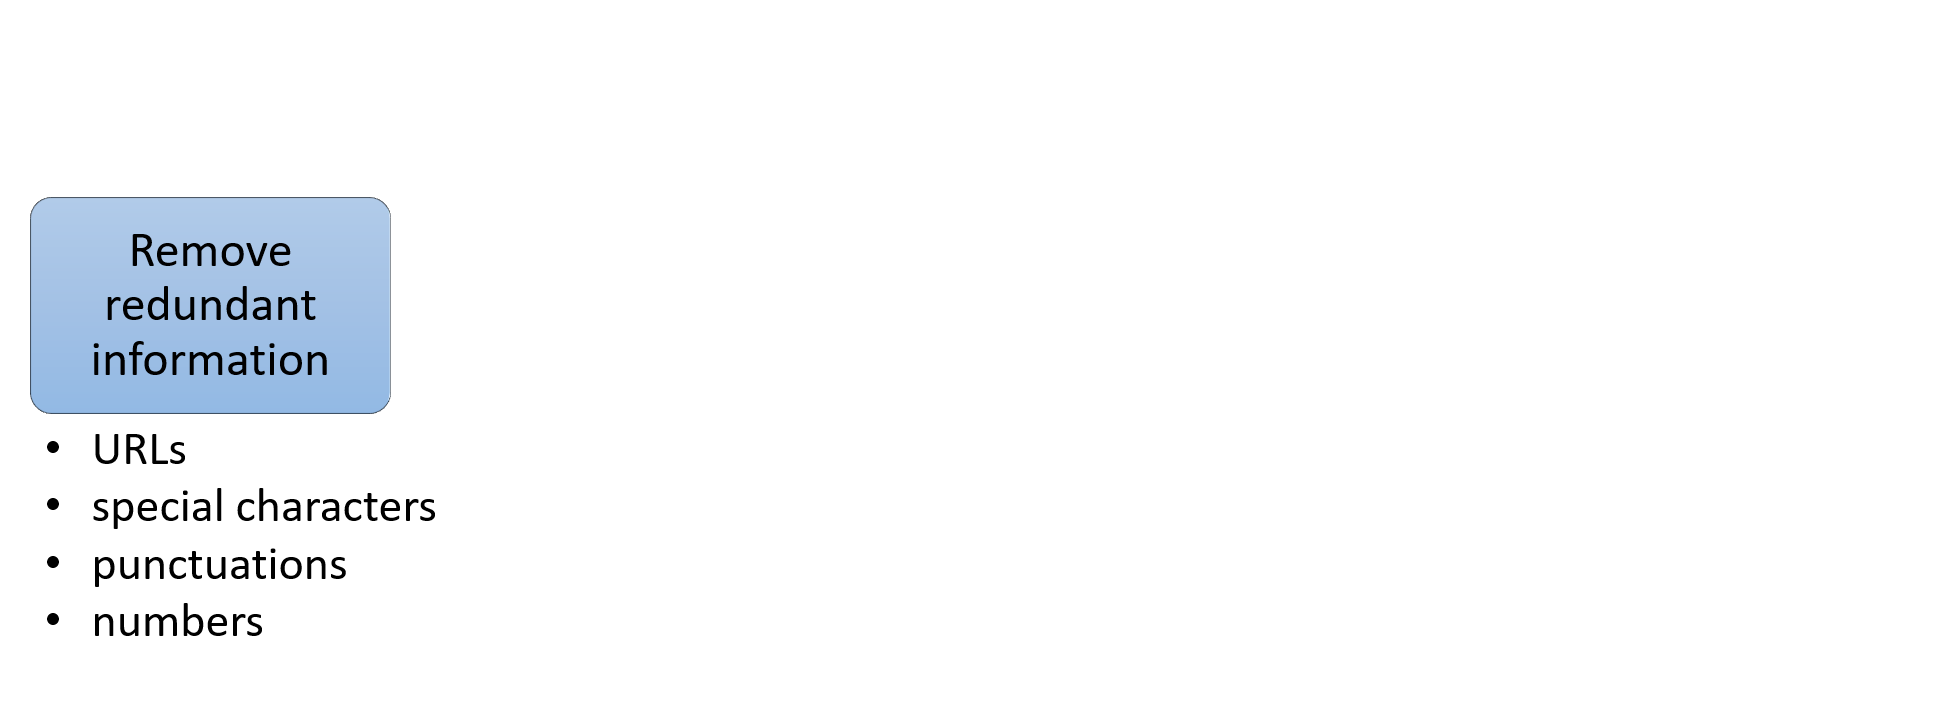
    • supprimer les informations redondantes
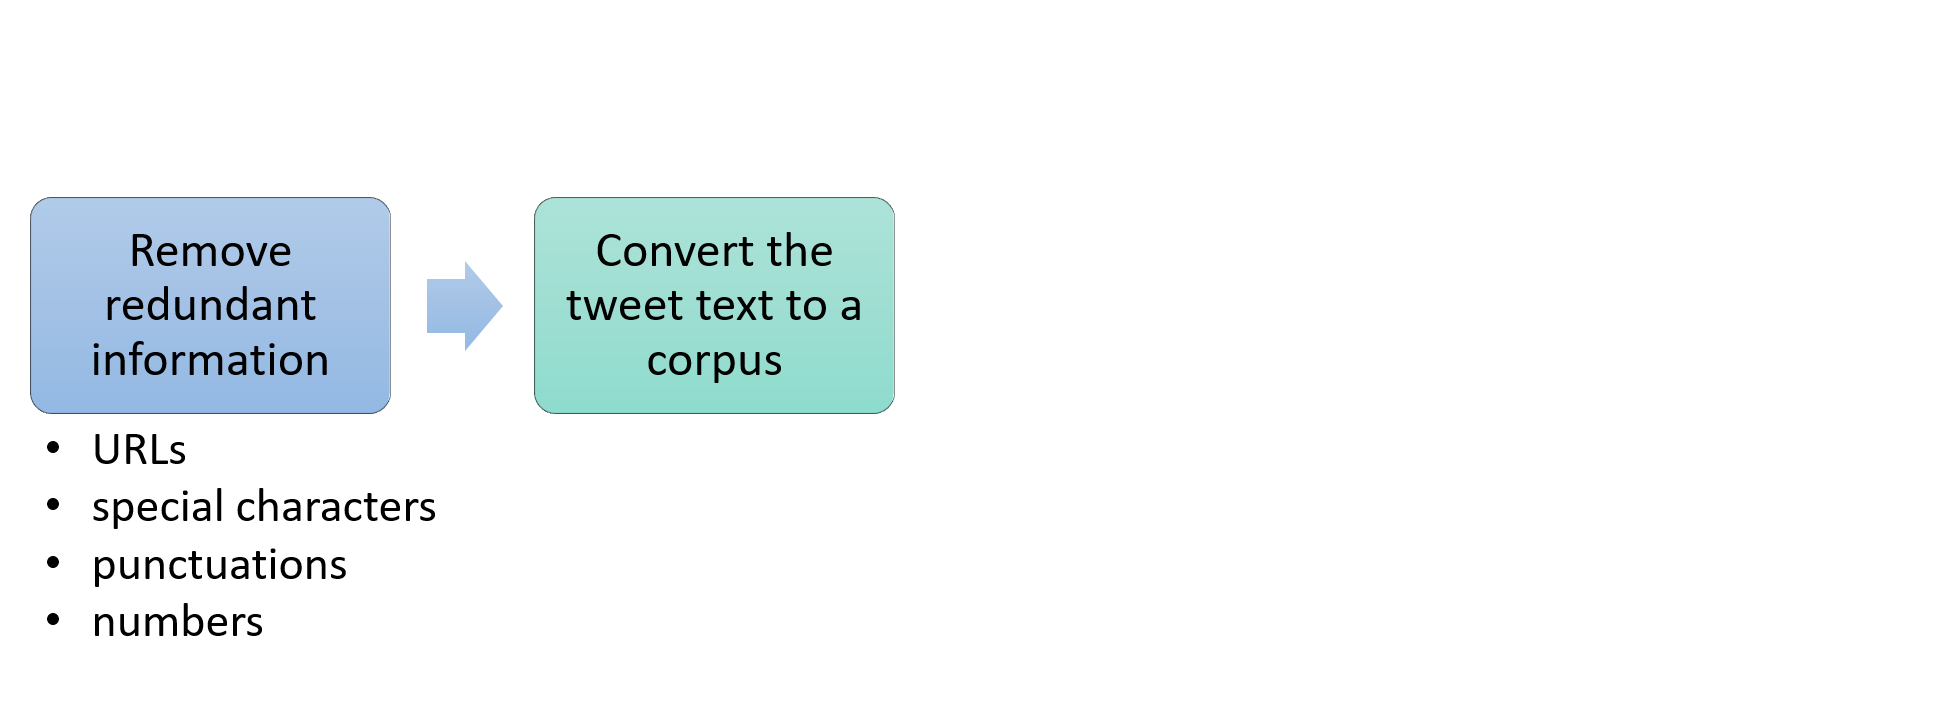
    • Convertir le texte en corpus
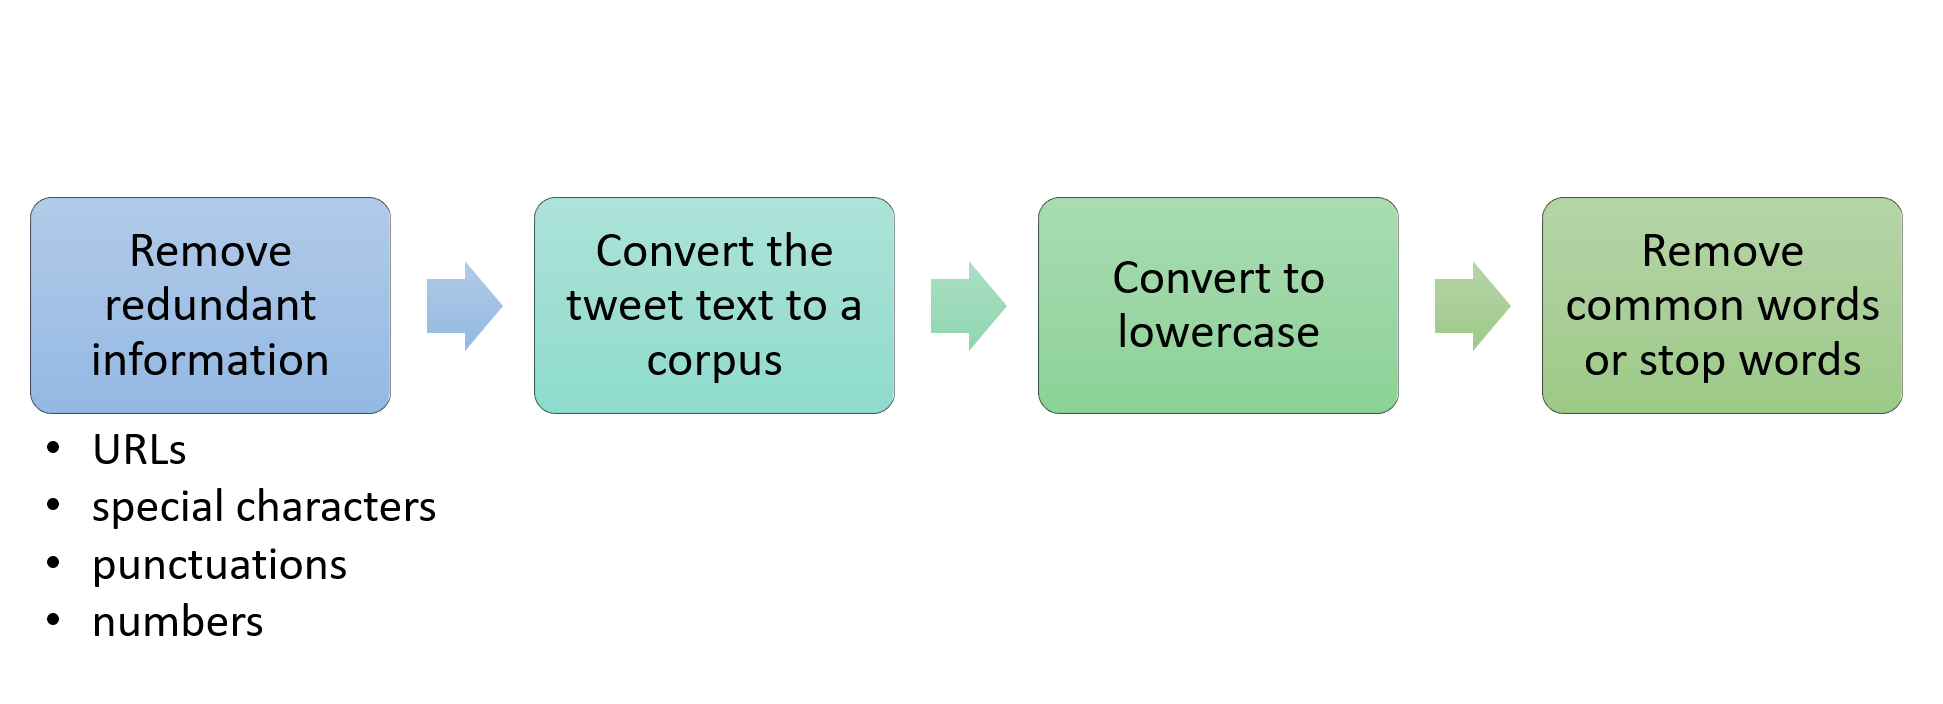
    • Supprimer les mots vides
Analyzing Social Media Data in R

Pourquoi traiter le texte des tweets ?

  • Le texte des tweets est non structuré, bruyé et brut
  • Contient des émoticônes, des URL, des chiffres
  • Un texte propre est requis pour l'analyse et des résultats fiables
Analyzing Social Media Data in R

Étapes du traitement de texte

Étape 1 : Supprimer les informations redondantes

Analyzing Social Media Data in R

Étapes du traitement de texte

Étape 2 : Convertir le texte en corpus

Analyzing Social Media Data in R

Étapes du traitement de texte

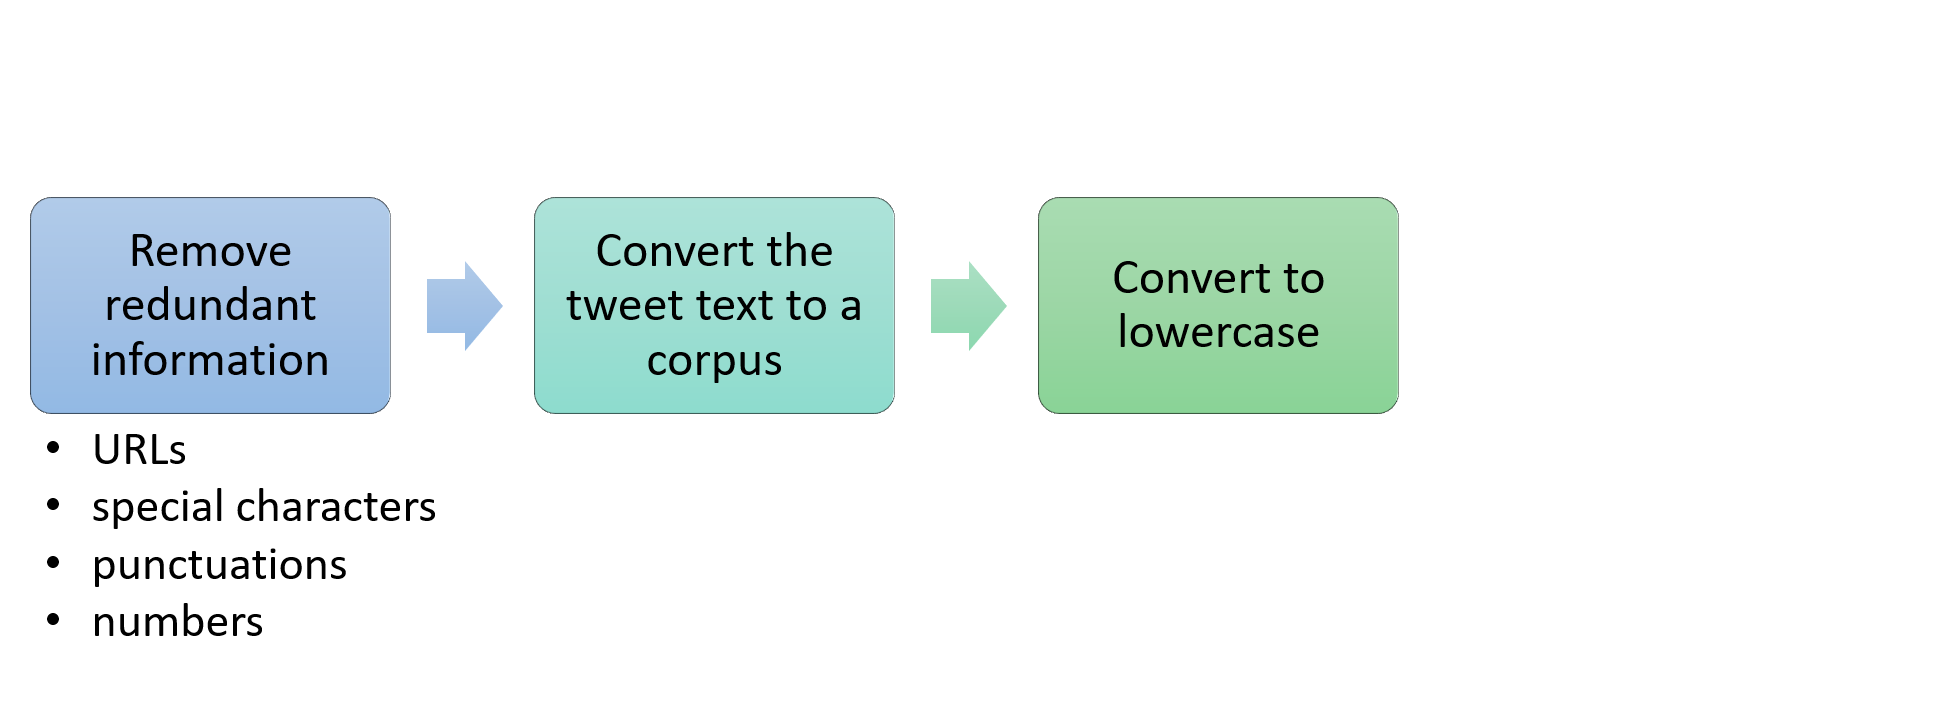
Étape 3 : Convertir en minuscules

Analyzing Social Media Data in R

Étapes du traitement de texte

Étape 4 : Supprimer les mots vides

Analyzing Social Media Data in R

Extraire le texte des tweets

# Extraire 1000 tweets sur "Obesity" en anglais et exclure les retweets
tweets_df <- search_tweets("Obesity", n = 1000, include_rts = F, lang = 'en')
# Extraire le texte des tweets et l'enregistrer dans un data frame
twt_txt <- tweets_df$text
Analyzing Social Media Data in R

Extraire le texte des tweets

head(twt_txt, 3)
[1] "@WeeaUwU for real, obesity should not be praised like it is in today's society" 

[2] "Great work by @DosingMatters in @AJHPOfficial on \"Vancomycin Vd estimation in 
adults with class III obesity\". As we continue to study/learn more about dosing in 
large body weight pts, we see that it's not a simple, one size, one level estimate 
that works https://t.co/KkYPqS6JzG" 

[3] "The Scottish Government have an ambition to halve childhood obesity by 2030. 
This means reducing obesity prevalence in 2-15yo children in Scotland to 7%. 
\n\n\U0001f449 In 2018, this figure was 16%\n\nFind out more in our latest blog: 
https://t.co/FWp56QWjQc https://t.co/XBK8Je7F1A"
Analyzing Social Media Data in R

Suppression des URL

# Supprimer les URL du texte des tweets
library(qdapRegex)
twt_txt_url <- rm_twitter_url(twt_txt)
Analyzing Social Media Data in R

Suppression des URL

twt_txt_url[1:3]
[1] "@WeeaUwU for real, obesity should not be praised like it is in today's society"

[2] "Great work by @DosingMatters in @AJHPOfficial on \"Vancomycin Vd estimation in  adults 
with class III obesity\". As we continue to study/learn more about dosing in large body 
weight pts, we see that it's not a simple, one size, one level estimate that works"

[3] "The Scottish Government have an ambition to halve childhood obesity by 2030. 
This means reducing obesity prevalence in 2-15yo children in Scotland to 7%. 
\U0001f449In 2018, this figure was 16% Find out more in our latest blog:"  
Analyzing Social Media Data in R

Caractères spéciaux, ponctuation et chiffres

# Supprimer caractères spéciaux, ponctuation et chiffres
twt_txt_chrs  <- gsub("[^A-Za-z]", " ", twt_txt_url)
Analyzing Social Media Data in R

Caractères spéciaux, ponctuation et chiffres

twt_txt_chrs[1:3]
[1] " WeeaUwU for real  obesity should not be praised like it is in today s society"

[2] "Great work by  DosingMatters in  AJHPOfficial on  Vancomycin Vd estimation in 
adults with class III obesity   As we continue to study learn more about dosing in 
large body weight pts  we see that it s not a simple  one size  one level estimate 
that works"

[3] "The Scottish Government have an ambition to halve childhood obesity by       This 
means reducing obesity prevalence in     yo children in Scotland to       In       this 
figure was     Find out more in our latest blog "   
Analyzing Social Media Data in R

Convertir en corpus textuel

# Convertir en corpus textuel
library(tm)
twt_corpus <- twt_txt_chrs %>% 
                VectorSource() %>% 
                Corpus()
twt_corpus[[3]]$content
[1] "The Scottish Government have an ambition to halve childhood obesity by       
This means reducing obesity prevalence in     yo children in Scotland to       In  
     this figure was     Find out more in our latest blog "
Analyzing Social Media Data in R

Convertir en minuscules

  • Un mot ne doit pas être compté comme deux différents si seule la casse diffère
# Convertir le corpus en minuscules
twt_corpus_lwr <- tm_map(twt_corpus, tolower) 
twt_corpus_lwr[[3]]$content
[1] "the scottish government have an ambition to halve childhood obesity by     this 
means reducing obesity prevalence in     yo children in scotland to       in    this 
figure was     find out more in our latest blog "
Analyzing Social Media Data in R

Que sont les mots vides ?

  • Les mots vides sont des mots courants comme a, an, and, but
# Mots vides courants en anglais
stopwords("english")
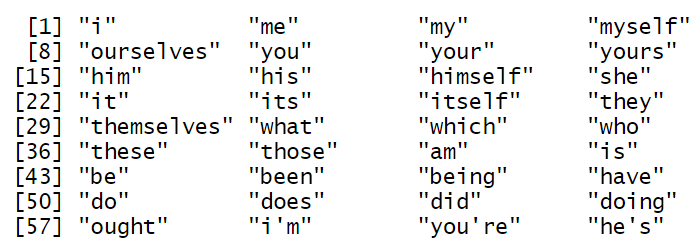
Liste par défaut des mots vides en anglais

Analyzing Social Media Data in R

Supprimer les mots vides

  • Il faut supprimer les mots vides pour se concentrer sur l'essentiel
# Supprimer les mots vides du corpus
twt_corpus_stpwd <- tm_map(twt_corpus_lwr, removeWords, stopwords("english"))
twt_corpus_stpwd[[3]]$content

[1] " scottish government   ambition  halve childhood obesity         means 
reducing obesity prevalence      yo children  scotland                figure      
find     latest blog "
Analyzing Social Media Data in R

Supprimer les espaces supplémentaires

  • Supprimer les espaces supplémentaires pour obtenir un corpus propre
# Supprimer les espaces supplémentaires
twt_corpus_final <- tm_map(twt_corpus_stpwd, stripWhitespace)
twt_corpus_final[[3]]$content
[1] " scottish government ambition halve childhood obesity means reducing obesity 
prevalence yo children scotland figure find latest blog "
Analyzing Social Media Data in R

Passons à la pratique !

Analyzing Social Media Data in R

Preparing Video For Download...