Explorando LLMs pré-treinados

Reinforcement Learning from Human Feedback (RLHF)

Mina Parham

AI Engineer

A importância do fine-tuning
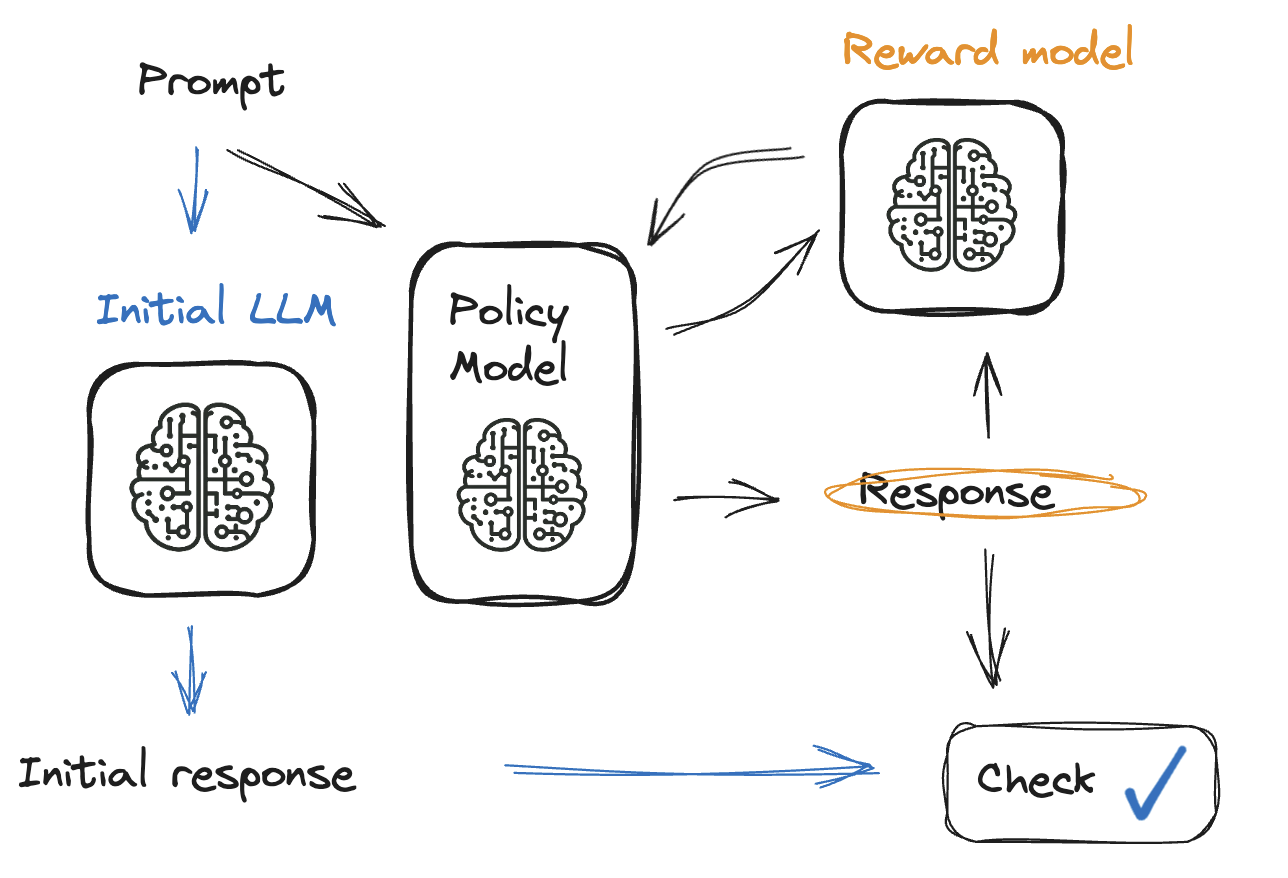
Um diagrama ilustrando o processo de RLHF.

Reinforcement Learning from Human Feedback (RLHF)

A importância do fine-tuning

Um diagrama representando um LLM com entrada e saída.

Reinforcement Learning from Human Feedback (RLHF)

Guia passo a passo para fazer fine-tuning em um LLM
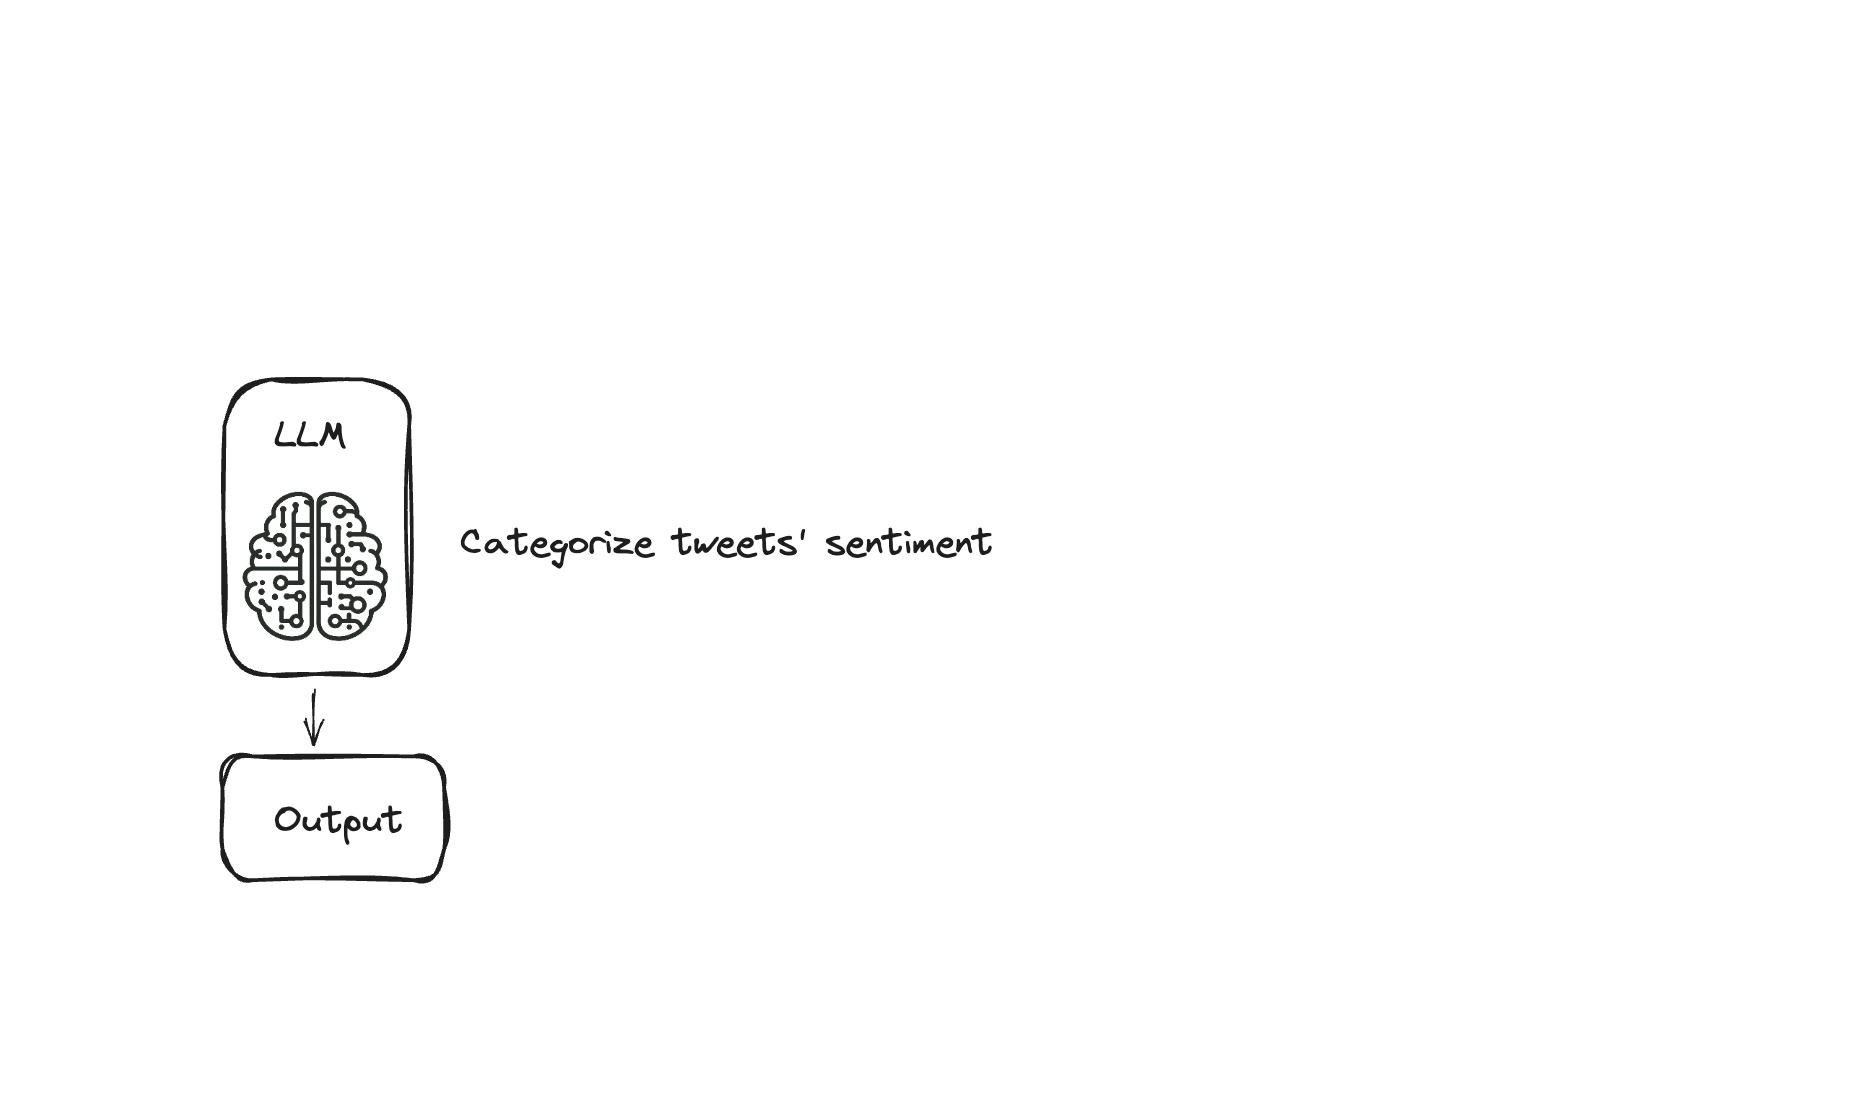
Um ícone representando um LLM treinado para reconhecer o sentimento de tweets.

Reinforcement Learning from Human Feedback (RLHF)

Guia passo a passo para fazer fine-tuning em um LLM
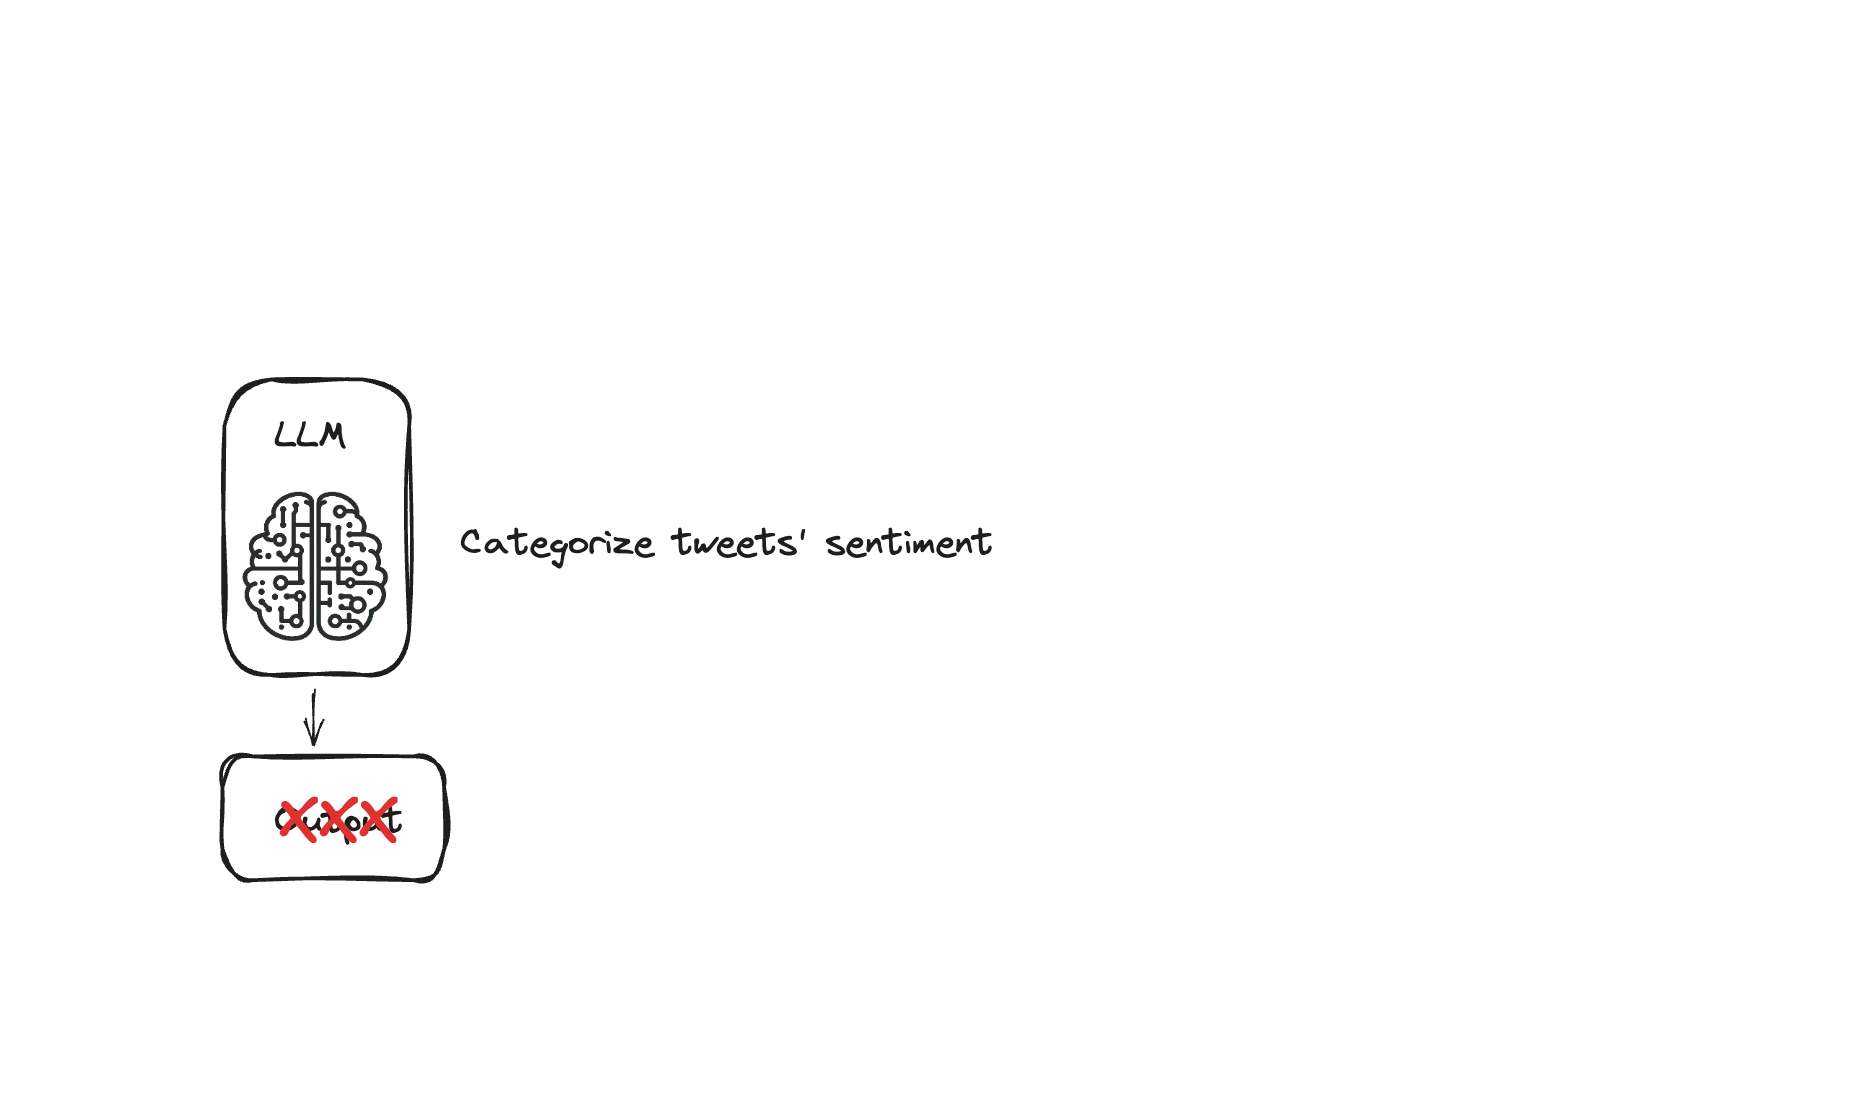
Um ícone representando um LLM treinado para reconhecer o sentimento de tweets dando a saída errada.

Reinforcement Learning from Human Feedback (RLHF)

Guia passo a passo para fazer fine-tuning em um LLM
Um ícone representando um LLM para reconhecer o sentimento de tweets, pré-treinado com um grande conjunto de dados.

Reinforcement Learning from Human Feedback (RLHF)

Etapa 1: carregar os dados a usar

from datasets import load_dataset
import pandas as pd

# `load_dataset` simplifies loading and preprocessing datasets from various sources
# It provides easy access to a wide range of datasets with minimal setup
dataset = load_dataset("mteb/tweet_sentiment_extraction")
df = pd.DataFrame(dataset['train'])
    id               text                                        label   label_text
0   cb774db0d1       I'd have responded, if I were going         1       neutral
1   549e992a42       Sooo SAD I will miss you in San Diego!!!    0       negative
2   08ac60f138       my boss is bullying me...                   0       negative
Reinforcement Learning from Human Feedback (RLHF)

Etapa 2: escolher um modelo pré-treinado

from transformers import AutoModelForCausalLM

# AutoModelForCausalLM simplifies loading and switching models
model = AutoModelForCausalLM.from_pretrained("openai-gpt")


  • Modelos causais: tokens anteriores "causam" os seguintes
Reinforcement Learning from Human Feedback (RLHF)

Etapa 3: tokenizer

from transformers import AutoTokenizer

# `AutoTokenizer` loads the correct tokenizer for the specified model
tokenizer = AutoTokenizer.from_pretrained("openai-gpt")
tokenizer.add_special_tokens({'pad_token': '[PAD]'})
model.resize_token_embeddings(len(tokenizer))


  • Padding: para ter lotes de texto do mesmo tamanho
Reinforcement Learning from Human Feedback (RLHF)

Etapa 3: tokenizer

def tokenize_function(examples):
    tokenized = tokenizer(examples["content"], padding="max_length", truncation=True) 
    return tokenized

tokenized_datasets = dataset.map(tokenize_function, batched=True)


  • Parâmetro batched: para processamento mais rápido
Reinforcement Learning from Human Feedback (RLHF)

Etapa 4: fazer fine-tuning com o método Trainer

training_args = TrainingArguments(
   output_dir="test_trainer",
   per_device_train_batch_size=1,
   per_device_eval_batch_size=1,  
   gradient_accumulation_steps=4)
trainer = Trainer(
   model=model,
   args=training_args,
   train_dataset=tokenized_dataset["train"],
   eval_dataset=tokenized_dataset["test"])
trainer.train()
Reinforcement Learning from Human Feedback (RLHF)

Vamos praticar!

Reinforcement Learning from Human Feedback (RLHF)

Preparing Video For Download...