Obtendo Mais Dados

Feature Engineering com PySpark

John Hogue

Lead Data Scientist, General Mills

Reflexões sobre conjuntos de dados externos

PRÓS

  • Adicionar preditores importantes
  • Complementar/substituir valores
  • Barato ou fácil de obter

Combinando dados

CONTRAS

  • Pode travar a análise
  • Fácil causar data leakage
  • Torne-se expert no assunto do conjunto
Responsabilidade

Feature Engineering com PySpark

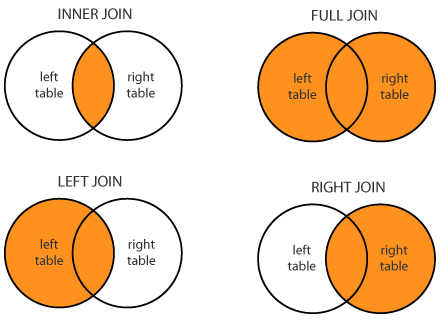
Sobre joins

Orientando nossas direções de dados

  • Esquerda: nosso conjunto inicial
  • Direita: novo conjunto a incorporar

Junções em SQL

Feature Engineering com PySpark

Joins em DataFrame do PySpark

DataFrame.join(

other, # Other DataFrame to merge
on=None, # The keys to join on
how=None) # Type of join to perform (default is 'inner')
Feature Engineering com PySpark

Exemplo de join no PySpark

# Inspect dataframe head
hdf.show(2)
+----------+--------------------+
|        dt|                  nm|
+----------+--------------------+
|2012-01-02|        New Year Day|
|2012-01-16|Martin Luther Kin...|
+----------+--------------------+
only showing top 2 rows
# Specify join conditon
cond = [df['OFFMARKETDATE'] == hdf['dt']]

# Join two hdf onto df df = df.join(hdf, on=cond, 'left')
# How many sales occurred on bank holidays? df.where(~df['nm'].isNull()).count()
0
Feature Engineering com PySpark

Join com SparkSQL

  • Aplique SQL ao seu dataframe
# Register the dataframe as a temp table
df.createOrReplaceTempView("df")
hdf.createOrReplaceTempView("hdf")
# Write a SQL Statement
sql_df = spark.sql("""
                      SELECT 
                        *
                      FROM df
                      LEFT JOIN hdf
                      ON df.OFFMARKETDATE = hdf.dt
                   """)
Feature Engineering com PySpark

Vamos juntar alguns dados!

Feature Engineering com PySpark

Preparing Video For Download...