Análise com janela móvel

Introdução ao Spark SQL em Python

Mark Plutowski

Data Scientist

O texto bruto

ADVENTURE  I.  A SCANDAL IN BOHEMIA

I.


To Sherlock Holmes she is always the woman. I have seldom heard him mention 
her under any other name. In his eyes she eclipses and predominates the whole 
of her sex. It was not that he felt any emotion akin to love for Irene Adler. 
All emotions, and that one particularly, were abhorrent to his cold, precise 
but admirably balanced mind. He was, I take it, the most perfect reasoning 
and observing machine that the world has seen, but as a lover he would have 
placed himself in a false position. He never spoke of the softer passions, 
save with a gibe and a sneer. They were admirable things for the observer--
excellent for drawing the veil from men's motives and actions. But for the 
trained reasoner to admit such intrusions into his own delicate and finely 
adjusted temperament was to introduce a distracting factor which might throw 
a doubt upon all his mental results. Grit in a sensitive instrument, or a 
crack in one of his own high-power lenses, would not be more disturbing than 
a strong emotion in a nature such as his. And yet there was but one woman to 
him, and that woman was the late Irene Adler, of dubious and questionable 
memory.
Introdução ao Spark SQL em Python

O texto processado

+--------+---+----+
|    word| id|part|
+--------+---+----+
| scandal|305|   1|
|      in|306|   1|
| bohemia|307|   1|
|       i|308|   1|
|      to|309|   1|
|sherlock|310|   1|
|  holmes|311|   1|
|     she|312|   1|
|      is|313|   1|
|  always|314|   1|
|     the|315|   1|
|   woman|316|   1|
|       i|317|   1|
|    have|318|   1|
|  seldom|319|   1|
|   heard|320|   1|
|     him|321|   1|
| mention|322|   1|
|     her|323|   1|
|   under|324|   1|
+--------+---+----+
Introdução ao Spark SQL em Python

Partições

df.select('part', 'title').distinct().sort('part').show(truncate=False)
+----+---------------------+
|part|title                |
+----+---------------------+
|1   |Sherlock Chapter I   |
|2   |Sherlock Chapter II  |
|3   |Sherlock Chapter III |
|4   |Sherlock Chapter IV  |
|5   |Sherlock Chapter V   |
|6   |Sherlock Chapter VI  |
|7   |Sherlock Chapter VII |
|8   |Sherlock Chapter VIII|
|9   |Sherlock Chapter IX  |
|10  |Sherlock Chapter X   |
|11  |Sherlock Chapter XI  |
|12  |Sherlock Chapter XII |
+----+---------------------+
Introdução ao Spark SQL em Python

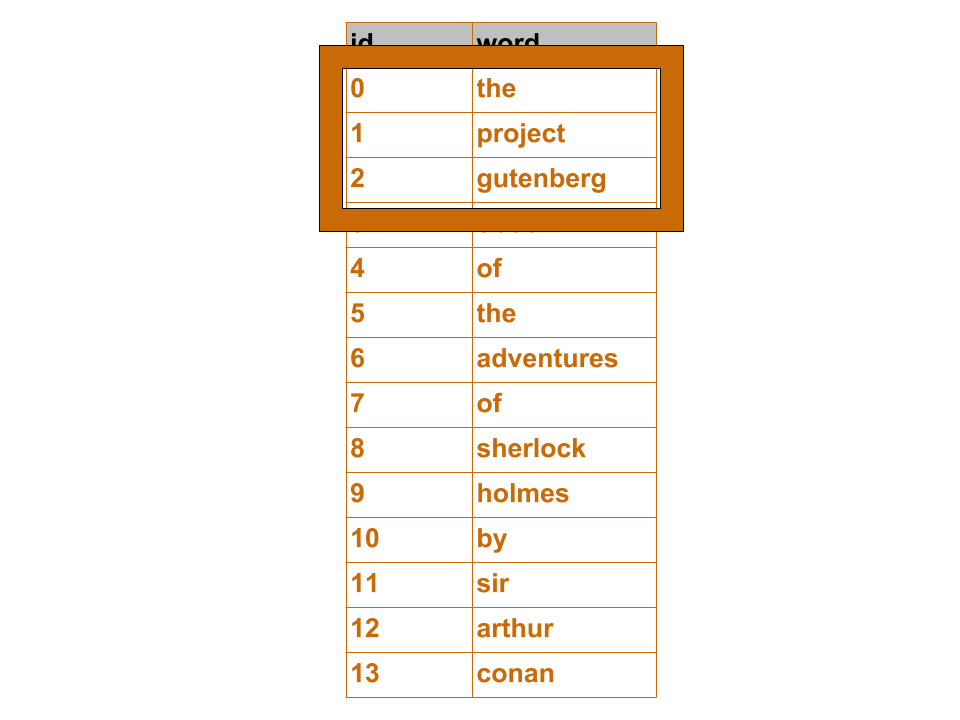
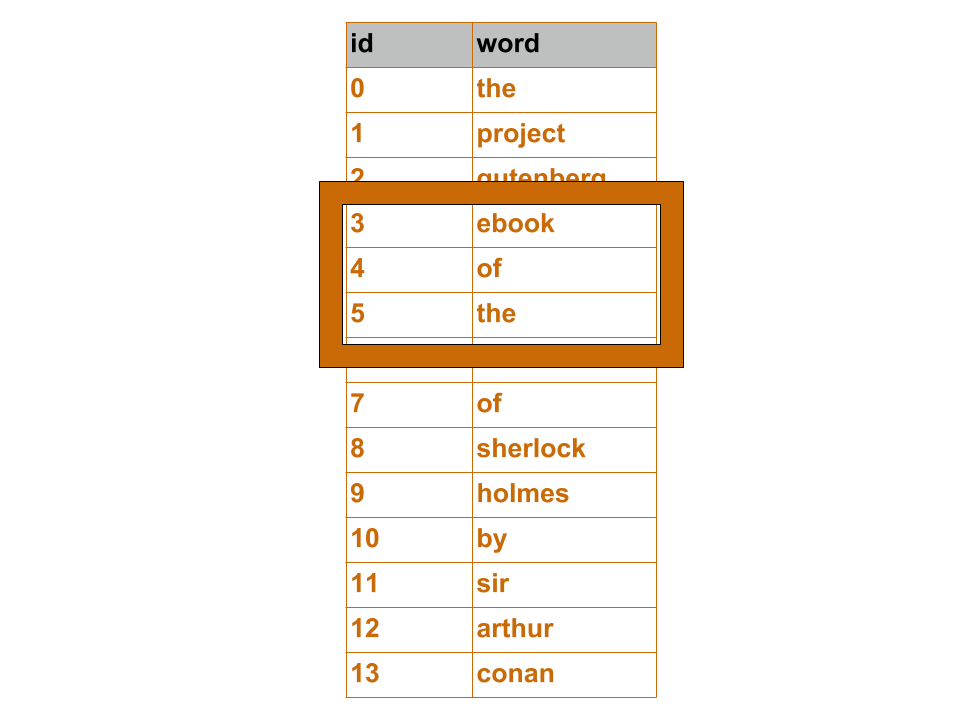
Janela móvel  0

Introdução ao Spark SQL em Python

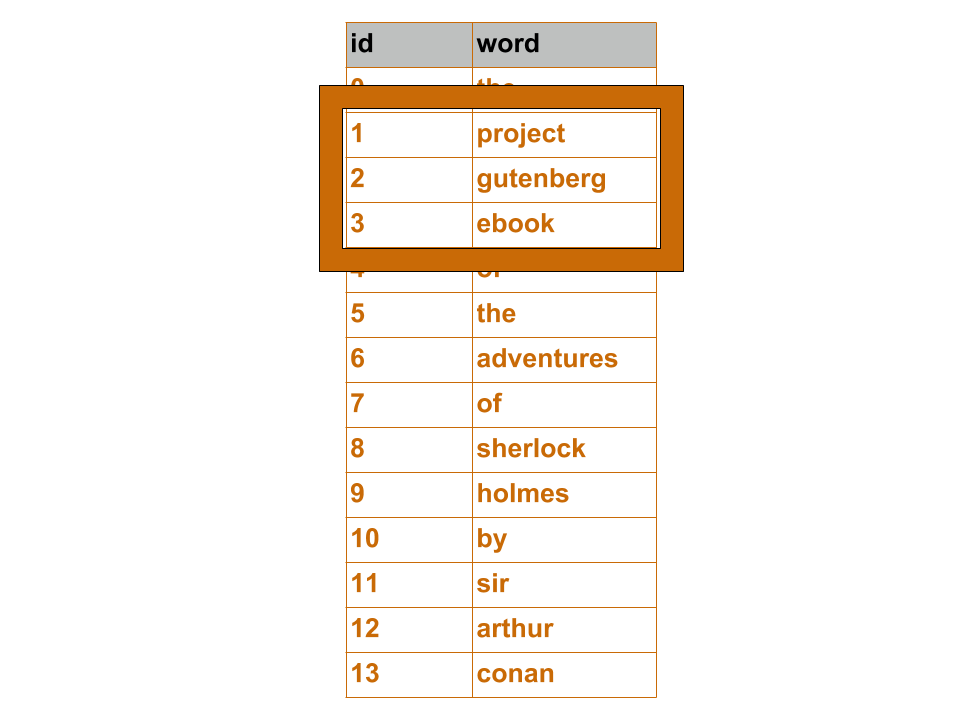
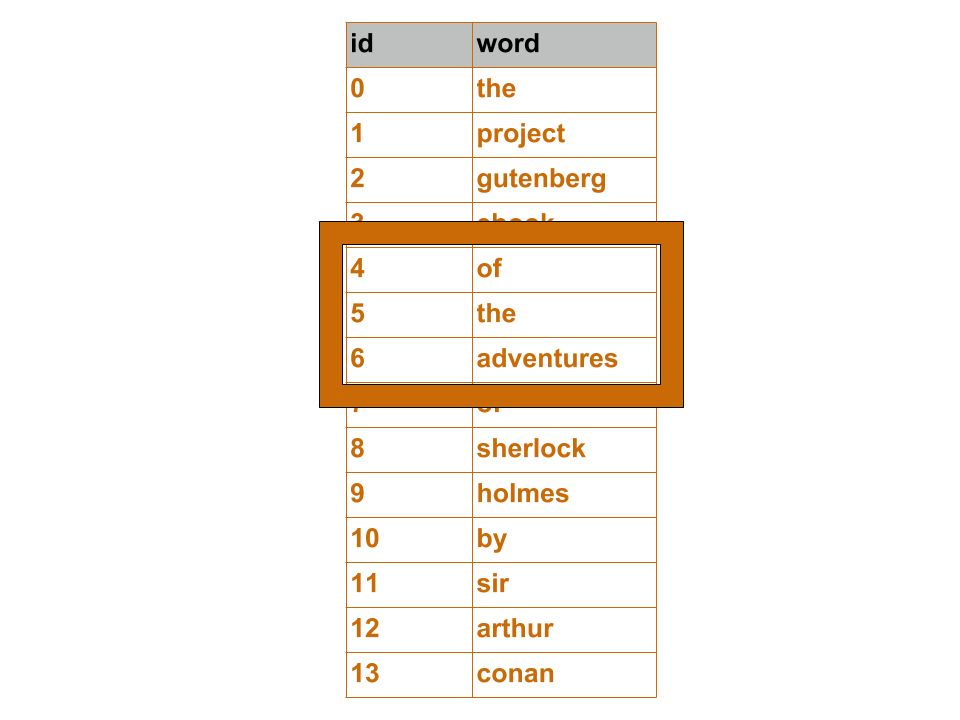
Janela móvel 1

Introdução ao Spark SQL em Python

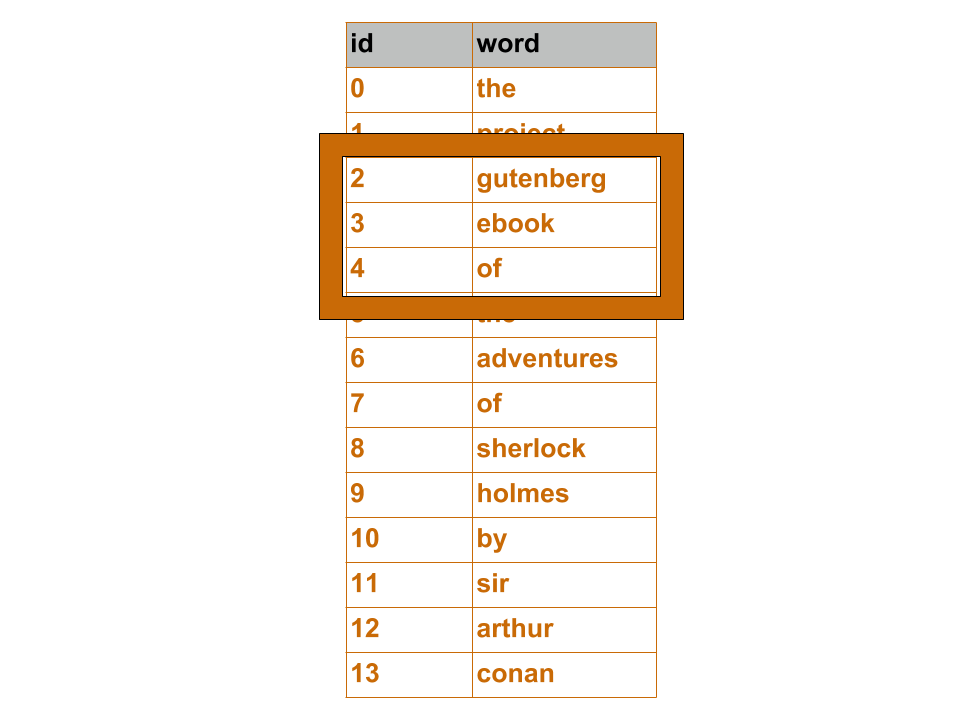
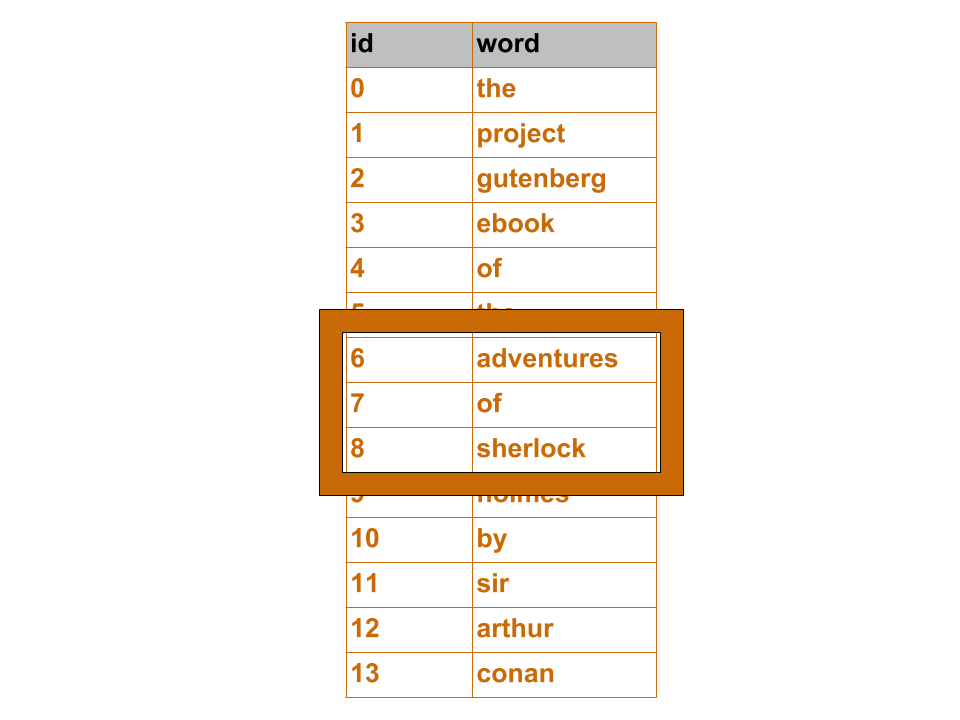
Janela móvel 2

Introdução ao Spark SQL em Python

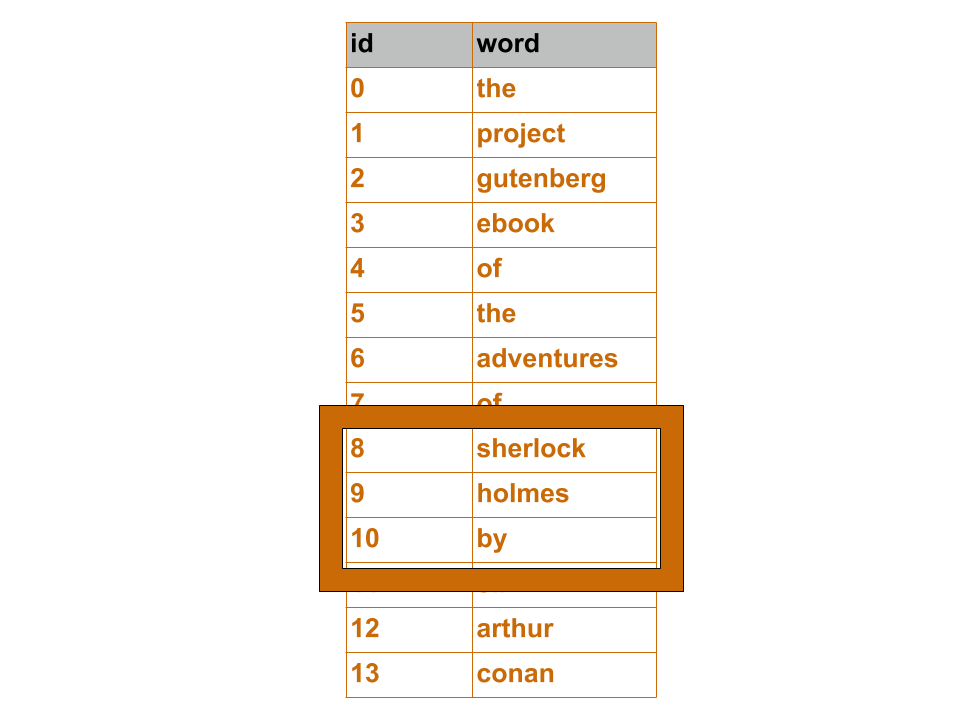
Janela móvel 3

Introdução ao Spark SQL em Python

Janela móvel 4

Introdução ao Spark SQL em Python

Janela móvel 5

Introdução ao Spark SQL em Python

Janela móvel 7

Introdução ao Spark SQL em Python

Janela móvel 10

Introdução ao Spark SQL em Python

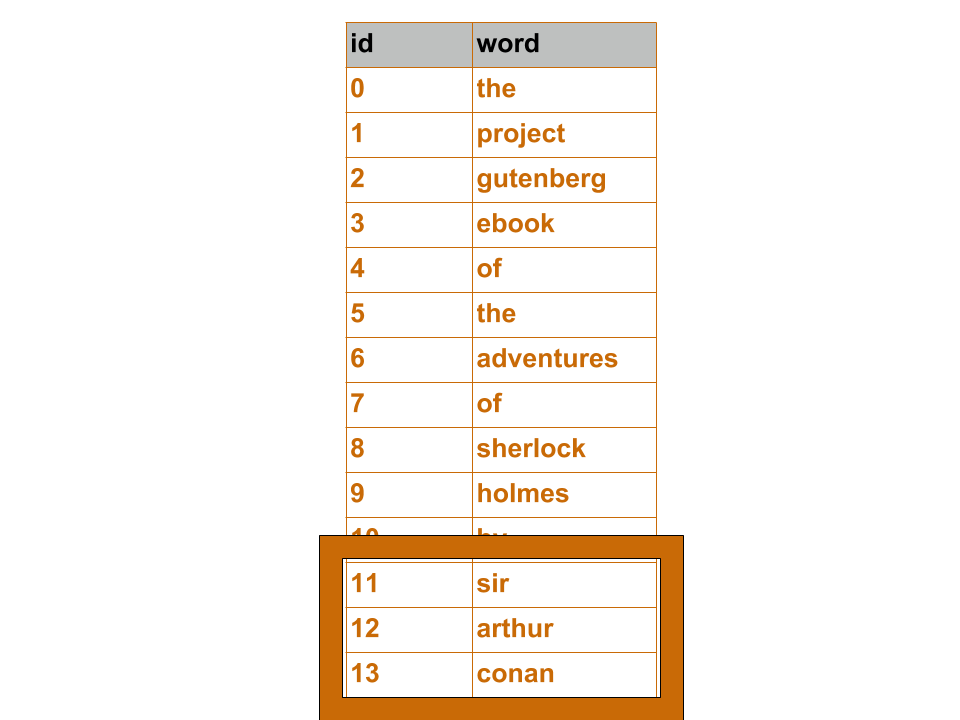
Janela móvel 13

Introdução ao Spark SQL em Python

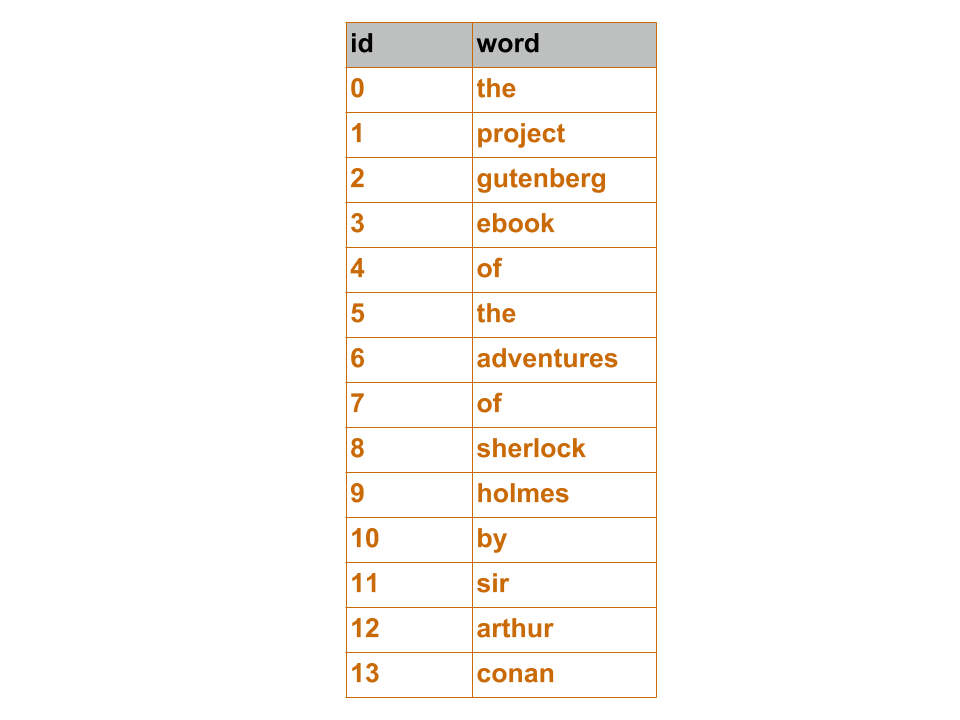
As palavras têm índice

+---+----------+
| id|      word|
+---+----------+
|  0|       the|
|  1|   project|
|  2| gutenberg|
|  3|     ebook|
|  4|        of|
|  5|       the|
|  6|adventures|
|  7|        of|
|  8|  sherlock|
|  9|    holmes|
| 10|        by|
| 11|       sir|
| 12|    arthur|
| 13|     conan|
| 14|     doyle|
| 15|       #15|
| 16|        in|
| 17|       our|
| 18|    series|
| 19|        by|
+---+----------+
Introdução ao Spark SQL em Python

Consulta com janela móvel

query = """
   SELECT id, word AS w1,
   LEAD(word,1) OVER(PARTITION BY part ORDER BY id ) AS w2,
   LEAD(word,2) OVER(PARTITION BY part ORDER BY id ) AS w3
   FROM df
""" 
spark.sql(query).sort('id').show()
+---+----------+----------+----------+
| id|        w1|        w2|        w3|
+---+----------+----------+----------+
|  0|       the|   project| gutenberg|
|  1|   project| gutenberg|     ebook|
|  2| gutenberg|     ebook|        of|
|  3|     ebook|        of|       the|
|  4|        of|       the|adventures|
|...|..........|..........|..........|
Introdução ao Spark SQL em Python

Saída da janela móvel

+---+----------+----------+----------+
| id|        w1|        w2|        w3|
+---+----------+----------+----------+
|  0|       the|   project| gutenberg|
|  1|   project| gutenberg|     ebook|
|  2| gutenberg|     ebook|        of|
|  3|     ebook|        of|       the|
|  4|        of|       the|adventures|
|  5|       the|adventures|        of|
|  6|adventures|        of|  sherlock|
|  7|        of|  sherlock|    holmes|
|  8|  sherlock|    holmes|        by|
|  9|    holmes|        by|       sir|
| 10|        by|       sir|    arthur|
| 11|       sir|    arthur|     conan|
| 12|    arthur|     conan|     doyle|
+---+----------+----------+----------+
Introdução ao Spark SQL em Python

Função de janela LAG

lag_query = """
   SELECT 
   id,
   LAG(word,2) OVER(PARTITION BY part ORDER BY id ) AS w1,
   LAG(word,1) OVER(PARTITION BY part ORDER BY id ) AS w2,
   word AS w3
   FROM df
   ORDER BY id
"""

spark.sql(lag_query).show()
Introdução ao Spark SQL em Python

LAG – saída

+---+----------+----------+----------+
| id|        w1|        w2|        w3|
+---+----------+----------+----------+
|  0|      null|      null|       the|
|  1|      null|       the|   project|
|  2|       the|   project| gutenberg|
|  3|   project| gutenberg|     ebook|
|  4| gutenberg|     ebook|        of|
|  5|     ebook|        of|       the|
|  6|        of|       the|adventures|
|  7|       the|adventures|        of|
|  8|adventures|        of|  sherlock|
|  9|        of|  sherlock|    holmes|
| 10|  sherlock|    holmes|        by|
| 11|    holmes|        by|       sir|
| 12|       ...|       ...|       ...|
+---+----------+----------+----------+
Introdução ao Spark SQL em Python

Janelas ficam no particionamento

lag_query = """
   SELECT 
   id,
   LAG(word,2) OVER(PARTITION BY part ORDER BY id ) AS w1,
   LAG(word,1) OVER(PARTITION BY part ORDER BY id ) AS w2,
   word AS w3
   FROM df
   WHERE part=2
"""

spark.sql(lag_query).show()
Introdução ao Spark SQL em Python

Janelas no particionamento – saída

+----+----------+----------+----------+
|  id|        w1|        w2|        w3|
+----+----------+----------+----------+
|8859|      null|      null|     part2|
|8860|      null|     part2| adventure|
|8861|     part2| adventure|        ii|
|8862| adventure|        ii|       the|
|8863|        ii|       the|red-headed|
|8864|       the|red-headed|    league|
|....|..........|..........|..........|
Introdução ao Spark SQL em Python

Reparticionamento

  • PARTITION BY
  • repartition()
Introdução ao Spark SQL em Python

Vamos praticar!

Introdução ao Spark SQL em Python

Preparing Video For Download...