A representação bag-of-words

Introdução ao Processamento de Linguagem Natural em R

Kasey Jones

Research Data Scientist

O exemplo anterior

animal_farm %>%
  unnest_tokens(output = "word", token = "words",
                input = text_column) %>%
  anti_join(stop_words) %>%
  count(word, sort = TRUE)
# A tibble: 3,611 x 2
   word         n
   <chr>    <int>
 1 animals    248
 2 farm       163
 ...
Introdução ao Processamento de Linguagem Natural em R

A representação bag-of-words

text1 <- c("Few words are important.")
text2 <- c("All words are important.")
text3 <- c("Most words are important.")

Unique Words:

  • few: only in text1
  • all: only in text2
  • most: only in text3
  • words, are, important
Introdução ao Processamento de Linguagem Natural em R

Representações vetoriais típicas

# Minúsculas, sem stop words
word_vector <- c("few", "all", "most", "words", "important")
# Representação para text1
text1 <- c("Few words are important.")
text1_vector <- c(1, 0, 0, 1, 1)
# Representação para text2
text2 <- c("All words are important.")
text2_vector <- c(0, 1, 0, 1, 1)
# Representação para text3
text3 <- c("Most words are important.")
text3_vector <- c(0, 0, 1, 1, 1)
Introdução ao Processamento de Linguagem Natural em R

Representação no tidytext

words <- animal_farm %>%
    unnest_tokens(output = "word", token = "words", input = text_column) %>%
    anti_join(stop_words) %>%
    count(chapter, word, sort = TRUE)
words
# A tibble: 6,807 x 3
   chapter    word         n
   <chr>      <chr>    <int>
 1 Chapter 8  napoleon    43
 2 Chapter 8  animals     41
 3 Chapter 9  boxer       34
...
Introdução ao Processamento de Linguagem Natural em R

Exemplo com uma palavra

words %>%
  filter(word == 'napoleon') %>%
  arrange(desc(n))
# A tibble: 9 x 3
  chapter    word         n
  <chr>      <chr>    <int>
1 Chapter 8  napoleon    43
2 Chapter 7  napoleon    24
3 Chapter 5  napoleon    22
...
8 Chapter 3  napoleon     3
9 Chapter 4  napoleon     1
Introdução ao Processamento de Linguagem Natural em R

Matrizes esparsas

library(tidytext); library(dplyr)
russian_tweets <- read.csv("russian_1.csv")
russian_tweets <- as_tibble(russian_tweets)

tidy_tweets <- russian_tweets %>%
  unnest_tokens(word, content) %>%
  anti_join(stop_words)
tidy_tweets %>%
  count(word, sort = TRUE)
# A tibble: 43,666 x 2
...
Introdução ao Processamento de Linguagem Natural em R

Matrizes esparsas (continuação)

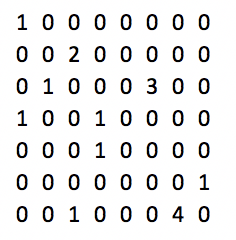
Matriz esparsa

  • 20.000 linhas (os tweets)
  • 43.000 colunas (as palavras)
  • 20.000 * 43.000 = 860.000.000
  • Só 177.000 entradas diferentes de 0. Cerca de 0,02%

Exemplo de matriz esparsa: Matrizes esparsas têm pouquíssimas entradas diferentes de 0. Ao visualizar uma matriz esparsa, quase tudo são zeros.

Introdução ao Processamento de Linguagem Natural em R

Prática de BoW

Introdução ao Processamento de Linguagem Natural em R

Preparing Video For Download...