Introduzione al preprocessing per il testo

Deep Learning per il testo con PyTorch

Shubham Jain

Data Scientist

Cosa imparerai

  • Classificazione di testi
  • Generazione di testi
  • Encoding
  • Modelli di deep learning per il testo
  • Architettura Transformer
  • Protezione dei modelli

Casi d'uso:

  • Analisi del sentiment
  • Riassunto di testi
  • Traduzione automatica

Analisi del sentiment

Deep Learning per il testo con PyTorch

Cosa dovresti sapere

Corso propedeutico: Intermediate Deep Learning with PyTorch

  • Modelli di deep learning con PyTorch
  • Cicli di training e valutazione
  • Reti neurali convoluzionali (CNN) e ricorrenti (RNN)
Deep Learning per il testo con PyTorch

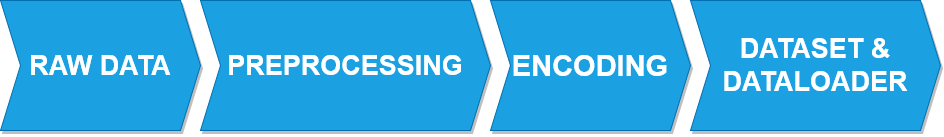
Pipeline di elaborazione del testo


Pipeline di elaborazione PyTorch

Deep Learning per il testo con PyTorch

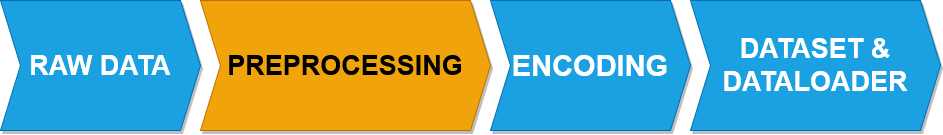
Pipeline di elaborazione del testo


Pipeline di elaborazione PyTorch


  • Pulisci e prepara il testo
Deep Learning per il testo con PyTorch

PyTorch e NLTK

Logo PyTorch

Logo NLTK

  • Natural language toolkit
    • Trasforma testo grezzo in testo processato
Deep Learning per il testo con PyTorch

Tecniche di preprocessing

  • Tokenizzazione
  • Rimozione delle stop word
  • Stemming
  • Rimozione di parole rare
Deep Learning per il testo con PyTorch

Tokenizzazione

  • Dal testo si estraggono token o parole
  • Tokenizzazione con torchtext
from torchtext.data.utils import get_tokenizer

tokenizer = get_tokenizer("basic_english")
tokens = tokenizer("I am reading a book now. I love to read books!") print(tokens)
["I", "am", "reading", "a", "book", "now", ".", "I", "love", "to", "read", 
"books", "!"]
Deep Learning per il testo con PyTorch

Rimozione delle stop word

  • Elimina parole comuni che non aggiungono significato
  • Stop word: "a", "the", "and", "or" e altre
import nltk
nltk.download('stopwords')
from nltk.corpus import stopwords

stop_words = set(stopwords.words('english'))
tokens = ["I", "am", "reading", "a", "book", "now", ".", "I", "love", "to", "read", "books", "!"] filtered_tokens = [token for token in tokens if token.lower() not in stop_words]
print(filtered_tokens)
["reading", "book", ".", "love", "read", "books", "!"]
Deep Learning per il testo con PyTorch

Stemming

  • Riduci le parole alla loro forma base
  • Per esempio: "running", "runs", "ran" diventano run
import nltk
from nltk.stem import PorterStemmer

stemmer = PorterStemmer()
filtered_tokens = ["reading", "book", ".", "love", "read", "books", "!"]
stemmed_tokens = [stemmer.stem(token) for token in filtered_tokens]
print(stemmed_tokens)
["read", "book", ".", "love", "read", "book", "!"]
Deep Learning per il testo con PyTorch

Rimozione di parole rare

  • Rimuovi parole poco frequenti che non aggiungono valore
from nltk.probability import FreqDist
stemmed_tokens= ["read", "book", ".", "love", "read", "book", "!"]  
freq_dist = FreqDist(stemmed_tokens)

threshold = 2
common_tokens = [token for token in stemmed_tokens if freq_dist[token] > threshold] print(common_tokens)
["read", "book", "read", "book"]
Deep Learning per il testo con PyTorch

Tecniche di preprocessing

Tokenizzazione, rimozione stopword, stemming e rimozione di parole rare

  • Riduci le feature
  • Insiemi di dati più puliti e rappresentativi
  • Esistono altre tecniche
Deep Learning per il testo con PyTorch

Esercitiamoci!

Deep Learning per il testo con PyTorch

Preparing Video For Download...