Introduzione a RLHF

Reinforcement Learning from Human Feedback (RLHF)

Mina Parham

AI Engineer

Benvenuto/a al corso!


  • Docente: Mina Parham


  • AI Engineer
  • Large Language Models (LLMs)
  • Reinforcement Learning from Human Feedback (RLHF)


  • Argomento: Reinforcement Learning from Human Feedback (RLHF)
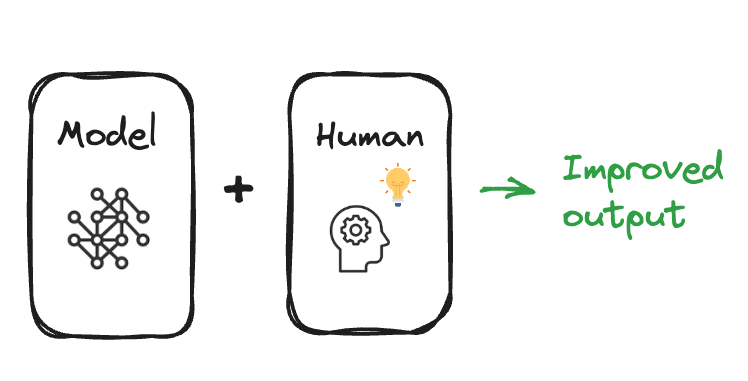
Schema che rappresenta un modello di IA con un passaggio aggiuntivo in cui interviene un umano.

Reinforcement Learning from Human Feedback (RLHF)

Benvenuto/a al corso!


  • Docente: Mina Parham


  • AI Engineer
  • Large Language Models (LLMs)
  • Reinforcement Learning from Human Feedback (RLHF)


  • Argomento: Reinforcement Learning from Human Feedback (RLHF)

Schema che mostra un modello di IA con un passaggio aggiuntivo in cui interviene un umano, portando a risultati migliori.

Reinforcement Learning from Human Feedback (RLHF)

Ripasso del reinforcement learning
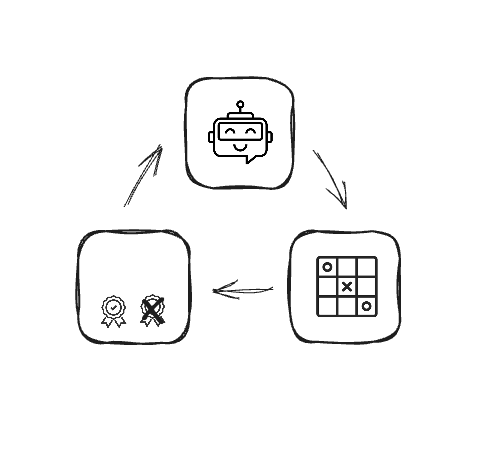
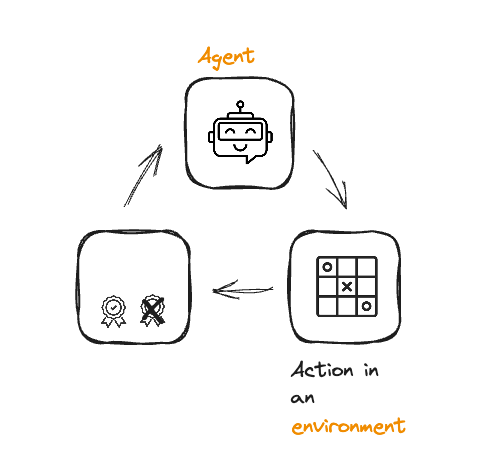
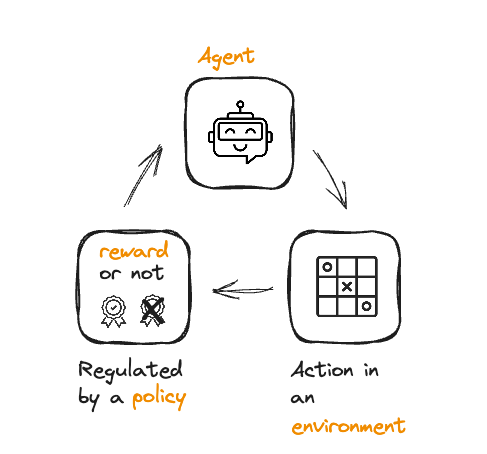
Schema con un'icona di un agente, un'azione e una politica di ricompensa in ciclo, che rappresenta il processo di reinforcement learning.

Reinforcement Learning from Human Feedback (RLHF)

Ripasso del reinforcement learning

Schema con un'icona di un agente, un'azione e una politica di ricompensa in ciclo, che rappresenta il processo di reinforcement learning.

Reinforcement Learning from Human Feedback (RLHF)

Ripasso del reinforcement learning

Schema con un'icona di un agente, un'azione e una politica di ricompensa in ciclo, che rappresenta il processo di reinforcement learning.

Reinforcement Learning from Human Feedback (RLHF)

Ripasso del reinforcement learning

Schema con un'icona di un agente, un'azione e una politica di ricompensa in ciclo, che rappresenta il processo di reinforcement learning.

Reinforcement Learning from Human Feedback (RLHF)

Da RL a RLHF


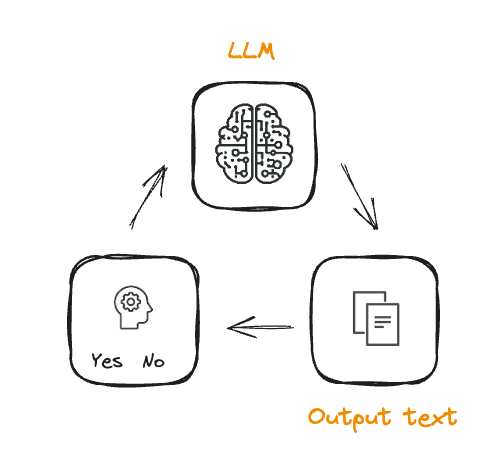
  Schema con un'icona di un LLM, un output testuale e un valutatore umano, che rappresenta parte del ciclo del reinforcement learning from human feedback.

Reinforcement Learning from Human Feedback (RLHF)

Da RL a RLHF


  Schema con un'icona di un LLM, un output testuale e un valutatore umano, che rappresenta parte del ciclo del reinforcement learning from human feedback.

Reinforcement Learning from Human Feedback (RLHF)

Da RL a RLHF

  • Addestrare il reward model
  • Allineamento alle preferenze umane

Schema con un'icona di un LLM, un output testuale e un valutatore umano, che rappresenta parte del ciclo del reinforcement learning from human feedback.

Reinforcement Learning from Human Feedback (RLHF)

Fine-tuning degli LLM in RLHF


Icona di un large language model.

Reinforcement Learning from Human Feedback (RLHF)

Fine-tuning degli LLM in RLHF

  • Addestrare l'LLM iniziale

Icona di un large language model ottimizzato con un insieme di dati di input.

Reinforcement Learning from Human Feedback (RLHF)

L'intero processo RLHF

Un prompt che chiede "Who wrote Romeo and Juliet" inviato a un LLM.

Reinforcement Learning from Human Feedback (RLHF)

L'intero processo RLHF

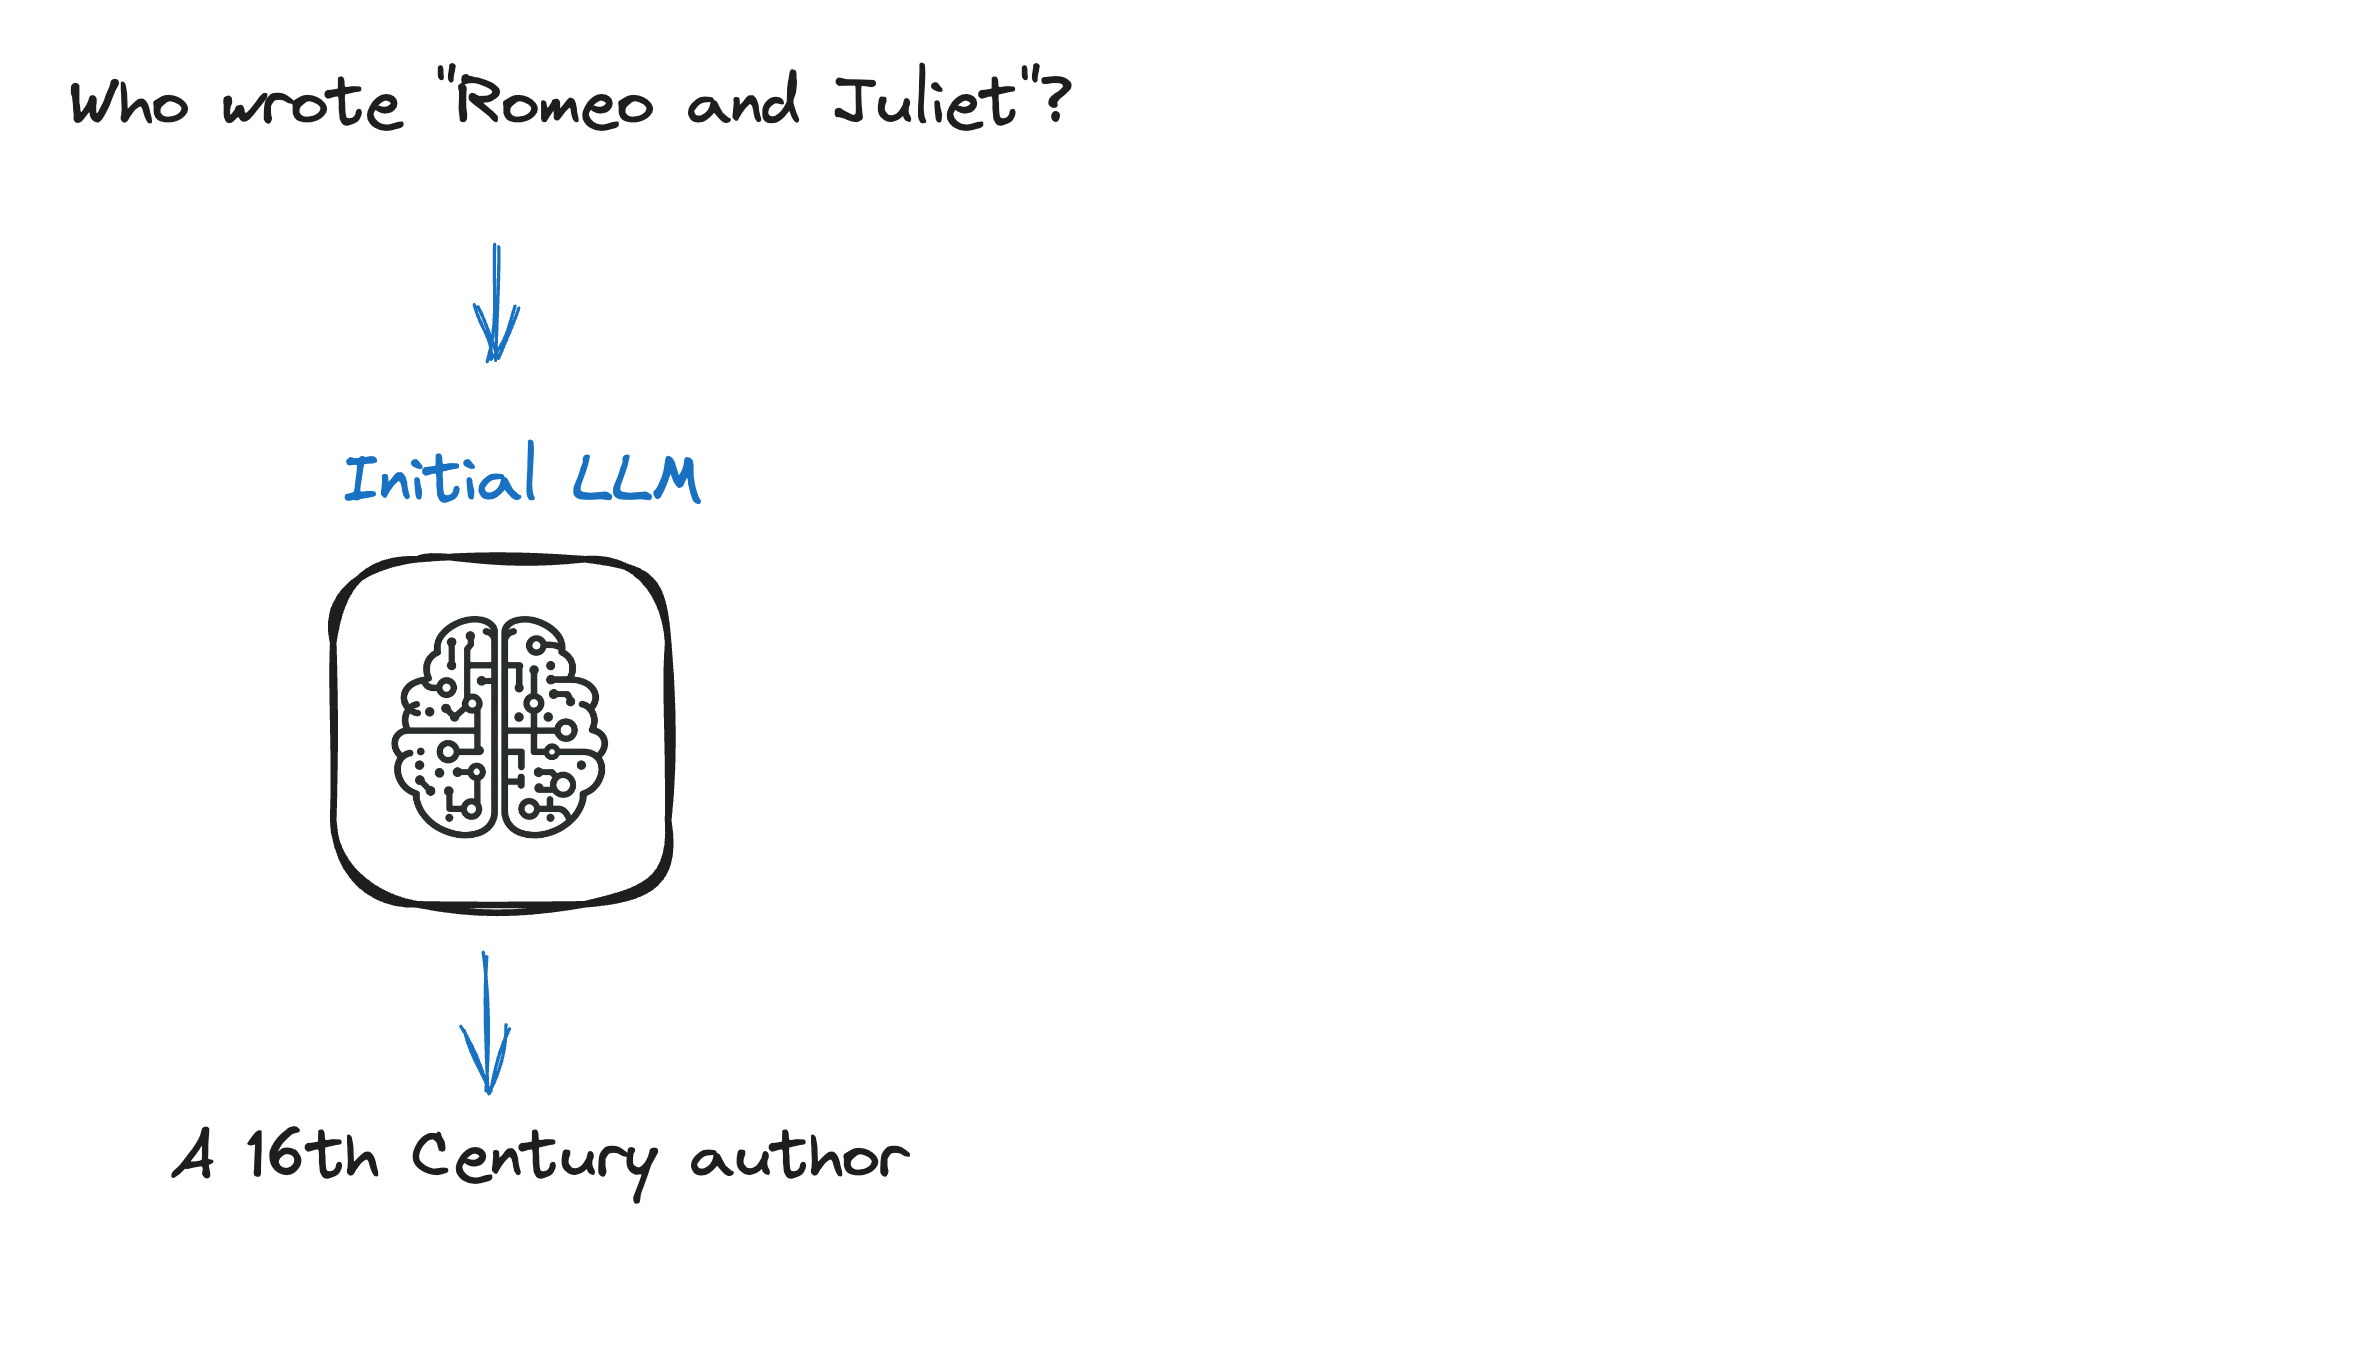
Un prompt che chiede "Who wrote Romeo and Juliet" con un LLM che risponde: "a 16th Century author".

Reinforcement Learning from Human Feedback (RLHF)

L'intero processo RLHF

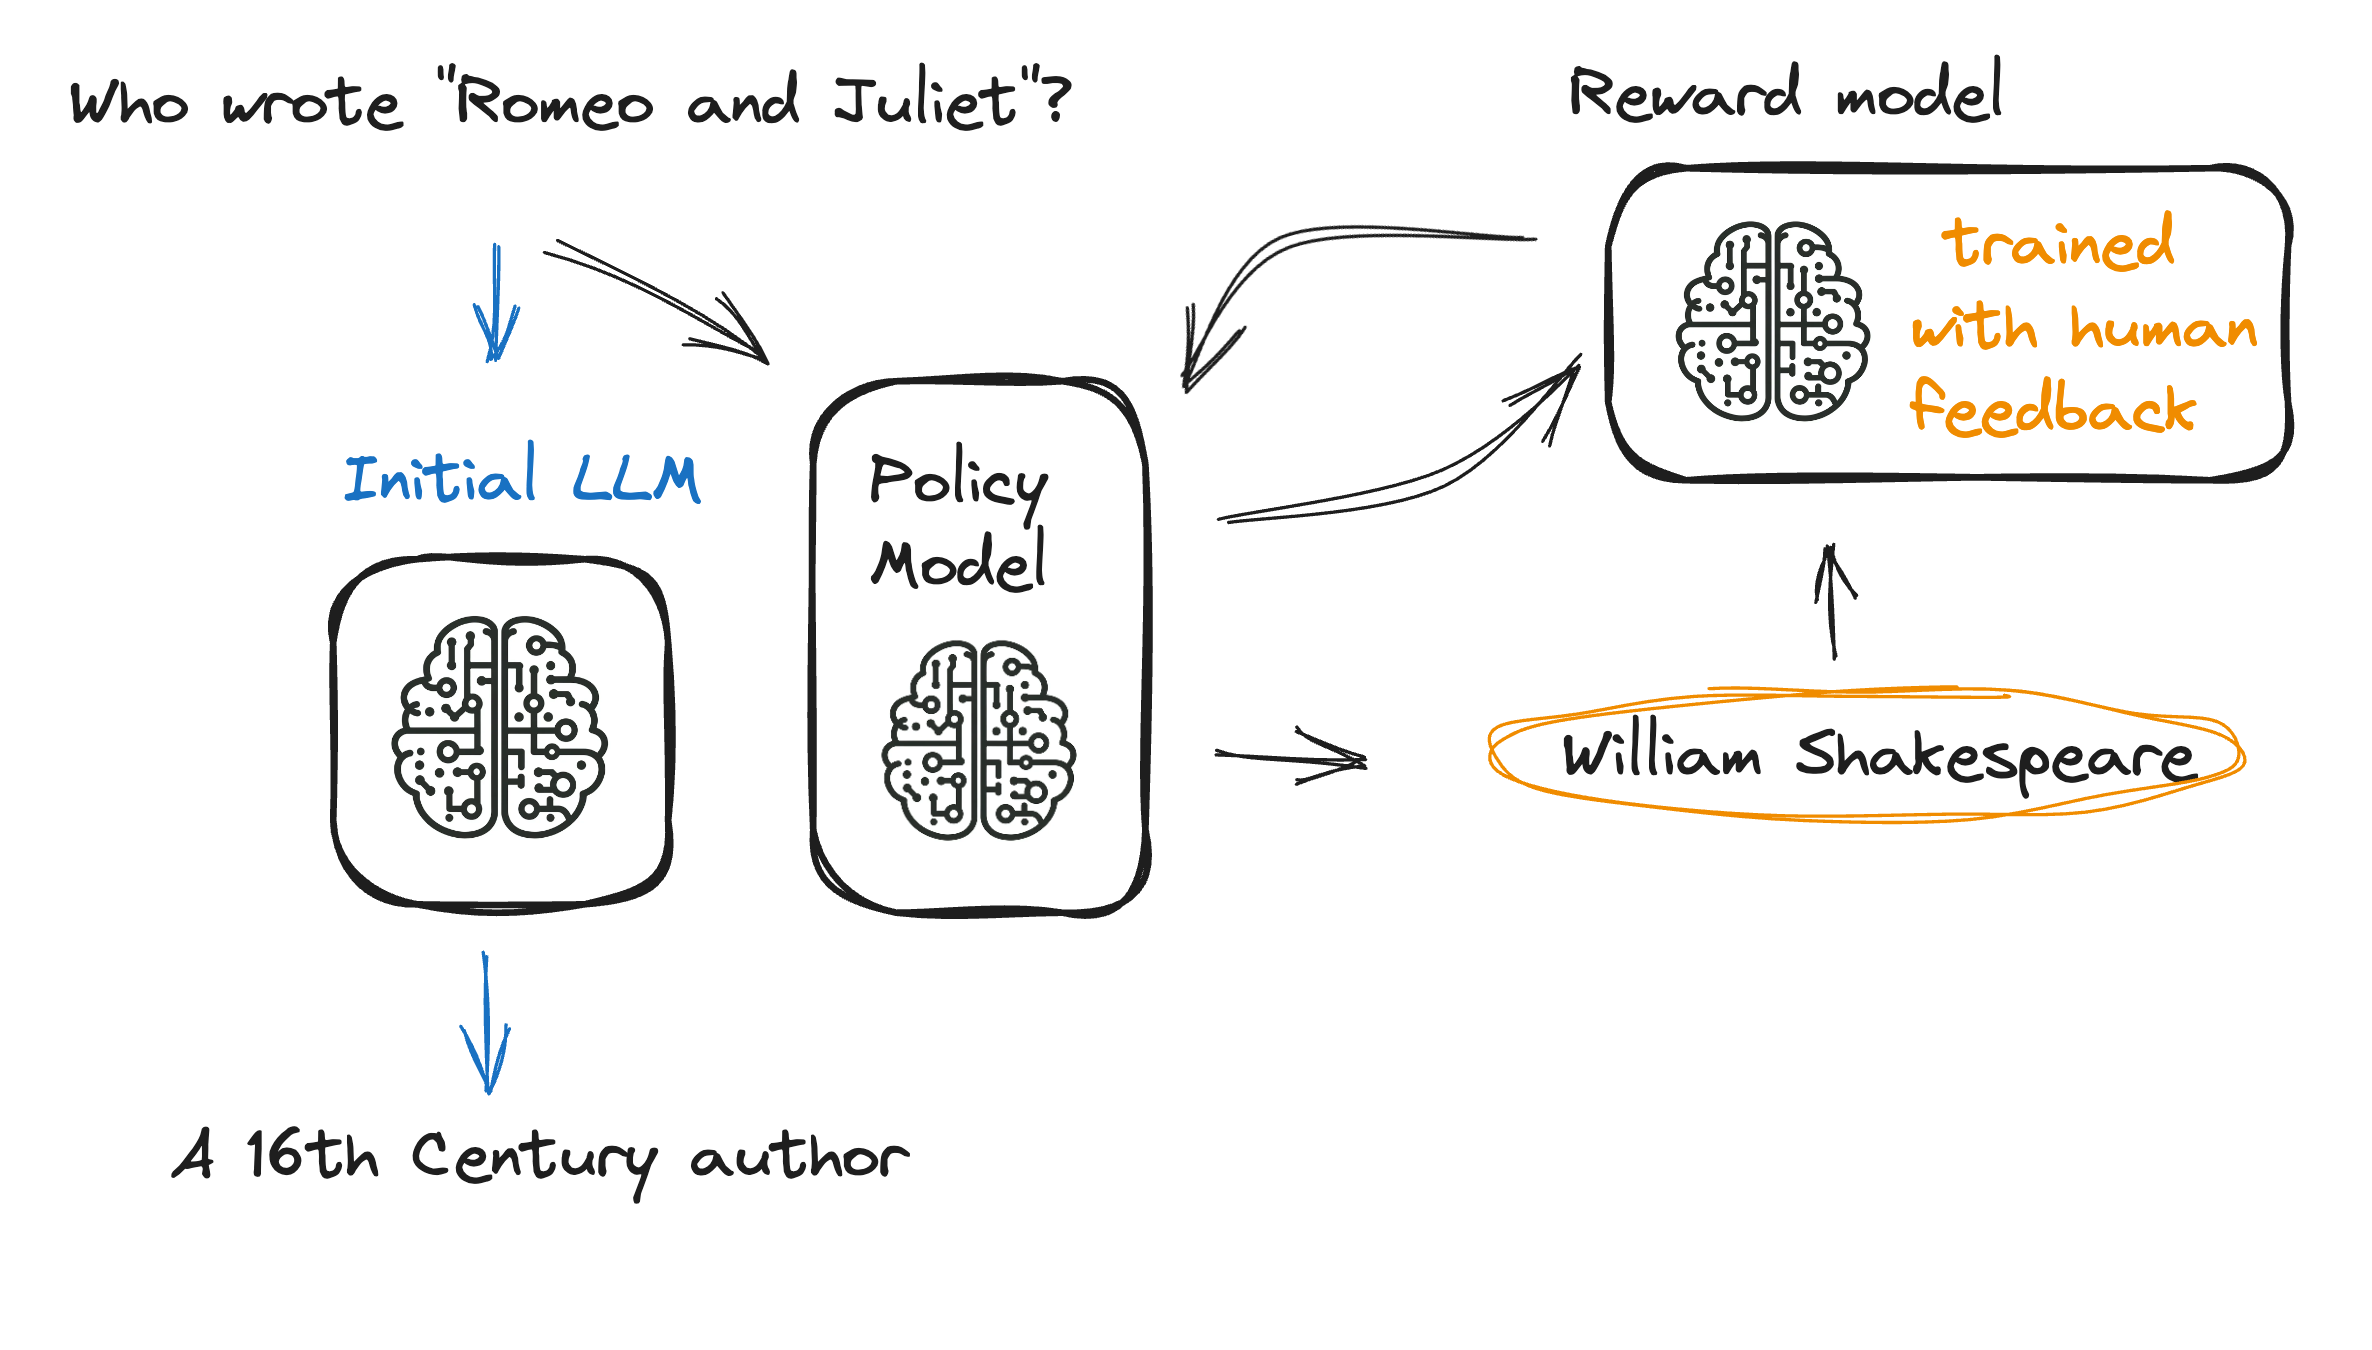
Un prompt che chiede "Who wrote Romeo and Juliet" con un LLM che risponde: "a 16th Century author", e un modello aggiuntivo, un policy model, che riceve il prompt.

Reinforcement Learning from Human Feedback (RLHF)

L'intero processo RLHF

Un prompt che chiede "Who wrote Romeo and Juliet" con un LLM che risponde: "a 16th Century author", e un modello aggiuntivo, un policy model, che riceve il prompt ed è addestrato usando un reward model.

Reinforcement Learning from Human Feedback (RLHF)

L'intero processo RLHF

Un prompt che chiede "Who wrote Romeo and Juliet" con un LLM che risponde: "a 16th Century author", e un modello aggiuntivo, un policy model, addestrato usando un reward model, che dà la risposta "William Shakespeare".

Reinforcement Learning from Human Feedback (RLHF)

L'intero processo RLHF

Un prompt che chiede "Who wrote Romeo and Juliet" con un LLM che risponde: "a 16th Century author", e un modello aggiuntivo, un policy model, addestrato usando un reward model, che dà la risposta "William Shakespeare", e un confronto tra i due risultati.

Reinforcement Learning from Human Feedback (RLHF)

Interagire con LLM ottimizzati con RLHF

  • Modelli RLHF pre-addestrati su Hugging Face 🤗
from transformers import pipeline

text_generator = pipeline('text-generation', model='lvwerra/gpt2-imdb-pos-v2')
# Provide a review prompt review_prompt = "This is definitely a" # Generate the continuation output = text_generator(review_prompt, max_length=50) #Print the generated text print(output[0]['generated_text'])
This is definitely a crucial improvement.
Reinforcement Learning from Human Feedback (RLHF)

Interagire con LLM ottimizzati con RLHF

from transformers import pipeline, AutoModelForSequenceClassification, AutoTokenizer


# Instantiate the pre-trained model and tokenizer model = AutoModelForSequenceClassification.from_pretrained("lvwerra/distilbert-imdb") tokenizer = AutoTokenizer.from_pretrained("lvwerra/distilbert-imdb")
# Use pipeline to create the sentiment analyzer sentiment_analyzer = pipeline('sentiment-analysis', model=model, tokenizer=tokenizer) # Pass the text to the sentiment analyzer and print the result sentiment = sentiment_analyzer("This is definitely a crucial improvement.")
print(f"Sentiment Analysis Result: {sentiment}")
positive
Reinforcement Learning from Human Feedback (RLHF)

Esercitiamoci!

Reinforcement Learning from Human Feedback (RLHF)

Preparing Video For Download...