Valutare i modelli RLHF

Reinforcement Learning from Human Feedback (RLHF)

Mina Parham

AI Engineer

Metriche di automazione


  • Task di classificazione: Accuracy, F1 score
classification_results.head(3)
| ID | Feedback_Text                         | True_Category | Predicted_Category |
|----|---------------------------------------|---------------|--------------------|
| 1  | "Arrived on time and works great."    | Positive      | Positive           |
| 2  | "I had issues with customer service." | Negative      | Neutral            |
| 3  | "The website is easy to navigate."    | Positive      | Positive           |
Reinforcement Learning from Human Feedback (RLHF)

Metriche di automazione


  • Generazione di testo, riassunto: ROUGE, BLEU
text_generation.head(3)
| ID | Prompt               | True_Completion  | Pred_Completion   |
|----|----------------------|------------------|-------------------|
| 1  | "Customer service"   | "can help you."  | "will assist."    |
| 2  | "To get a refund,"   | "contact us."    | "reach out."      |
| 3  | "Support team is"    | "here 24/7."     | "available 24/7." |
Reinforcement Learning from Human Feedback (RLHF)

Metriche di automazione


Affermazione di riferimento:

  • RLHF migliora l'allineamento del modello ai valori umani.


ROUGE score: 0.83


Affermazione da confrontare:

  • RLHF allinea i modelli ai valori umani.
Reinforcement Learning from Human Feedback (RLHF)

Curve degli artifact

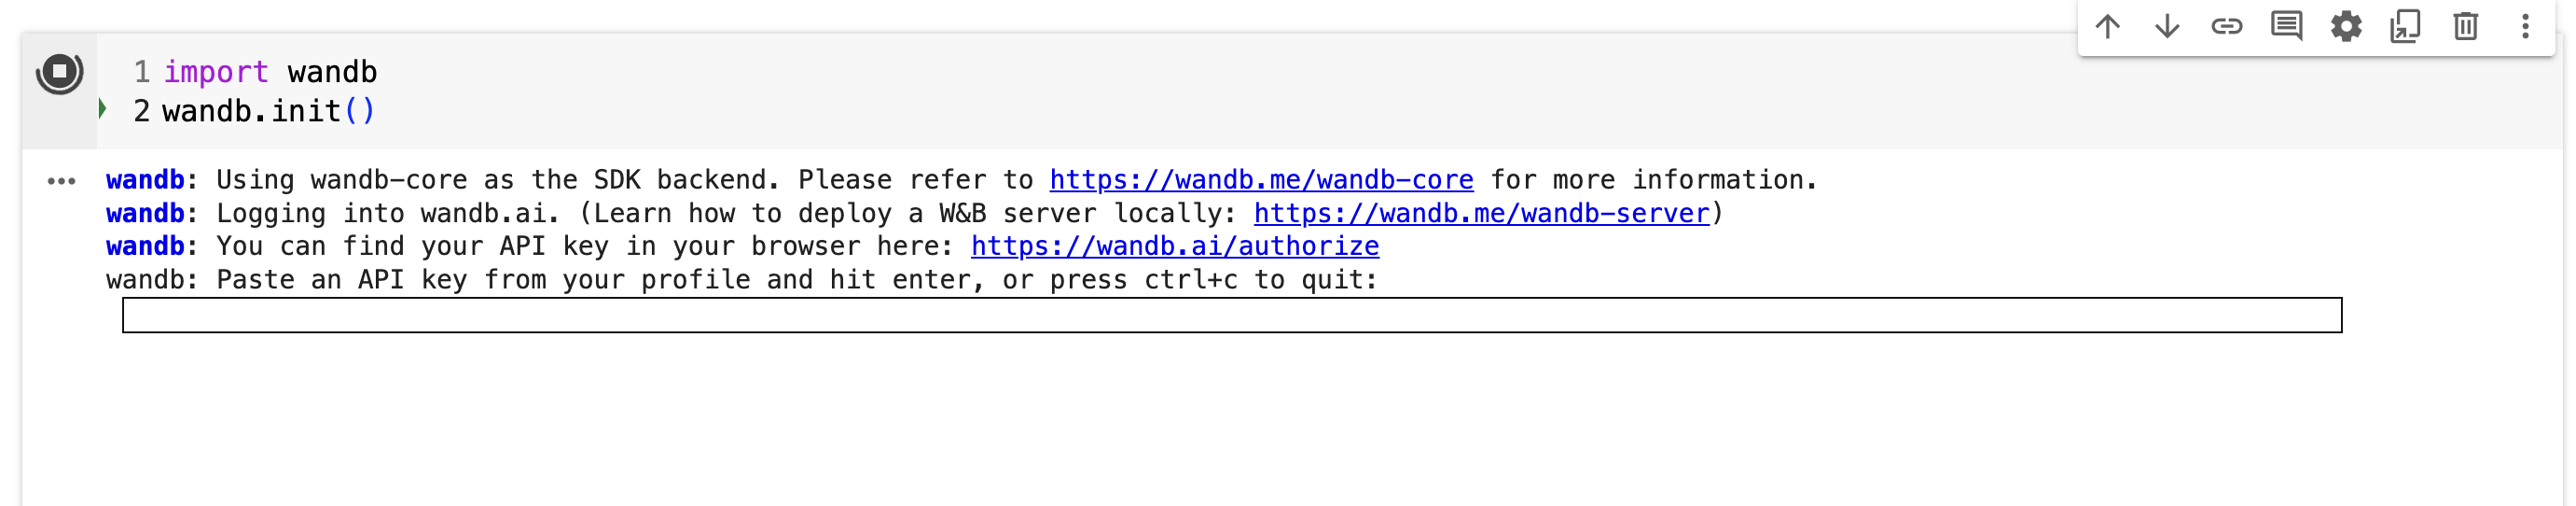
config = PPOConfig(
    model_name="lvwerra/gpt2-imdb",learning_rate=1.41e-5, log_with="wandb")
import wandb
wandb.init()

Uno screenshot dell'output del terminale in Weights and Biases.

Reinforcement Learning from Human Feedback (RLHF)

Curve degli artifact

  • La ricompensa aumenta man mano che il modello impara.
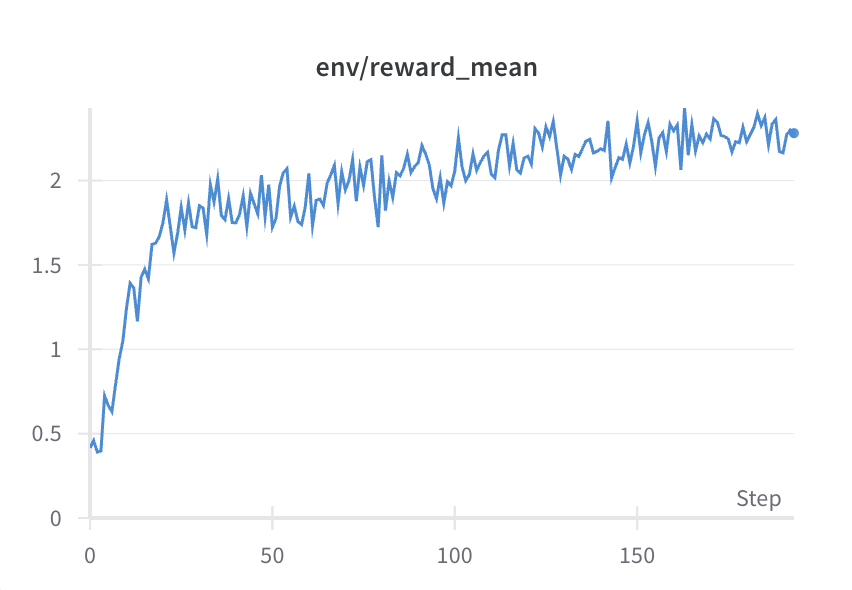
Una curva con trend crescente della ricompensa, segno che il modello migliora.

  • La curva KL dovrebbe crescere gradualmente.
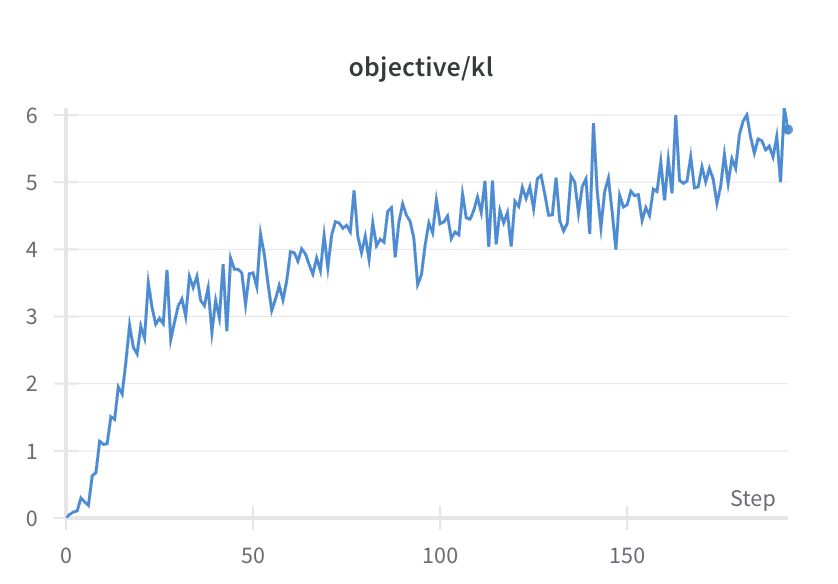
Una curva con aumento graduale della perdita KL.

Reinforcement Learning from Human Feedback (RLHF)

Valutazione centrata sull'essere umano

  • Valutazione umana: giudizi soggettivi o profonda comprensione del contesto
Una valutatrice umana al laptop.

  • Valutazione con modelli: scalabilità e coerenza
Un robot con fumetti che rappresentano un valutatore modello.

Reinforcement Learning from Human Feedback (RLHF)

Esercitiamoci!

Reinforcement Learning from Human Feedback (RLHF)

Preparing Video For Download...