Operazioni RDD in PySpark
Fondamenti di Big Data con PySpark

Upendra Devisetty
Science Analyst, CyVerse
Panoramica delle operazioni PySpark
- Le trasformazioni creano nuovi RDD
- Le azioni eseguono calcoli sugli RDD
Trasformazioni RDD
- Le trasformazioni seguono la valutazione lazy
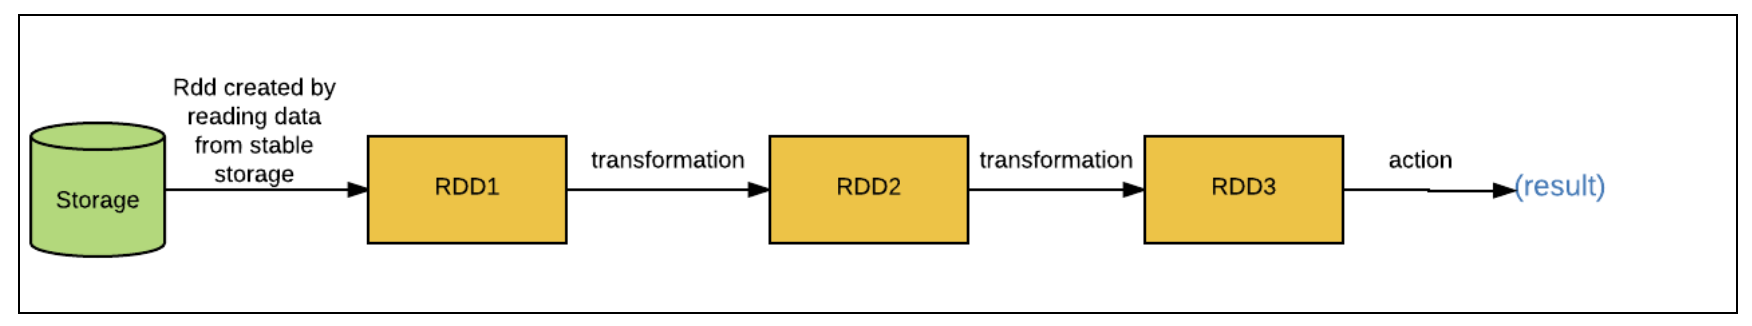
Trasformazioni RDD di base
map(),filter(),flatMap()eunion()
Trasformazione map()
- La trasformazione map() applica una funzione a tutti gli elementi dell'RDD
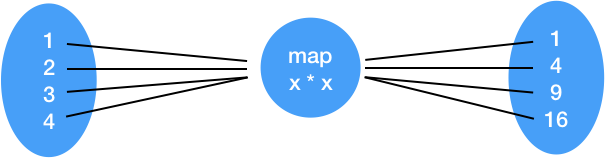
RDD = sc.parallelize([1,2,3,4])
RDD_map = RDD.map(lambda x: x * x)
Trasformazione filter()
- La trasformazione filter restituisce un nuovo RDD con solo gli elementi che soddisfano la condizione
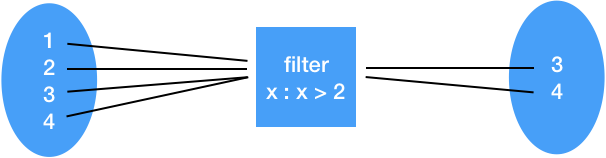
RDD = sc.parallelize([1,2,3,4])
RDD_filter = RDD.filter(lambda x: x > 2)
Trasformazione flatMap()
- La trasformazione flatMap() restituisce più valori per ogni elemento dell'RDD originale
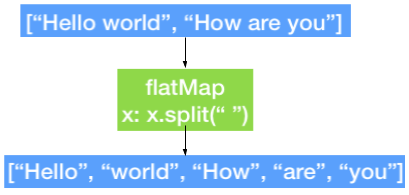
RDD = sc.parallelize(["hello world", "how are you"])
RDD_flatmap = RDD.flatMap(lambda x: x.split(" "))
Trasformazione union()
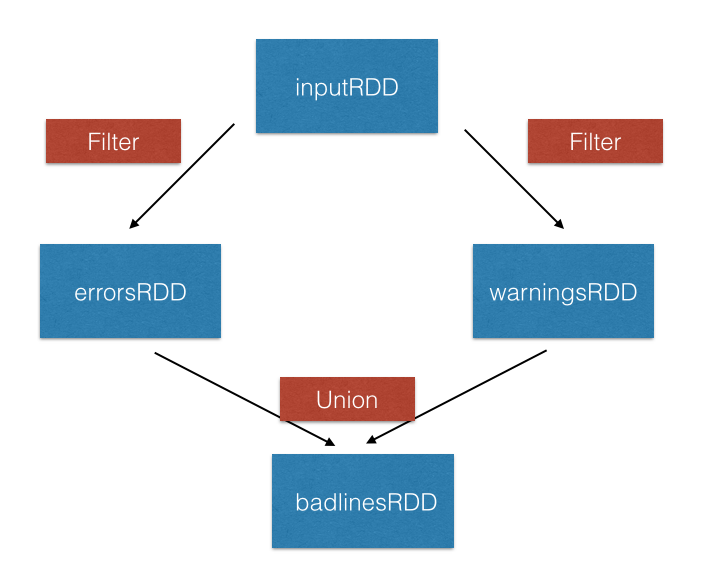
inputRDD = sc.textFile("logs.txt")
errorRDD = inputRDD.filter(lambda x: "error" in x.split())
warningsRDD = inputRDD.filter(lambda x: "warnings" in x.split())
combinedRDD = errorRDD.union(warningsRDD)

