Phân tích cảm xúc với Python
Violeta Misheva
Data Scientist
Mô tả tần suất xuất hiện của từ trong một tài liệu hoặc tập tài liệu (corpus)
Xây dựng từ vựng và đo lường mức độ xuất hiện của chúng
Đây là cuốn sách hay nhất. Tôi rất thích và cực kỳ khuyến nghị!!!
{'This': 1, 'is': 1, 'the': 2 , 'best': 1 , 'book': 2,
'ever': 1, 'I':1 , 'loved':1 , 'and': 1  , 'highly': 1,
'recommend': 1 , 'it': 1 }
import pandas as pd
from sklearn.feature_extraction.text import CountVectorizer
vect = CountVectorizer(max_features=1000)
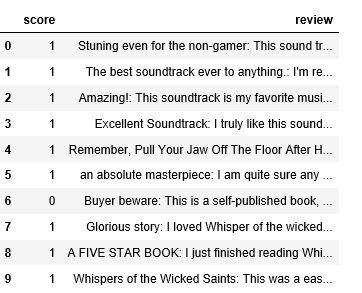
vect.fit(data.review)
X = vect.transform(data.review)
X
<10000x1000 sparse matrix of type '<class 'numpy.int64'>'
  with 406668 stored elements in Compressed Sparse Row format>
# Chuyển thành mảng
my_array = X.toarray()
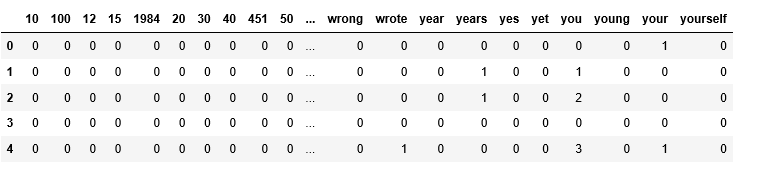
# Chuyển lại thành DataFrame, gán tên cột
X_df = pd.DataFrame(my_array, columns=vect.get_feature_names())