Lấy thêm dữ liệu

Feature Engineering với PySpark

John Hogue

Lead Data Scientist, General Mills

Suy nghĩ về bộ dữ liệu bên ngoài

ƯU ĐIỂM

  • Thêm biến dự báo quan trọng
  • Bổ sung/thay thế giá trị
  • Rẻ hoặc dễ lấy

Kết hợp dữ liệu

NHƯỢC ĐIỂM

  • Có thể làm chậm phân tích
  • Dễ gây rò rỉ dữ liệu
  • Phải am hiểu bộ dữ liệu

Trách nhiệm

Feature Engineering với PySpark

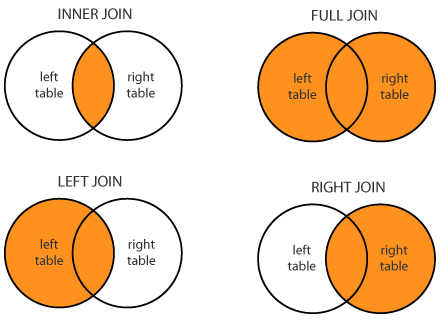
Về các phép join

Định hướng join dữ liệu

  • Trái: bộ dữ liệu gốc
  • Phải: bộ dữ liệu cần ghép thêm

SQL Joins

Feature Engineering với PySpark

Join DataFrame trong PySpark

DataFrame.join(

other, # DataFrame khác để hợp nhất
on=None, # Khóa để join
how=None) # Kiểu join (mặc định 'inner')
Feature Engineering với PySpark

Ví dụ join trong PySpark

# Inspect dataframe head
hdf.show(2)
+----------+--------------------+
|        dt|                  nm|
+----------+--------------------+
|2012-01-02|        New Year Day|
|2012-01-16|Martin Luther Kin...|
+----------+--------------------+
only showing top 2 rows
# Specify join conditon
cond = [df['OFFMARKETDATE'] == hdf['dt']]

# Join two hdf onto df df = df.join(hdf, on=cond, 'left')
# How many sales occurred on bank holidays? df.where(~df['nm'].isNull()).count()
0
Feature Engineering với PySpark

Join trong SparkSQL

  • Áp dụng SQL cho dataframe
# Register the dataframe as a temp table
df.createOrReplaceTempView("df")
hdf.createOrReplaceTempView("hdf")
# Write a SQL Statement
sql_df = spark.sql("""
                      SELECT 
                        *
                      FROM df
                      LEFT JOIN hdf
                      ON df.OFFMARKETDATE = hdf.dt
                   """)
Feature Engineering với PySpark

Hãy join một số dữ liệu!

Feature Engineering với PySpark

Preparing Video For Download...