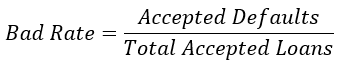Python을 활용한 신용 위험 모델링
Michael Crabtree
Data Scientist, Ford Motor Company
prob_default 값 범위에 대한 임계값을 설정했습니다loan_status를 변경했습니다preds_df['loan_status'] = preds_df['prob_default'].apply(lambda x: 1 if x > 0.4 else 0)
| 대출 | prob_default | threshold | loan_status |
|---|---|---|---|
| 1 | 0.25 | 0.4 | 0 |
| 2 | 0.42 | 0.4 | 1 |
| 3 | 0.75 | 0.4 | 1 |
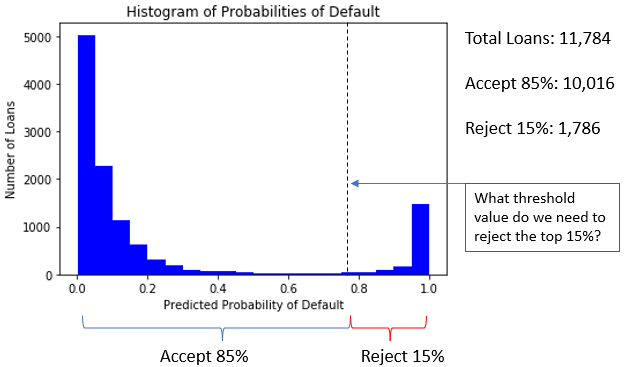
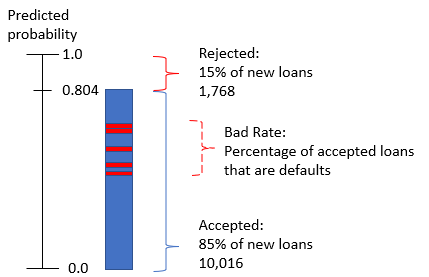
prob_default 값이 가장 낮은 대출의 85%를 승인합니다import numpy as np
# Compute the threshold for 85% acceptance rate
threshold = np.quantile(prob_default, 0.85)
0.804
| 대출 | prob_default |
임계값 | 예측 loan_status |
승인 또는 거부 |
|---|---|---|---|---|
| 1 | 0.65 | 0.804 | 0 | 승인 |
| 2 | 0.85 | 0.804 | 1 | 거부 |
loan_status 값을 다시 할당합니다# Compute the quantile on the probabilities of default
preds_df['loan_status'] = preds_df['prob_default'].apply(lambda x: 1 if x > 0.804 else 0)
prob_default 값을 가진 대출입니다#Calculate the bad rate
np.sum(accepted_loans['true_loan_status']) / accepted_loans['true_loan_status'].count()
0이고 부도가 1이면 sum()은 부도 건수입니다.count()는 데이터 프레임의 행 수와 같습니다Python을 활용한 신용 위험 모델링