부도 확률 예측하기

Python을 활용한 신용 위험 모델링

Michael Crabtree

Data Scientist, Ford Motor Company

로지스틱 회귀 계수

# Model Intercept
array([-3.30582292e-10])
# Coefficients for ['loan_int_rate','person_emp_length','person_income']
array([[ 1.28517496e-09, -2.27622202e-09, -2.17211991e-05]])
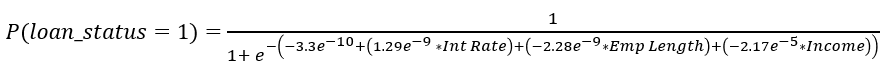
로지스틱 회귀를 이용한 부도 확률 공식

# Calculating probability of default
int_coef_sum = -3.3e-10 +
    (1.29e-09 * loan_int_rate) + (-2.28e-09 * person_emp_length) + (-2.17e-05 * person_income)
prob_default = 1 / (1 + np.exp(-int_coef_sum))
prob_nondefault = 1 - (1 / (1 + np.exp(-int_coef_sum)))
Python을 활용한 신용 위험 모델링

계수 해석하기

# Intercept
intercept = -1.02
# Coefficient for employment length
person_emp_length_coef = -0.056
  • person_emp_length이 1년 증가할 때마다 부도 가능성이 낮아집니다
Python을 활용한 신용 위험 모델링

계수 해석하기

# Intercept
intercept = -1.02
# Coefficient for employment length
person_emp_length_coef = -0.056
  • person_emp_length이 1년 증가할 때마다 부도 가능성이 낮아집니다
절편 person_emp_length 값 * 계수 부도 확률
-1.02 10 (10 * -0.06) .17
-1.02 11 (11 * -0.06) .16
-1.02 12 (12 * -0.06) .15
Python을 활용한 신용 위험 모델링

비숫자형 열 사용하기

  • 숫자형: loan_int_rate, person_emp_length, person_income

  • 비숫자형:

    cr_loan_clean['loan_intent']
    
EDUCATION            
MEDICAL              
VENTURE              
PERSONAL             
DEBTCONSOLIDATION   
HOMEIMPROVEMENT
  • 처리하지 않으면 Python의 Machine Learning 모델에서 오류가 발생합니다
Python을 활용한 신용 위험 모델링

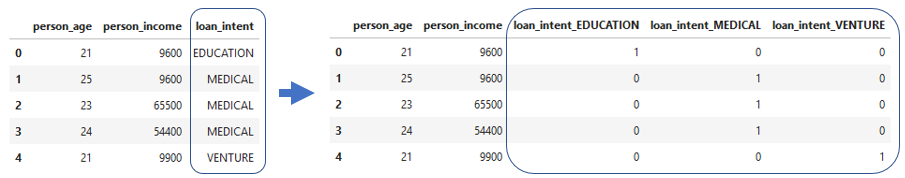
원-핫 인코딩

  • 문자열을 숫자로 표현

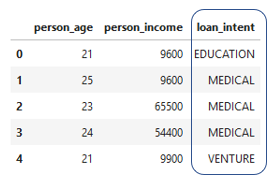
데이터 내 대출 목적 예시

Python을 활용한 신용 위험 모델링

원-핫 인코딩

  • 문자열을 숫자로 표현
  • 새 열 column_VALUE에 0 또는 1로 표시

대출 목적 열을 원-핫 인코딩한 예시

Python을 활용한 신용 위험 모델링

Get dummies

  • pandas의 get_dummies() 함수 활용
# Separate the numeric columns
cred_num = cr_loan.select_dtypes(exclude=['object'])
# Separate non-numeric columns
cred_cat = cr_loan.select_dtypes(include=['object'])
# One-hot encode the non-numeric columns only
cred_cat_onehot = pd.get_dummies(cred_cat)
# Union the numeric columns with the one-hot encoded columns
cr_loan = pd.concat([cred_num, cred_cat_onehot], axis=1)
Python을 활용한 신용 위험 모델링

확률로 미래 예측하기

  • scikit-learn의 .predict_proba() 메서드 사용
# Train the model
clf_logistic.fit(X_train, np.ravel(y_train))
# Predict using the model
clf_logistic.predict_proba(X_test)
  • 부도 확률 배열 생성
# Probabilities: [[non-default, default]]
array([[0.55, 0.45]])
Python을 활용한 신용 위험 모델링

연습해 봅시다!

Python을 활용한 신용 위험 모델링

Preparing Video For Download...