그리드 vs 랜덤 서치
R에서 하이퍼파라미터 튜닝

Dr. Shirin Elsinghorst
Senior Data Scientist
그리드 서치 계속
man_grid <- expand.grid(n.trees = c(100, 200, 250), interaction.depth = c(1, 4, 6), shrinkage = 0.1, n.minobsinnode = 10)fitControl <- trainControl(method = "repeatedcv", number = 3, repeats = 5, search = "grid")tic() set.seed(42) gbm_model_voters_grid <- train(turnout16_2016 ~ ., data = voters_train_data, method = "gbm", trControl = fitControl, verbose= FALSE, tuneGrid = man_grid) toc()
85.745 sec elapsed
하이퍼파라미터 범위로 그리드 서치
big_grid <-  expand.grid(n.trees = seq(from = 10, to = 300, by = 50),
                         interaction.depth = seq(from = 1, to = 10,
                                                 length.out = 6),
                         shrinkage = 0.1,
                         n.minobsinnode = 10)
big_grid
   n.trees interaction.depth shrinkage n.minobsinnode
1       10               1.0       0.1             10
2       60               1.0       0.1             10
3      110               1.0       0.1             10
4      160               1.0       0.1             10
5      210               1.0       0.1             10
6      260               1.0       0.1             10
...
36     260              10.0       0.1             10
하이퍼파라미터 조합이 많은 그리드 서치
big_grid <- expand.grid(n.trees = seq(from = 10, to = 300, by = 50), interaction.depth = seq(from = 1, to = 10, length.out = 6), shrinkage = 0.1, n.minobsinnode = 10)fitControl <- trainControl(method = "repeatedcv", number = 3, repeats = 5, search = "grid")tic() set.seed(42) gbm_model_voters_big_grid <- train(turnout16_2016 ~ ., data = voters_train_data, method = "gbm", trControl = fitControl, verbose = FALSE, tuneGrid = big_grid) toc()
240.698 sec elapsed
카르테시안 그리드 vs 랜덤 서치
ggplot(gbm_model_voters_big_grid)
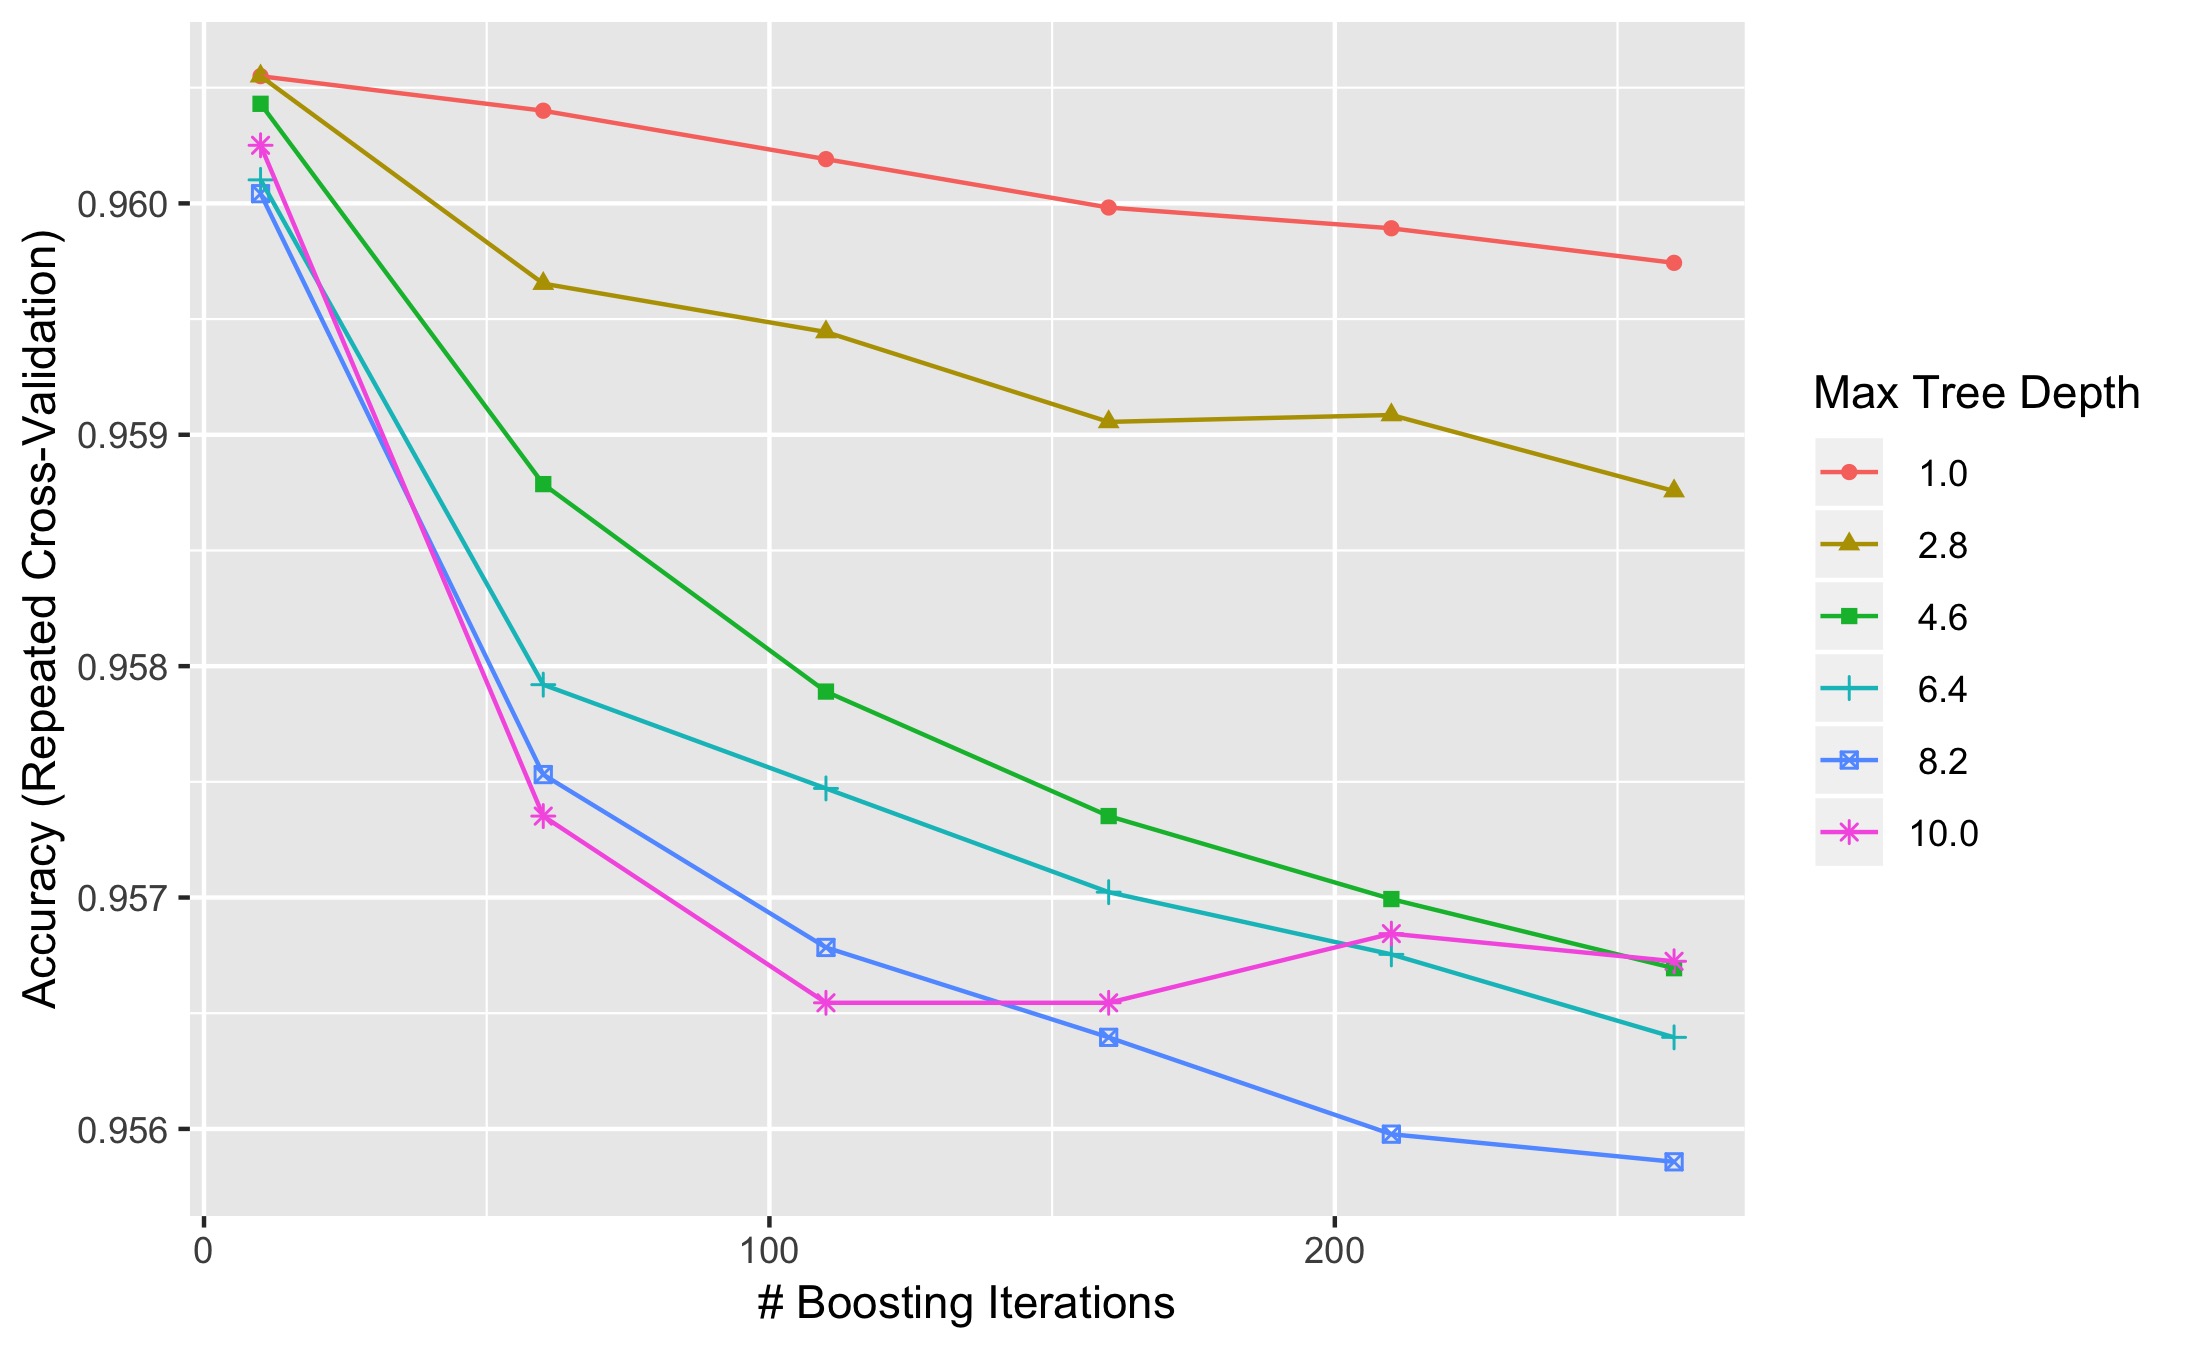
그리드 서치는 매우 빠르게 느려지고 계산 비용이 커질 수 있습니다!
따라서 실제로는 랜덤 서치를 자주 사용합니다.
caret에서 랜덤 서치
# trainControl 함수에서 랜덤 서치 정의
library(caret)
fitControl <- trainControl(method = "repeatedcv", number = 3, repeats = 5, search = "random")
# tuneLength 인자 설정
tic()
set.seed(42)
gbm_model_voters_random <- train(turnout16_2016 ~ .,
                   data = voters_train_data,
                   method = "gbm",
                   trControl = fitControl,
                   verbose = FALSE,
                   tuneLength = 5)
toc()
46.432 sec elapsed
caret에서 랜덤 서치
gbm_model_voters_random
Stochastic Gradient Boosting
...
Resampling results across tuning parameters:
  shrinkage   interaction.depth  n.minobsinnode  n.trees  Accuracy   Kappa
  0.08841129   4                  6              4396     0.9670737  -0.008533125
  0.09255042   2                  7               540     0.9630635  -0.013291683
  0.14484962   3                 21              3154     0.9570179  -0.013970255
  0.34935098  10                 10              2566     0.9610734  -0.015726813
  0.43341085   1                 13              2094     0.9460727  -0.024791056
Accuracy was used to select the optimal model using the largest value.
The final values used for the model were n.trees = 4396,
interaction.depth = 4, shrinkage = 0.08841129 and n.minobsinnode = 6.
- 주의:
caret에서는 랜덤 서치를 그리드 서치와 함께 사용할 수 없습니다!
코딩해 봅시다!
R에서 하이퍼파라미터 튜닝

