Pythonによるデータクリーニング
Adel Nehme
VP of AI Curriculum, DataCamp

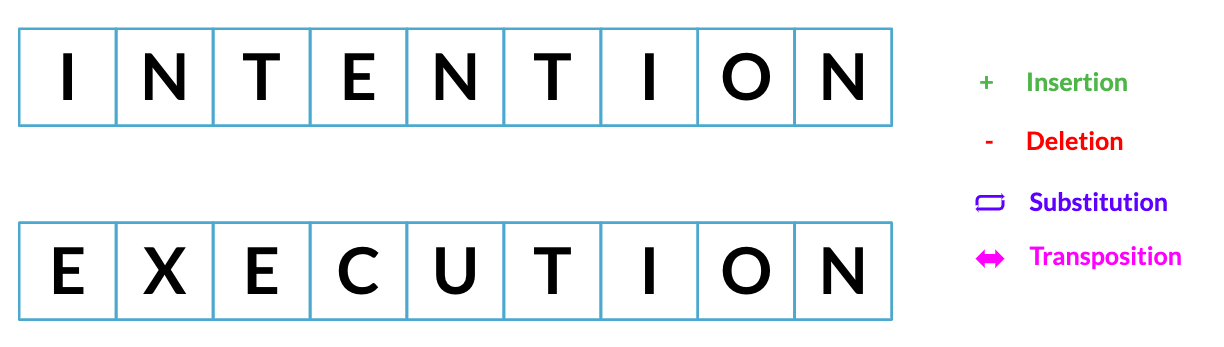
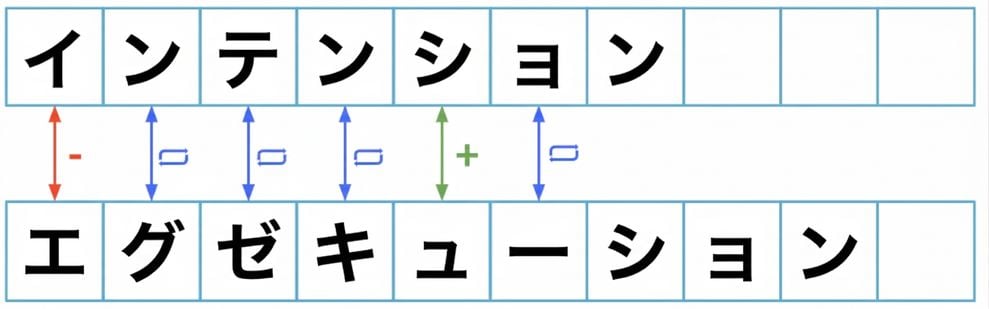
ある文字列から別の文字列へ移行するために必要な、可能な限り少ないステップ数

ある文字列から別の文字列へ移行するために必要な最小限の手順数


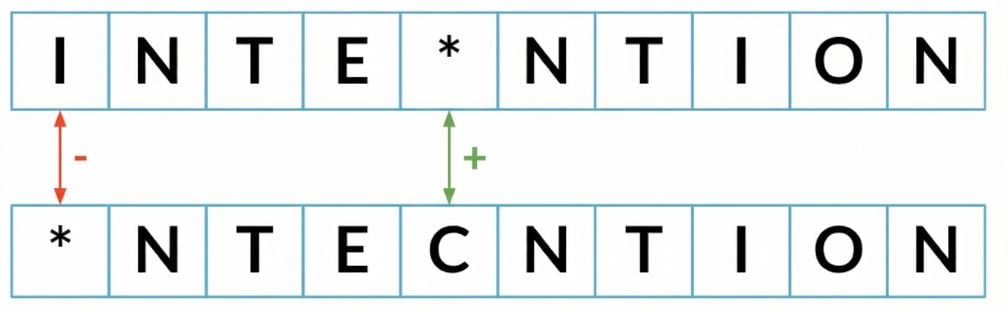
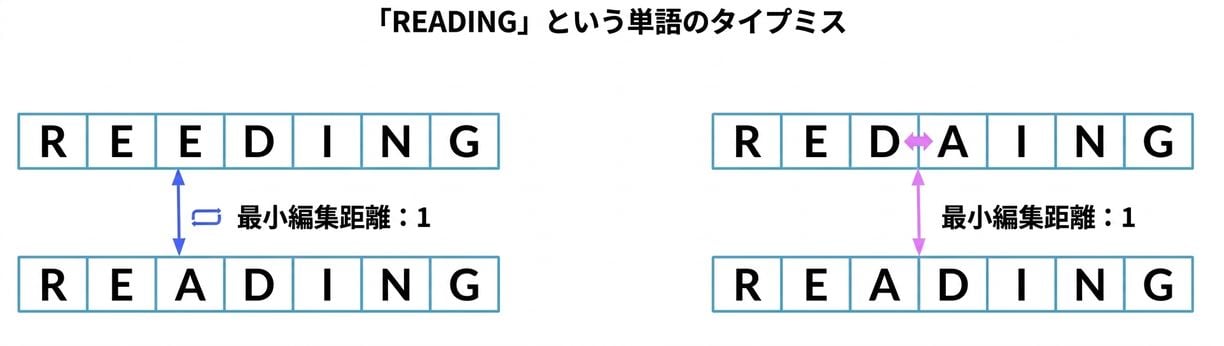
これまでの最小編集距離 2

最小編集距離: 5

| アルゴリズム | 操作 |
|---|---|
| Damerau-Levenshtein | 挿入、置換、削除、転置 |
| Levenshtein | 挿入、置換、削除 |
| ハミング | 置換のみ |
| Jaro距離 | 転置のみ |
| ... | ... |
利用可能なパッケージ: nltk, thefuzz, textdistance ..
| アルゴリズム | 操作 |
|---|---|
| Damerau-Levenshtein | 挿入、置換、削除、転置 |
| レーベンシュタイン | 挿入、置換、削除 |
| ハミング | 置換のみ |
| Jaro距離 | 転置のみ |
| ... | ... |
可能なパッケージ: thefuzz
# Lets us compare between two strings from thefuzz import fuzz# Compare reeding vs reading fuzz.WRatio('Reeding', 'Reading')
86
# Partial string comparison
fuzz.WRatio('Houston Rockets', 'Rockets')
90
# Partial string comparison with different order
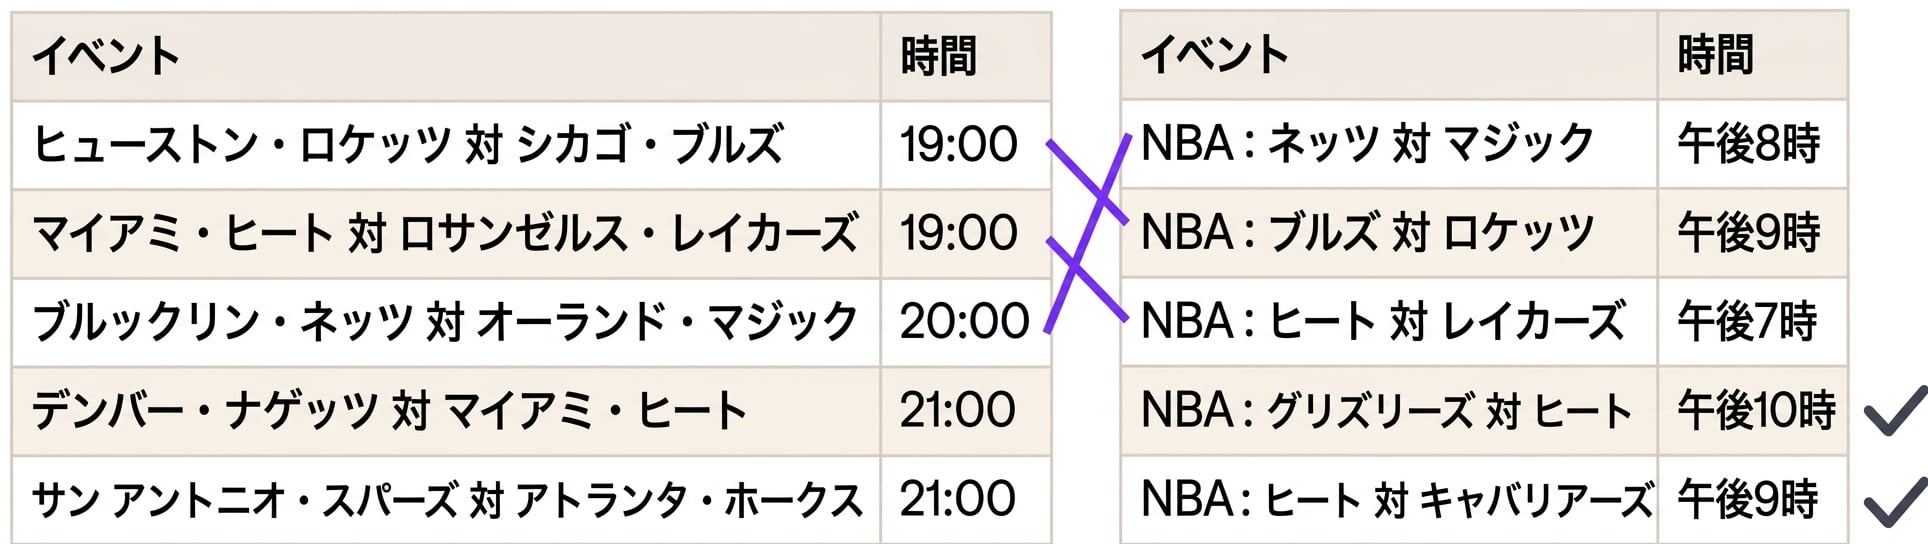
fuzz.WRatio('Houston Rockets vs Los Angeles Lakers', 'Lakers vs Rockets')
86
# Import process
from thefuzz import process
# Define string and array of possible matches
string = "Houston Rockets vs Los Angeles Lakers"
choices = pd.Series(['Rockets vs Lakers', 'Lakers vs Rockets',
'Houson vs Los Angeles', 'Heat vs Bulls'])
process.extract(string, choices, limit = 2)
[('Rockets vs Lakers', 86, 0), ('Lakers vs Rockets', 86, 1)]
第2章
.replace()を使用して"eur"を"Europe"にまとめます
バリエーションが多すぎたらどうなる?
"EU", "eur", "Europ", "Europa", "Erope", "Evropa"...
*文字列の類似度!
print(survey['state'].unique())
id state
0 California
1 Cali
2 Calefornia
3 Calefornie
4 Californie
5 Calfornia
6 Calefernia
7 New York
8 New York City
...
categories
state
0 California
1 New York
# For each correct category for state in categories['state']:# Find potential matches in states with typoes matches = process.extract(state, survey['state'], limit = survey.shape[0])# For each potential match match for potential_match in matches: # If high similarity score if potential_match[1] >= 80:# Replace typo with correct category survey.loc[survey['state'] == potential_match[0], 'state'] = state

Pythonによるデータクリーニング