言語タスクの指標: ROUGE、METEOR、EM

Python で学ぶ LLM の入門

Jasmin Ludolf

Senior Data Science Content Developer, DataCamp

LLMのタスクと評価指標
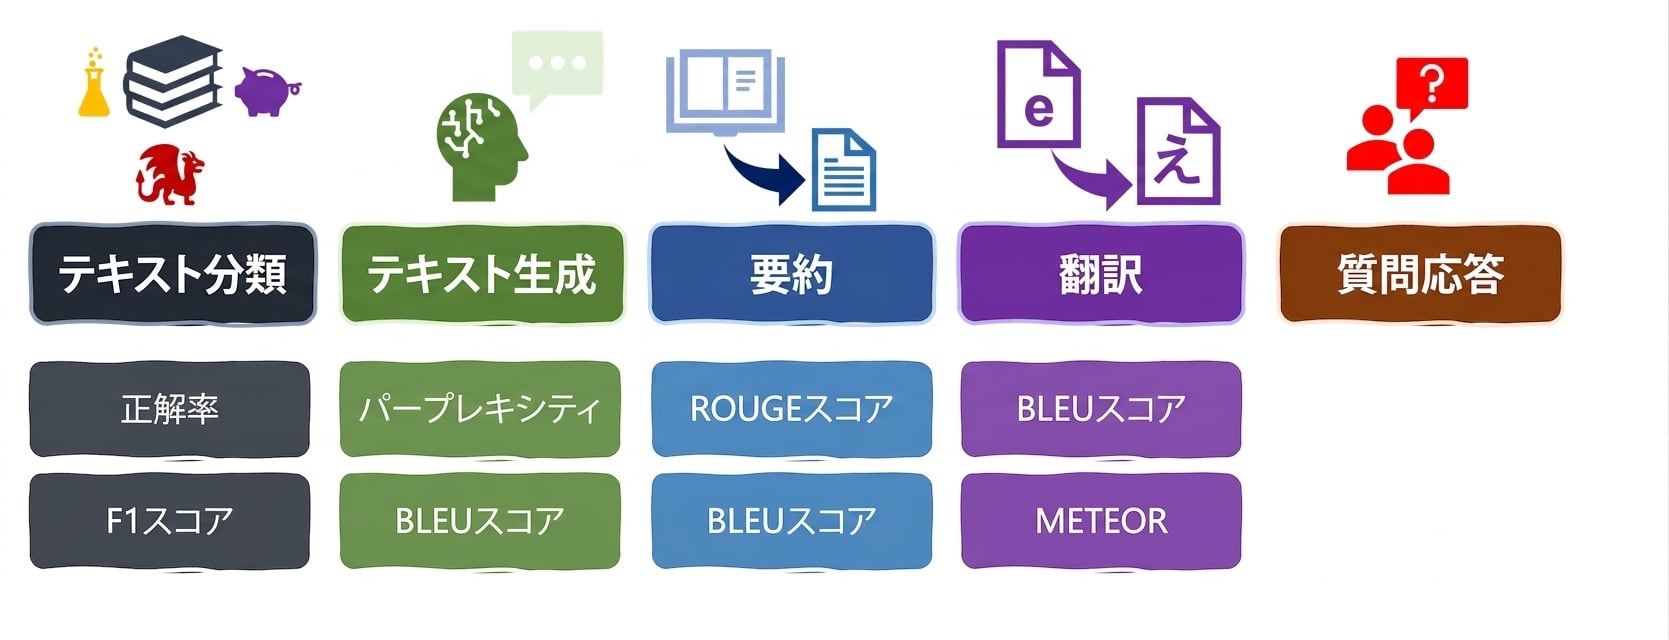
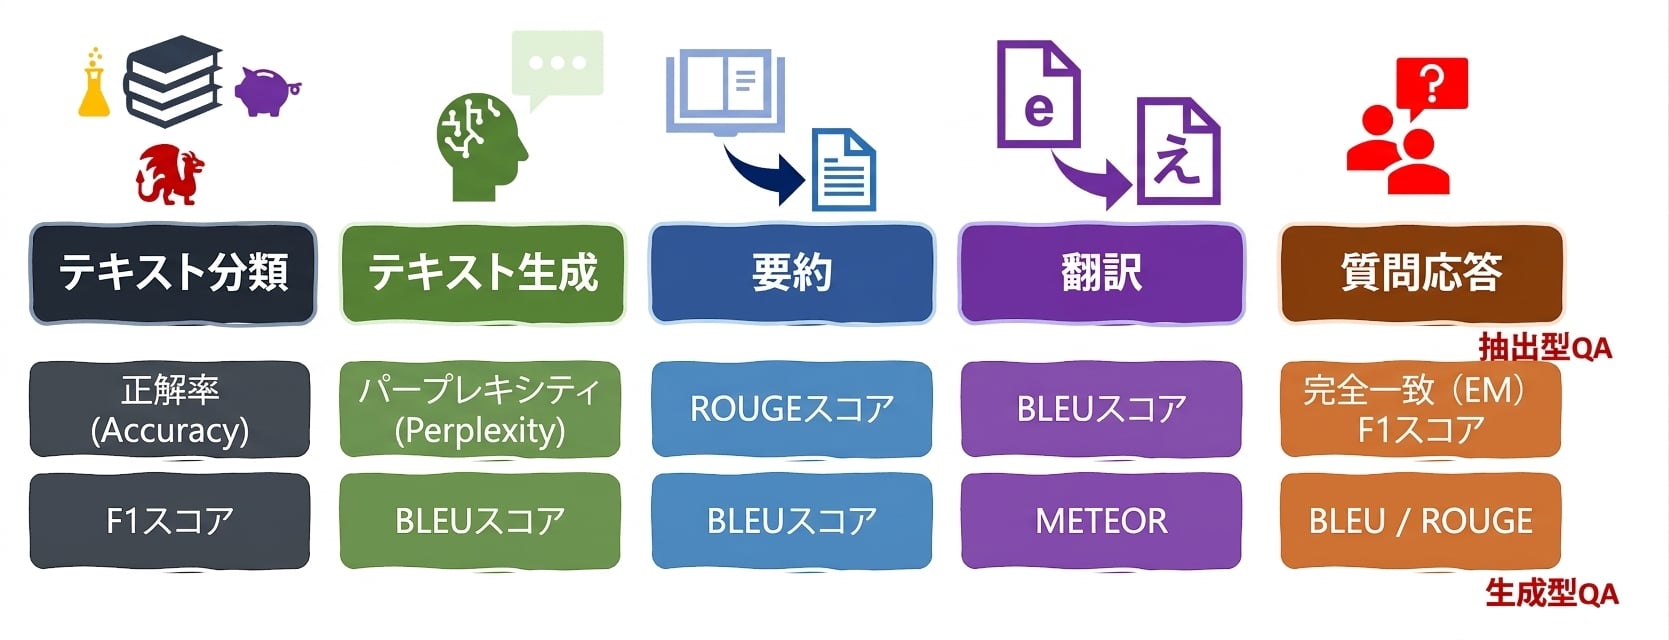
言語タスクの評価指標

Python で学ぶ LLM の入門

LLMのタスクと評価指標

言語タスクの評価指標

Python で学ぶ LLM の入門

LLMのタスクと評価指標

言語タスクの評価指標

Python で学ぶ LLM の入門

ROUGE

  • ROUGE: 生成された要約と参照要約との類似度指標
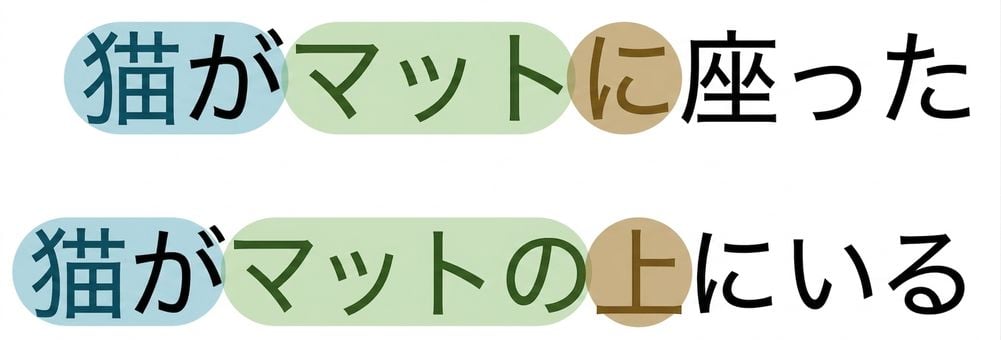
    • n-gramと重複を評価する
    • predictions: LLMの出力
    • references: 人間が提供した要約

マットに座った猫とマットの上にいる猫の比較

Python で学ぶ LLM の入門

ROUGE

rouge = evaluate.load("rouge")
predictions = ["""as we learn more about the frequency and size distribution of 
exoplanets, we are discovering that terrestrial planets are exceedingly common."""]
references = ["""The more we learn about the frequency and size distribution of 
exoplanets, the more confident we are that they are exceedingly common."""]

ROUGEスコア:

  • rouge1: ユニグラム重複度
  • rouge2: バイグラムの重複
  • rougeL: 長い重なり合う部分列
Python で学ぶ LLM の入門

ROUGEの出力

ROUGEスコア:

  • rouge1: ユニグラムの重複
  • rouge2: バイグラムの重複
  • rougeL: 長い重複部分列
  • 0-1のスコア:高いスコアほど類似度が高いことを示します
results = rouge.compute(predictions=predictions,
                         references=references)

print(results)
{'rouge1': 0.7441860465116279, 
'rouge2': 0.4878048780487805, 
'rougeL': 0.6976744186046512, 
'rougeLsum': 0.6976744186046512}
Python で学ぶ LLM の入門

METEOR

  • METEOR: 単語のバリエーション、類似した意味、語順など、より多くの言語的特徴
bleu = evaluate.load("bleu")
meteor = evaluate.load("meteor")


prediction = ["He thought it right and necessary to become a knight-errant, roaming the world in armor, seeking adventures and practicing the deeds he had read about in chivalric tales."] reference = ["He believed it was proper and essential to transform into a knight-errant, traveling the world in armor, pursuing adventures, and enacting the heroic deeds he had encountered in tales of chivalry."]
Python で学ぶ LLM の入門

METEOR

results_bleu = bleu.compute(predictions=pred, references=ref)
results_meteor = meteor.compute(predictions=pred, references=ref)
print("Bleu: ", results_bleu['bleu'])
print("Meteor: ", results_meteor['meteor'])
Bleu:  0.19088841781992524
Meteor:  0.5350702240481536
  • 0-1 スコア: 高いほど良い
Python で学ぶ LLM の入門

質問応答

言語タスクの評価指標

Python で学ぶ LLM の入門

完全一致(EM)

  • Exact Match (EM): LLMの出力が参照回答と完全に一致する場合は1
  • 通常はF1スコア{{3}}と併用される
from evaluate import load
em_metric = load("exact_match")

exact_match = evaluate.load("exact_match")
predictions = ["The cat sat on the mat.",
               "Theaters are great.", 
               "Like comparing oranges and apples."]
references = ["The cat sat on the mat?", 
              "Theaters are great.", 
              "Like comparing apples and oranges."]

results = exact_match.compute(
  references=references, predictions=predictions)
print(results)
{'exact_match': 0.3333333333333333}
Python で学ぶ LLM の入門

練習しましょう!

Python で学ぶ LLM の入門

Preparing Video For Download...