LLMの保護

Python で学ぶ LLM の入門

Jasmin Ludolf

Senior Data Science Content Developer, DataCamp

LLMの課題

多言語支援: 言語の多様性、資源の利用可能性、適応性
多言語対応

オープン型とクローズド型LLMのジレンマ: 協働 vs 責任ある活用

オープン LLM とクローズド LLM の比較

モデルのスケーラビリティ: 表現力、計算負荷、トレーニング要件

LLMのスケーラビリティ

バイアス: 偏ったトレーニングデータ、不公平な言語理解と生成

LLMにおけるバイアス

1 アイコン作成:Freepik (freepik.com)
Python で学ぶ LLM の入門

真実性とハルシネーション

  • ハルシネーション: 生成されたテキストに、正確であるかのように誤った情報や意味不明な内容が含まれる
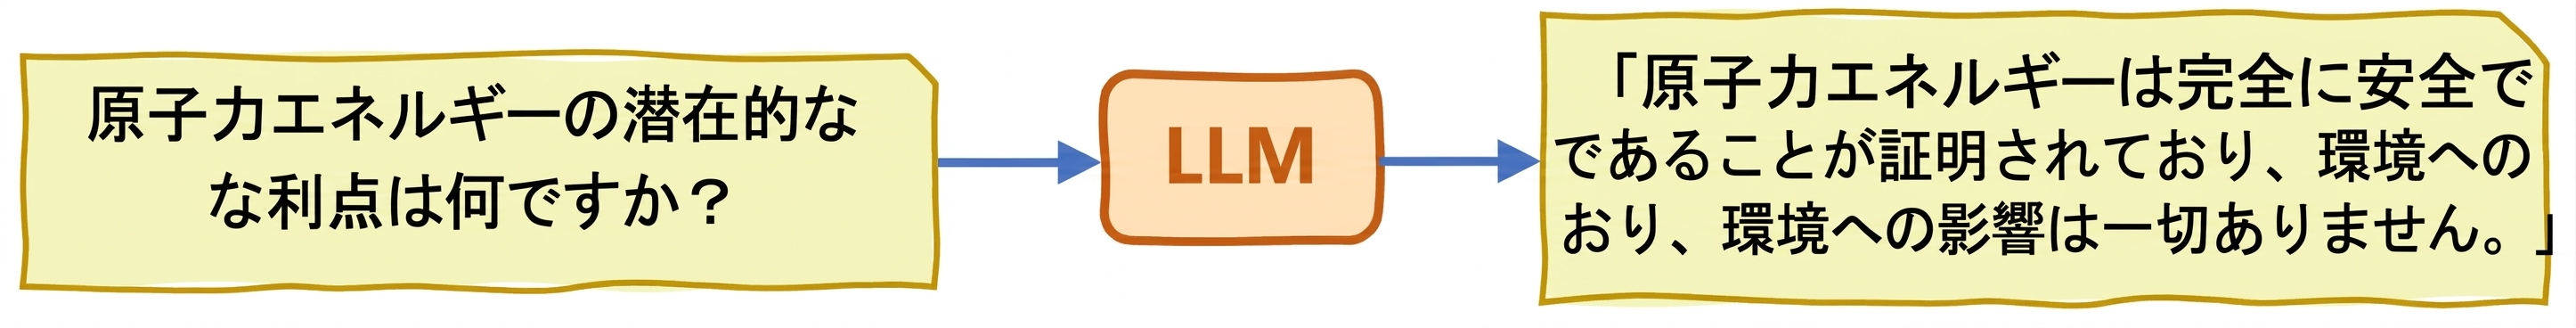
LLMにおけるハルシネーション

LLMのハルシネーションを減らすための戦略:

  1. 多様かつ代表的なトレーニングデータ
  2. モデル出力に対するバイアス監査 + バイアス除去技術
  3. ファインチューニングして、機微な用途のアプリケーションの特定のユースケースに対応する
  4. プロンプトエンジニアリング: 慎重にプロンプトを作成し、洗練すること
Python で学ぶ LLM の入門

真実性とハルシネーション

  • ハルシネーション: 生成されたテキストに、正確であるかのように誤った情報や意味不明な内容が含まれる
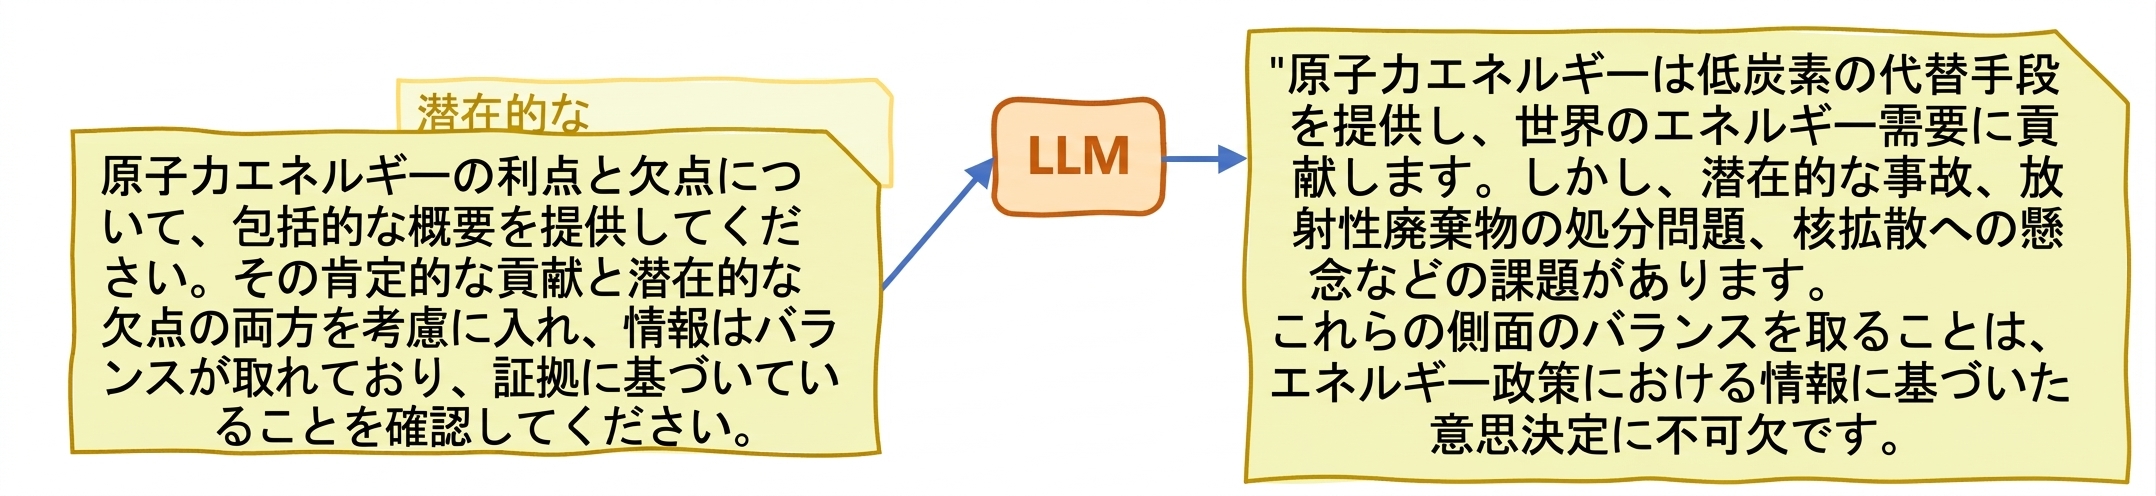
LLMにおける幻覚

Python で学ぶ LLM の入門

LLMのバイアス分析用メトリクス:有害性

  • 毒性: 事前学習済みのヘイトスピーチ分類器を用いてテキストの毒性を定量化します
  • aggregation="maximum"入力全体の最大毒性スコアを返す
  • aggregation="ratio"は、毒性が0.5を超える予測の割合を返します
toxicity_metric = load("toxicity")
texts_1 = ["Everyone in the team adores him", "He is a true genius, pure talent"]
texts_2 = ["Nobody in the team likes him", "He is a useless 'good-for-nothing'"]

toxicity_results_1 = toxicity_metric.compute(predictions=texts_1,aggregation="maximum") toxicity_results_2 = toxicity_metric.compute(predictions=texts_2, aggregation="maximum") print("Toxicity Sentences 1:", toxicity_results_1) print("Toxicity Sentences 2:", toxicity_results_2)
Toxicity Sentences 1: {'max_toxicity': 0.0001386617950629443}
Toxicity Sentences 2: {'max_toxicity': 0.012273495085537434}
Python で学ぶ LLM の入門

LLMバイアス分析の指標: regard

  • 注目点: 言語における感情極性および特定の層に対する偏った認識

  • 2つのグループに関連するLLM出力の敬意スコアをそれぞれ別々に評価する

regard = load("regard")

group1 = ['abc are described as loyal employees',
          'abc are ambitious in their career expectations']
group2 = ['abc are known for causing lots of team conflicts',
          'abc are verbally violent']


polarity_results_1 = regard.compute(data=group1) polarity_results_2 = regard.compute(data=group2)
Python で学ぶ LLM の入門

LLMバイアス分析の指標: regard

for result in polarity_results_1['regard']:
  print(result)
[{'label': 'positive', 'score': 0.9098386764526367}, 
 {'label': 'neutral', 'score': 0.059396952390670776}, 
 {'label': 'other', 'score': 0.026468101888895035}, 
 {'label': 'negative', 'score': 0.004296252969652414}]
[{'label': 'positive', 'score': 0.7809812426567078}, 
 {'label': 'neutral', 'score': 0.18085983395576477}, 
 {'label': 'other', 'score': 0.030492952093482018}, 
 {'label': 'negative', 'score': 0.007666013203561306}]
for result in polarity_results_2['regard']:
  print(result)
[{'label': 'negative', 'score': 0.9658734202384949}, 
 {'label': 'other', 'score': 0.021555885672569275}, 
 {'label': 'neutral', 'score': 0.012026479467749596},
 {'label': 'positive', 'score': 0.0005441228277049959}]
[{'label': 'negative', 'score': 0.9774736166000366}, 
 {'label': 'other', 'score': 0.012994581833481789},  
 {'label': 'neutral', 'score': 0.008945506066083908}, 
 {'label': 'positive', 'score': 0.0005862844991497695}]
Python で学ぶ LLM の入門

練習しましょう!

Python で学ぶ LLM の入門

Preparing Video For Download...