言語タスクの指標:パープレキシティ、BLEU

Python で学ぶ LLM の入門

Jasmin Ludolf

Senior Data Science Content Developer, DataCamp

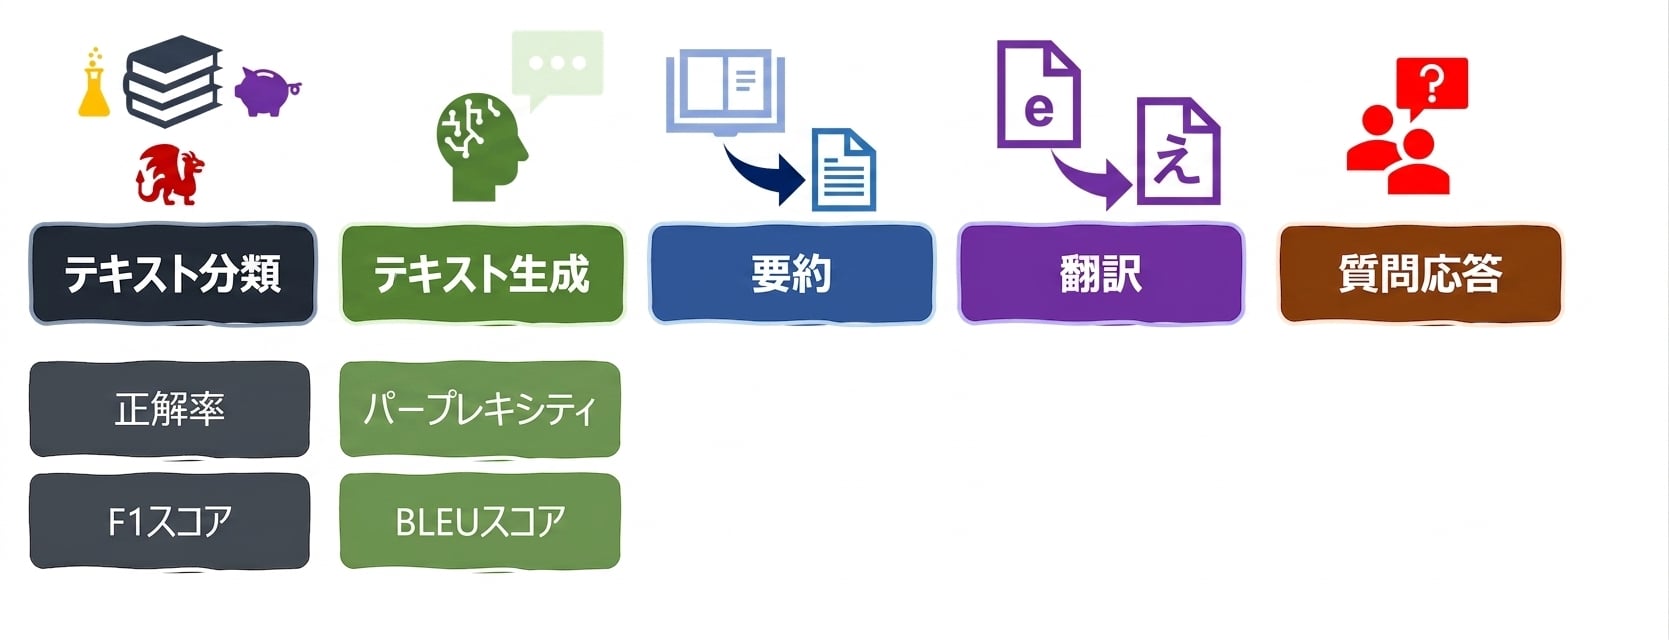
LLMのタスクと評価指標

言語タスクの評価指標

Python で学ぶ LLM の入門

パープレキシティ

  • モデルが次の単語を正確かつ自信を持って予測する能力
  • パープレキシティが低い = 信頼度が高い
input_text = "Latest research findings in Antarctica show"

generated_text = "Latest research findings in Antarctica show that the ice sheet 
is melting faster than previously thought."


# Encode the prompt, generate text and decode it input_text_ids = tokenizer.encode(input_text, return_tensors="pt") output = model.generate(input_text_ids, max_length=20) generated_text = tokenizer.decode(output[0], skip_special_tokens=True)
Python で学ぶ LLM の入門

パープレキシティの出力

perplexity = evaluate.load("perplexity", module_type="metric")
results = perplexity.compute(predictions=generated_text, model_id="gpt2")

print(results)
{'perplexities': [245.63299560546875, 520.3106079101562, ....], 
 'mean_perplexity': 2867.7229790460497}
print(results["mean_perplexity"])
2867.7229790460497
  • ベースライン結果と比較
Python で学ぶ LLM の入門

BLEU

  • 翻訳の質を人手による参照訳と比較して測定

  • 予測: LLMの出力物

  • 参照: 人的参照
bleu = evaluate.load("bleu")


input_text = "Latest research findings in Antarctica show" references = [["Latest research findings in Antarctica show significant ice loss due to climate change.", "Latest research findings in Antarctica show that the ice sheet is melting faster than previously thought."]] generated_text = "Latest research findings in Antarctica show that the ice sheet is melting faster than previously thought."
Python で学ぶ LLM の入門

BLEU の出力

results = bleu.compute(predictions=[generated_text], references=references)
print(results)
{'bleu': 1.0, 
 'precisions': [1.0, 1.0, 1.0, 1.0], 
 'brevity_penalty': 1.0, 
 'length_ratio': 1.2142857142857142, 
 'translation_length': 17, 
 'reference_length': 14}
  • 0-1スコア:1に近いほど高い類似度
Python で学ぶ LLM の入門

練習しましょう!

Python で学ぶ LLM の入門

Preparing Video For Download...