評価ライブラリ

Python で学ぶ LLM の入門

Jasmin Ludolf

Senior Data Science Content Developer, DataCamp

評価ライブラリ

import evaluate

accuracy = evaluate.load("accuracy")
print(accuracy.description)
Accuracy is the proportion of correct
predictions among the total number of cases
processed. It can be computed with:
Accuracy = (TP + TN) / (TP + TN + FP + FN)
Where:
TP: True positive
TN: True negative
FP: False positive
FN: False negative
  • メトリック: モデルのパフォーマンスをグラウンドトゥルースに基づいて評価します
  • 比較:2つのモデルを比較する
  • 測定: データセットの特性に関するインサイト
Python で学ぶ LLM の入門

特徴属性

print(accuracy.features)
{'predictions': Value(dtype='int32', id=None),
 'references': Value(dtype='int32', id=None)}

必要な入力を指標で検査

  • 'predictions': モデル出力
  • 'references':地の真実
  • .features:クラスラベルでサポートされる型を示します(例:'int32' または 'float32'{{3}})
f1 = evaluate.load("f1")
print(f1.features)
{'predictions': Value(dtype='int32', id=None),
 'references': Value(dtype='int32', id=None)}
pearson_corr = evaluate.load("pearsonr")
print(pearson_corr.features)
{'predictions': Value(dtype='float32', id=None),
'references': Value(dtype='float32', id=None)}
Python で学ぶ LLM の入門

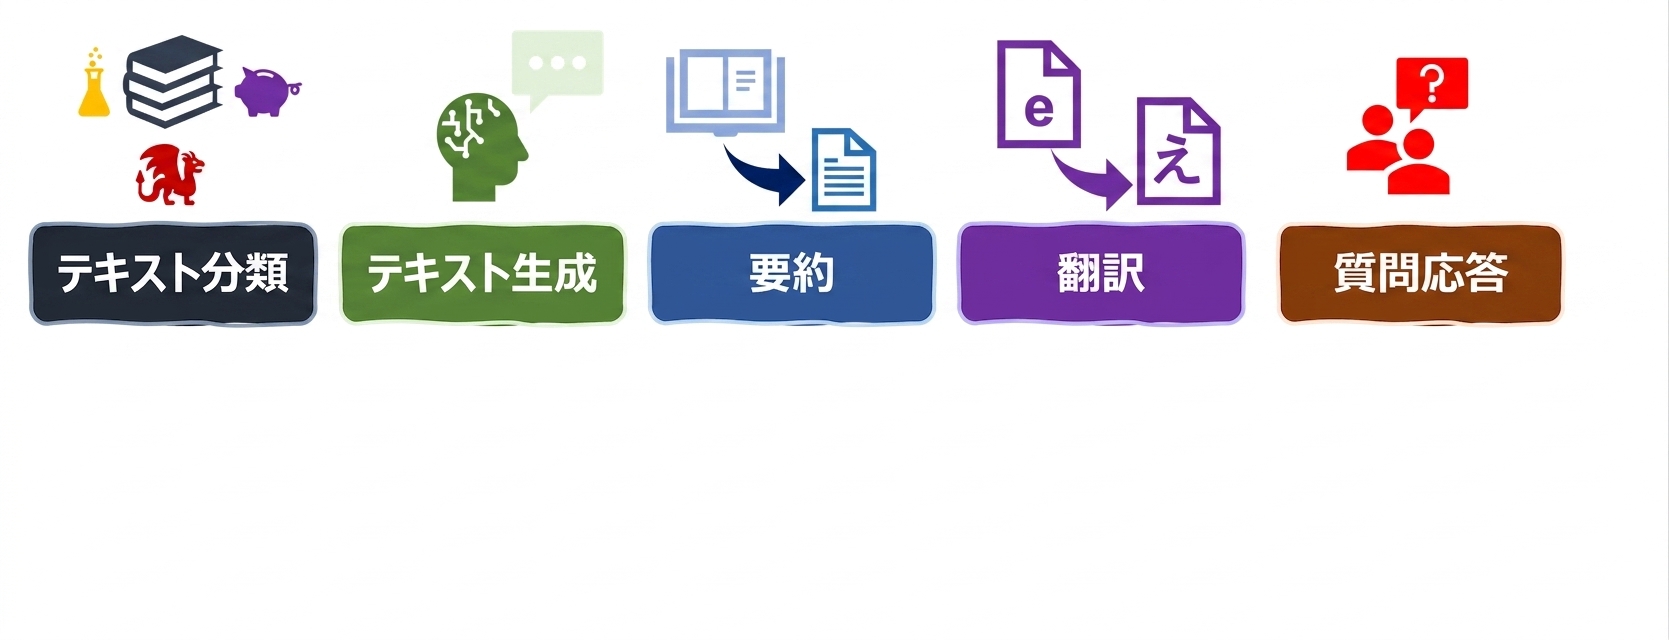
LLMのタスクと評価指標

言語タスクの評価指標

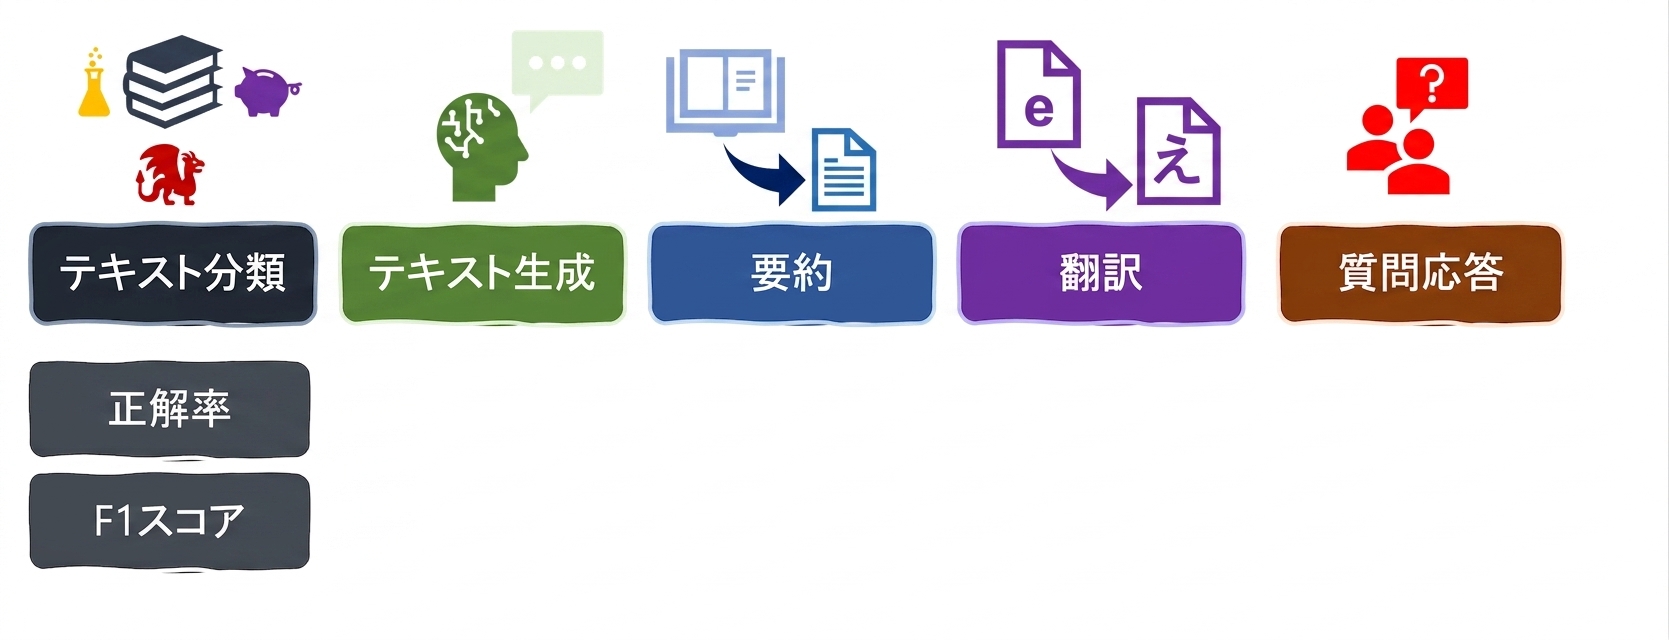
Python で学ぶ LLM の入門

LLMのタスクと評価指標

言語タスクの評価指標

Python で学ぶ LLM の入門

分類指標

accuracy = evaluate.load("accuracy")
precision = evaluate.load("precision")
recall = evaluate.load("recall")
f1 = evaluate.load("f1")
from transformers import pipeline

classifier = pipeline("text-classification", model=model, tokenizer=tokenizer)

predictions = classifier(evaluation_text)

predicted_labels = [1 if pred["label"] == "POSITIVE" else 0 for pred in predictions]
Python で学ぶ LLM の入門

メトリクスの出力

real_labels = [0,1,0,1,1]
predicted_labels = [0,0,0,1,1]

print(accuracy.compute(references=real_labels, predictions=predicted_labels))
print(precision.compute(references=real_labels, predictions=predicted_labels))
print(recall.compute(references=real_labels, predictions=predicted_labels))
print(f1.compute(references=real_labels, predictions=predicted_labels))
{'accuracy': 0.8}
{'precision': 1.0}
{'recall': 0.6666666666666666}
{'f1': 0.8}
Python で学ぶ LLM の入門

ファインチューニング済みモデルの評価

# Load saved model and tokenizer with 
# .from_pretrained("my_finetuned_files")


new_data = ["This is movie was disappointing!", "This is the best movie ever!"] new_input = tokenizer(new_data, return_tensors="pt", padding=True, truncation=True, max_length=64) with torch.no_grad(): outputs = model(**new_input) predicted = torch.argmax(outputs.logits, dim=1).tolist()
real = [0,1]
print(accuracy.compute(references=real,
                       predictions=predicted))
print(precision.compute(references=real,
                        predictions=predicted))
print(recall.compute(references=real,
                     predictions=predicted))
print(f1.compute(references=real, 
                 predictions=predicted))
{'accuracy': 1.0}
{'precision': 1.0}
{'recall': 1.0}
{'f1': 1.0}
Python で学ぶ LLM の入門

適切な評価指標の選択

  • 注意: 各指標は独自の洞察をもたらしますが、限界{{1}}もあります
  • 包括的であること:複数の指標(可能であればドメイン固有のKPIも)を組み合わせて使用する

認識、思考、意思決定を表す電球付きの脳のイラスト

Python で学ぶ LLM の入門

練習しましょう!

Python で学ぶ LLM の入門

Preparing Video For Download...