PySparkで学ぶBig Data入門
Upendra Devisetty
Science Analyst, CyVerse
PySpark MLlib には、Vector と LabeledPoint という専用データ型があります
Vector の種類は2つあります
denseVec = Vectors.dense([1.0, 2.0, 3.0])
DenseVector([1.0, 2.0, 3.0])
sparseVec = Vectors.sparse(4, {1: 1.0, 3: 5.5})
SparseVector(4, {1: 1.0, 3: 5.5})
LabeledPoint は、入力特徴量とラベル値のラッパーです
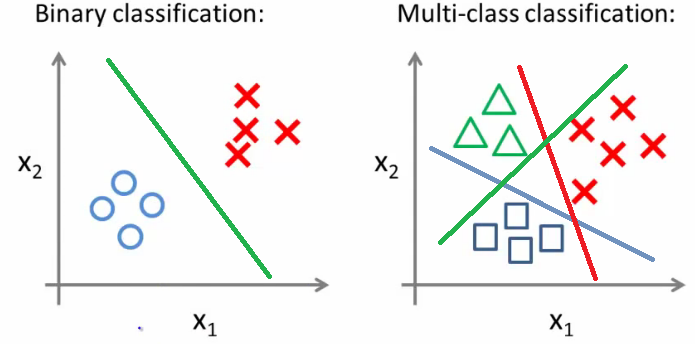
ロジスティック回帰の二値分類では、ラベルは 0(負)または 1(正)です
positive = LabeledPoint(1.0, [1.0, 0.0, 3.0])
negative = LabeledPoint(0.0, [2.0, 1.0, 1.0])
print(positive)
print(negative)
LabeledPoint(1.0, [1.0,0.0,3.0])
LabeledPoint(0.0, [2.0,1.0,1.0])
HashingTF()
from pyspark.mllib.feature import HashingTF
sentence = "hello hello world"
words = sentence.split()
tf = HashingTF(10000)
tf.transform(words)
SparseVector(10000, {3065: 1.0, 6861: 2.0})
data = [
        LabeledPoint(0.0, [0.0, 1.0]),
        LabeledPoint(1.0, [1.0, 0.0]),
]
RDD = sc.parallelize(data)
lrm = LogisticRegressionWithLBFGS.train(RDD)
lrm.predict([1.0, 0.0])
lrm.predict([0.0, 1.0])
1
0