バッチ処理

OpenAI API を使った AI システムの開発

Francesca Donadoni

Curriculum Manager, DataCamp

レート制限とは

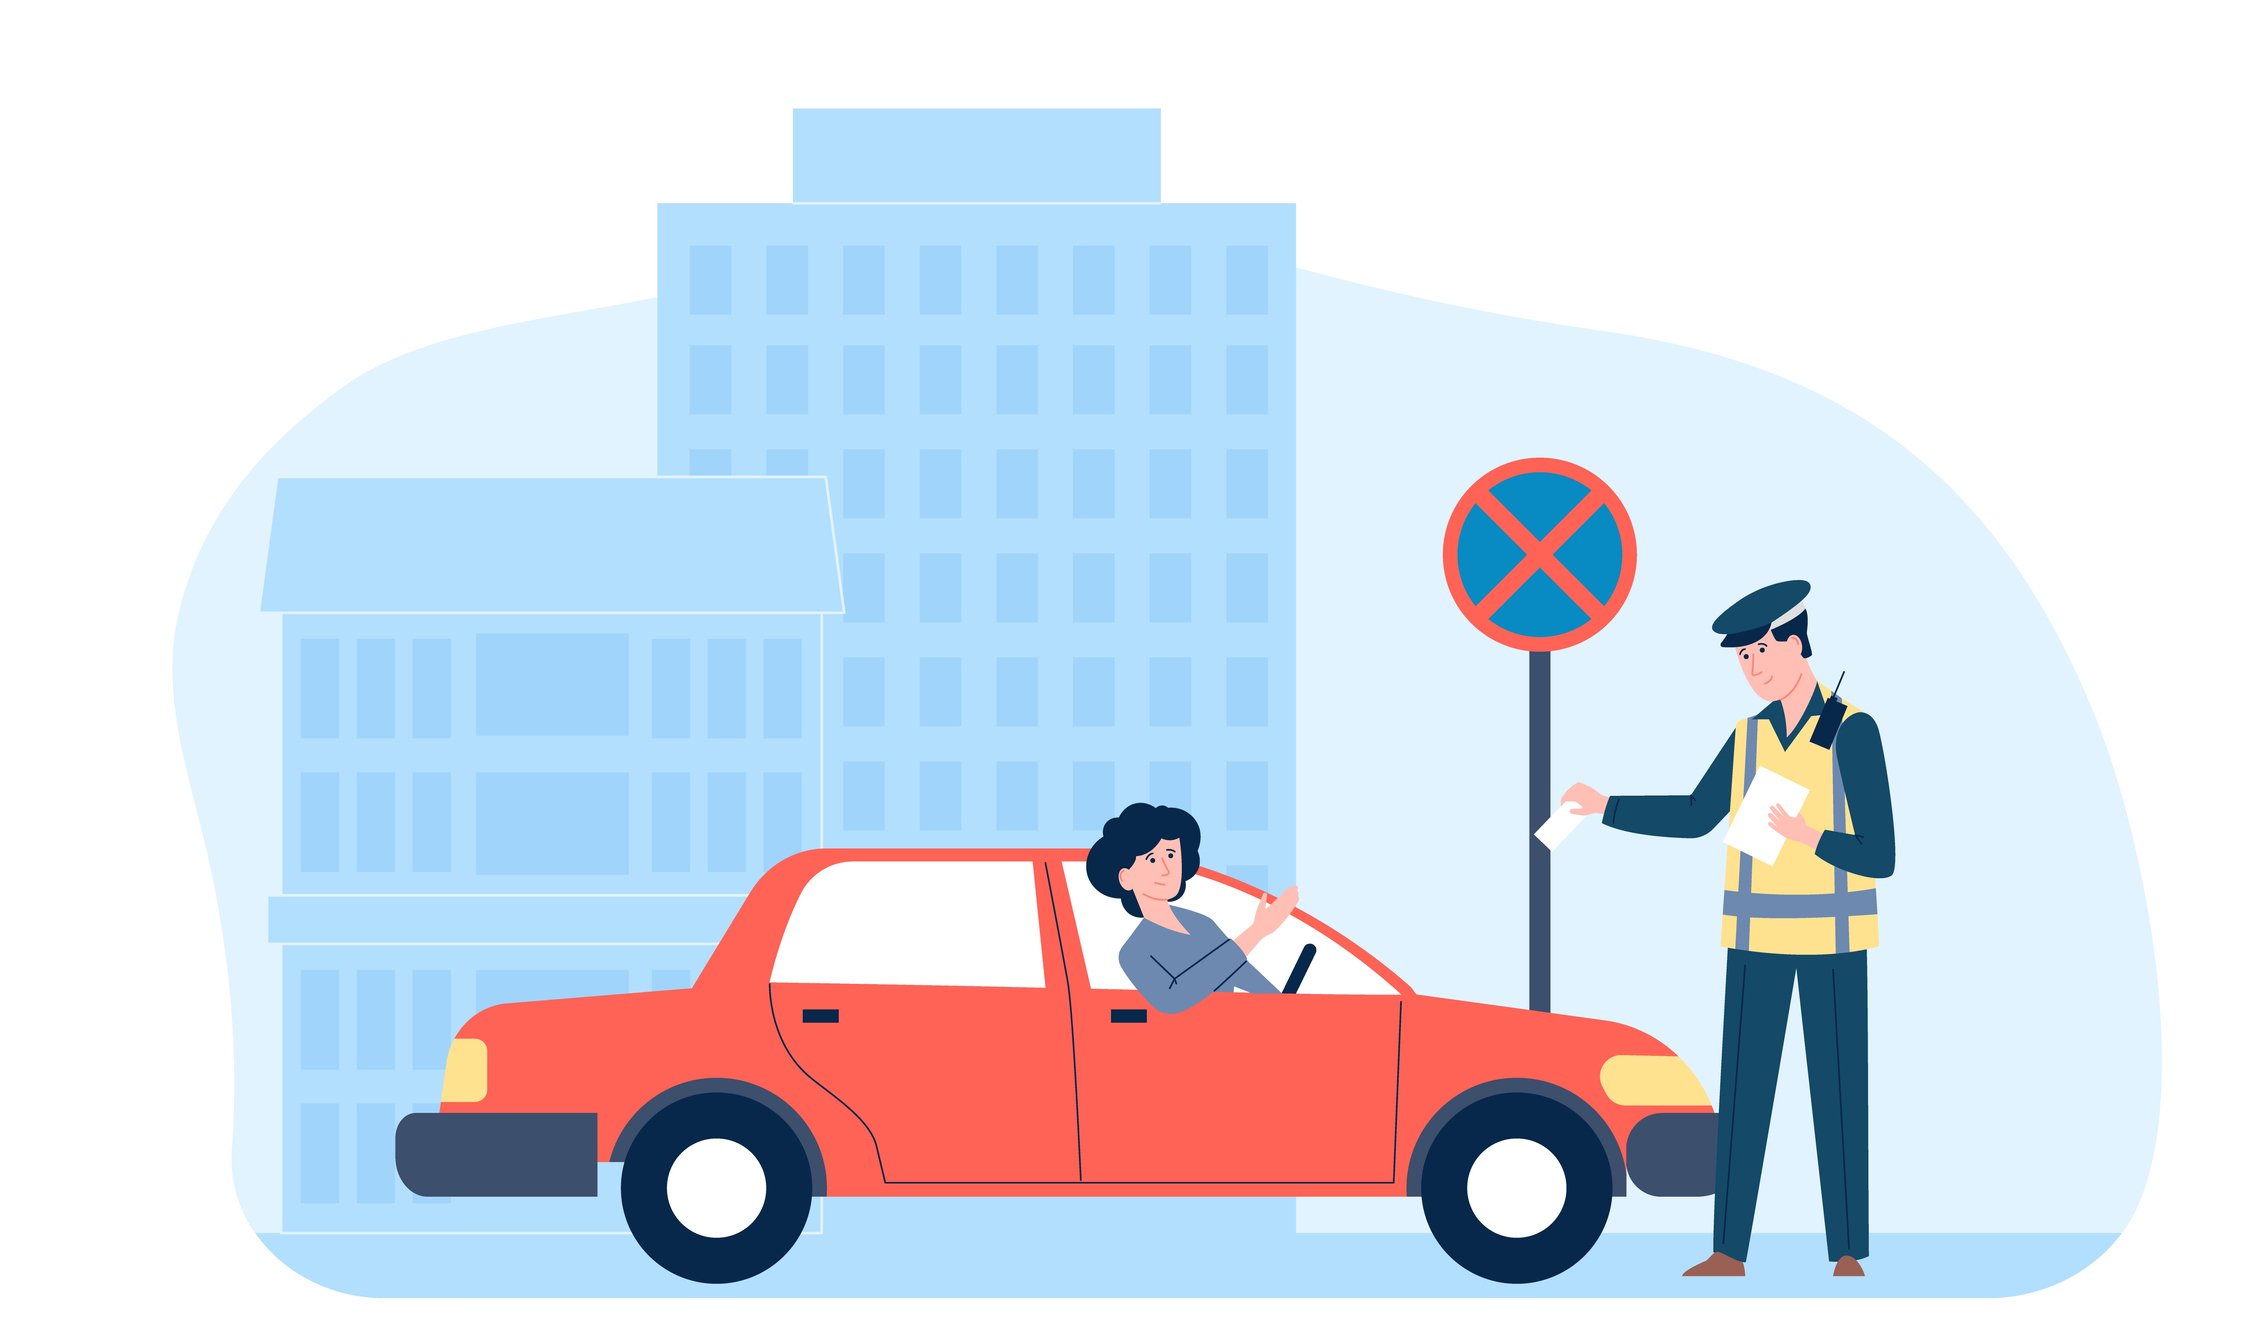
車を運転している人物が警察官に止められている

OpenAI API を使った AI システムの開発

レート制限が発生する仕組み

  • リクエストが多すぎる場合

    複数のメッセージを表す、グループ内の多数の吹き出し
  • リクエストのテキストが多すぎる場合

    白い背景に点が付いた大きな吹き出しアイコン。長いメッセージを表しています
OpenAI API を使った AI システムの開発

レート制限を回避するには

  • 再試行
    • リクエスト間の短い待機時間
  • バッチ処理
    • 1回のリクエストで複数メッセージを処理する
  • トークンの削減
    • トークン数の定量化と削減
OpenAI API を使った AI システムの開発

再試行

from tenacity import (
    retry,
    stop_after_attempt,
    wait_random_exponential
)

@retry(wait=wait_random_exponential(min=1, max=60), stop=stop_after_attempt(6))
OpenAI API を使った AI システムの開発

再試行

@retry(wait=wait_random_exponential(min=1, max=60), stop=stop_after_attempt(6))

def get_response(model, message): response = client.chat.completions.create( model=model, messages=[message], response_format={"type": "json_object"} ) return response.choices[0].message.content
OpenAI API を使った AI システムの開発

バッチ処理

countries = ["United States", "Ireland", "India"]

message=[
    {
    "role": "system",
    "content": """You are given a series of countries and are asked to return the 
    country and capital city. Provide each of the questions with an answer in the 
    response as separate content.""",
    }]


[message.append({"role": "user", "content": i }) for i in countries]
OpenAI API を使った AI システムの開発

バッチ処理

response = client.chat.completions.create(
      model="gpt-4o-mini",
      messages=message
    )

print(response.choices[0].message.content)
United States: Washington D.C.
Ireland: Dublin
India: New Delhi
OpenAI API を使った AI システムの開発

トークンの削減

import tiktoken


encoding = tiktoken.encoding_for_model("gpt-4o-mini")
prompt = "Tokens can be full words, or groups of characters commonly grouped together: tokenization."
num_tokens = len(encoding.encode(prompt))
print("Number of tokens in prompt:", num_tokens)
Number of tokens in prompt: 17
OpenAI API を使った AI システムの開発

練習しましょう!

OpenAI API を使った AI システムの開発

Preparing Video For Download...