검색을 위한 외부 데이터 분할

LangChain으로 LLM 애플리케이션 개발하기

Jonathan Bennion

AI Engineer & LangChain Contributor

RAG 개발 단계
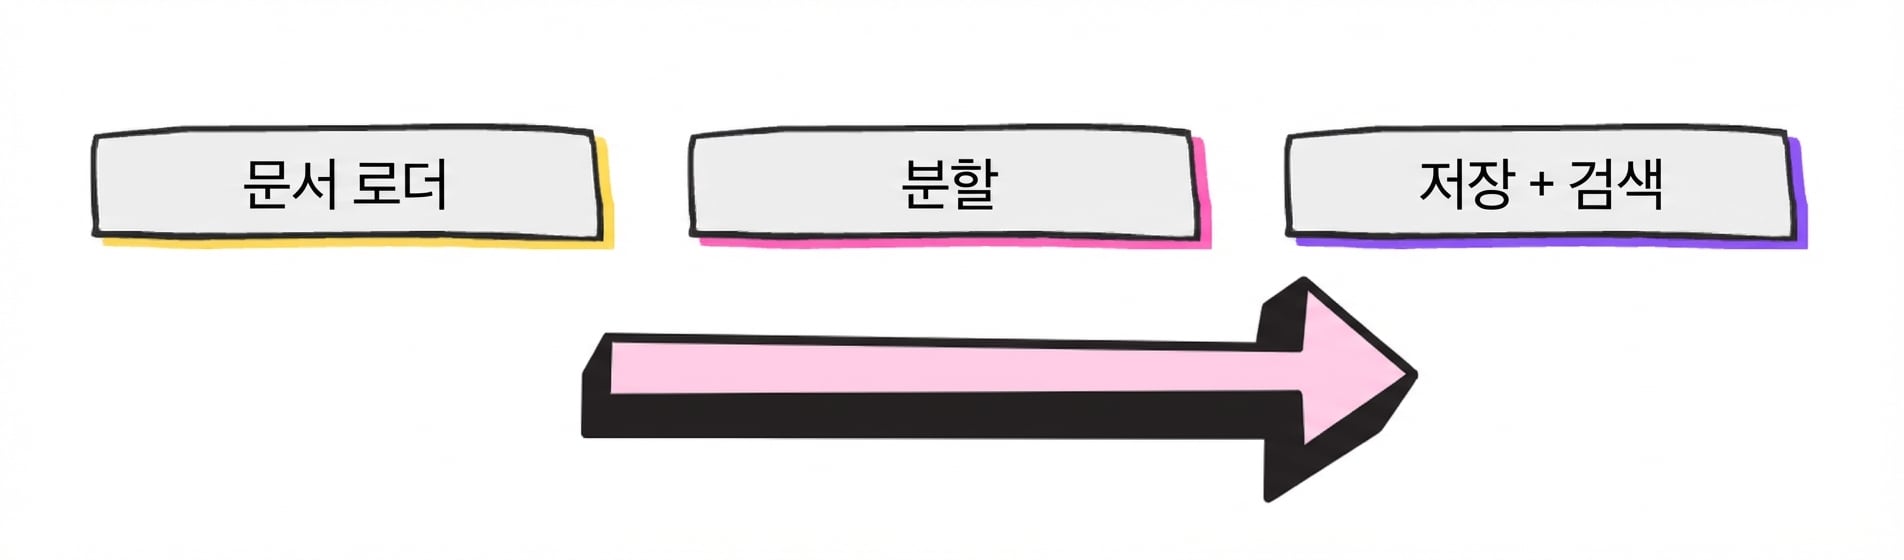
일반적인 RAG 워크플로: 문서 로더, 문서 분할기, 저장 및 검색 프로세스.

  • 문서 분할: 문서를 _청크_로 분할
  • LLM의 컨텍스트 윈도우에 맞게 문서를 나눔
LangChain으로 LLM 애플리케이션 개발하기

분할에 대해 생각하기...

Attention is All You Need 논문 서론 첫 번째 단락.

1행:

Recurrent neural networks, long short-term memory [13] and gated recurrent [7] neural networks

2행:

in particular, have been firmly established as state of the art approaches in sequence modeling and
1 https://arxiv.org/abs/1706.03762
LangChain으로 LLM 애플리케이션 개발하기

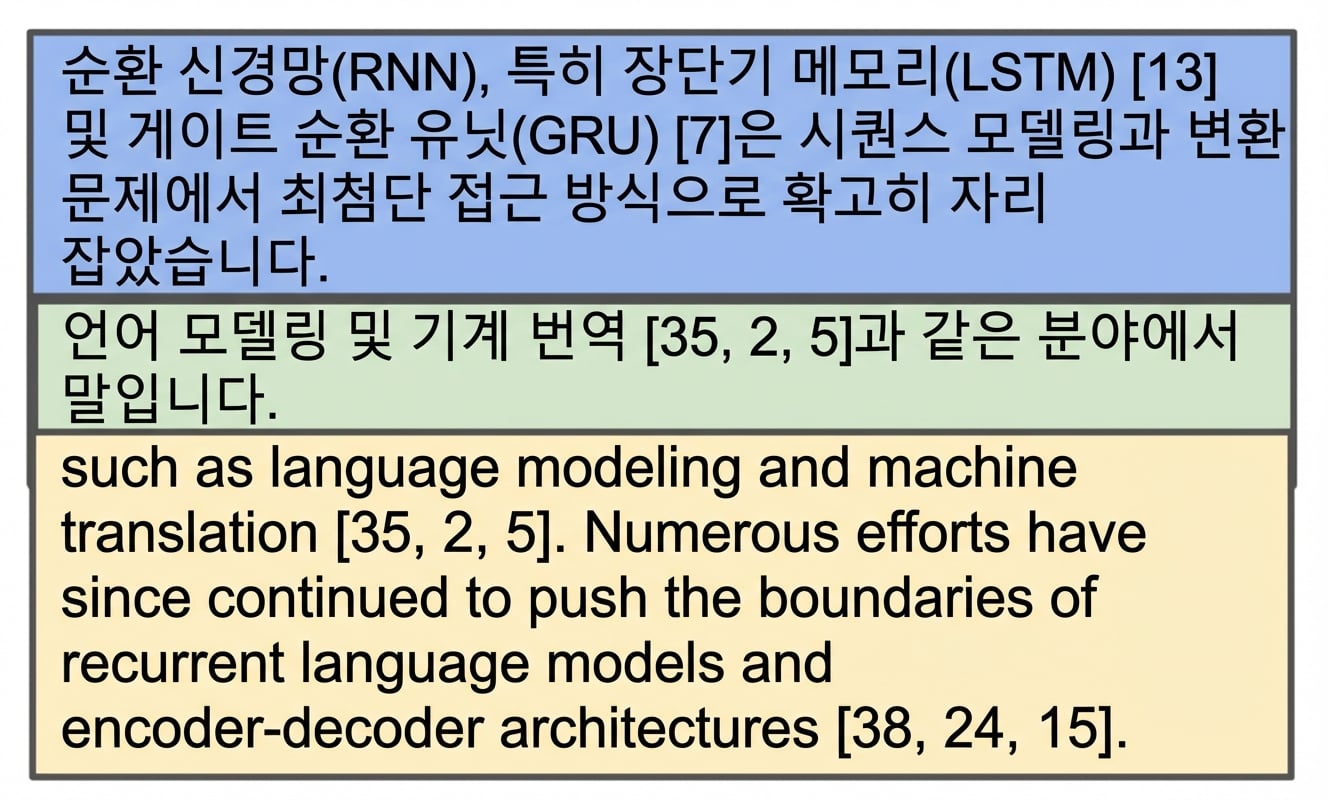
청크 오버랩

Attention is All You Need 논문 서론 첫 번째 단락을 청크 오버랩을 적용하여 두 청크로 분할한 모습.

LangChain으로 LLM 애플리케이션 개발하기

최적의 문서 분할 전략은 무엇인가?

"context"라는 단어를 개별 문자로 분할한 모습.


  1. CharacterTextSplitter
  2. RecursiveCharacterTextSplitter
  3. 그 외 다양한 방법
1 Wikipedia Commons
LangChain으로 LLM 애플리케이션 개발하기
quote = '''One machine can do the work of fifty ordinary humans.\nNo machine can do
the work of one extraordinary human.'''
len(quote)
103
chunk_size = 24
chunk_overlap = 3
1 Elbert Hubbard
LangChain으로 LLM 애플리케이션 개발하기
from langchain_text_splitters import CharacterTextSplitter


ct_splitter = CharacterTextSplitter( separator='.', chunk_size=chunk_size, chunk_overlap=chunk_overlap)
docs = ct_splitter.split_text(quote) print(docs)
print([len(doc) for doc in docs])
['One machine can do the work of fifty ordinary humans',
 'No machine can do the work of one extraordinary human']

[52, 53]
  • 구분자로 분할 시 < chunk_size이지만, 항상 성공하는 것은 아님!
LangChain으로 LLM 애플리케이션 개발하기
from langchain_text_splitters import RecursiveCharacterTextSplitter


rc_splitter = RecursiveCharacterTextSplitter( separators=["\n\n", "\n", " ", ""], chunk_size=chunk_size, chunk_overlap=chunk_overlap)
docs = rc_splitter.split_text(quote) print(docs)
LangChain으로 LLM 애플리케이션 개발하기

RecursiveCharacterTextSplitter

  • separators=["\n\n", "\n", " ", ""]
['One machine can do the',
 'work of fifty ordinary',
 'humans.',
 'No machine can do the',
 'work of one',
 'extraordinary human.']
  1. 단락으로 분할 시도: "\n\n"
  2. 문장으로 분할 시도: "\n"
  3. 단어로 분할 시도: " "
LangChain으로 LLM 애플리케이션 개발하기

RecursiveCharacterTextSplitter로 HTML 분할하기

from langchain_community.document_loaders import UnstructuredHTMLLoader 
from langchain_text_splitters import RecursiveCharacterTextSplitter


loader = UnstructuredHTMLLoader("white_house_executive_order_nov_2023.html") data = loader.load()
rc_splitter = RecursiveCharacterTextSplitter( chunk_size=chunk_size, chunk_overlap=chunk_overlap, separators=['.'])
docs = rc_splitter.split_documents(data) print(docs[0])
Document(page_content="To search this site, enter a search term [...]
LangChain으로 LLM 애플리케이션 개발하기

연습해 봅시다!

LangChain으로 LLM 애플리케이션 개발하기

Preparing Video For Download...