TF‑IDF 表現
Python で学ぶ Machine Learning のための特徴量エンジニアリング

Robert O'Callaghan
Director of Data Science, Ordergroove
TF‑IDF の導入
print(speech_df['Counts_the'].head())
0    21
1    13
2    29
3    22
4    20
TF‑IDF
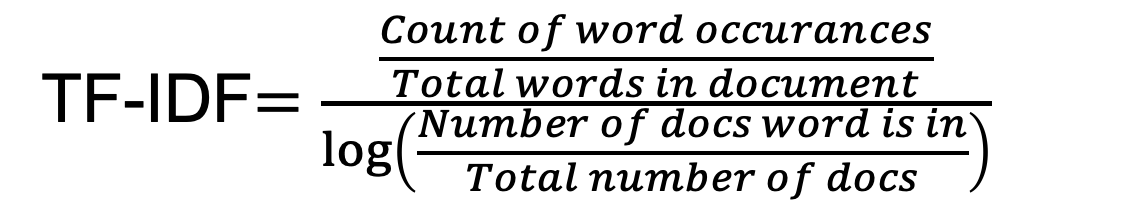
ベクトライザの読み込み
from sklearn.feature_extraction.text import TfidfVectorizer
tv = TfidfVectorizer()
print(tv)
TfidfVectorizer(analyzer=u'word', binary=False, decode_error=u'strict',
        dtype=<type 'numpy.float64'>, encoding=u'utf-8', input=u'content',
        lowercase=True, max_df=1.0, max_features=None, min_df=1,
        ngram_range=(1, 1), norm=u'l2', preprocessor=None, smooth_idf=True,
        stop_words=None, strip_accents=None, sublinear_tf=False,
        token_pattern=u'(?u)\\b\\w\\w+\\b', tokenizer=None, use_idf=True,
        vocabulary=None)
max_features とストップワード
tv = TfidfVectorizer(max_features=100,
                     stop_words='english')
max_features: TF‑IDF で作成する列数の上限
stop_words: 省く一般的な語(例: "and", "the" など)
テキストにフィットさせる
tv.fit(train_speech_df['text'])
train_tv_transformed = tv.transform(train_speech_df['text'])
統合する
train_tv_df = pd.DataFrame(train_tv_transformed.toarray(),
                           columns=tv.get_feature_names())\
                                 .add_prefix('TFIDF_')

train_speech_df = pd.concat([train_speech_df, train_tv_df],
                            axis=1, sort=False)
変換結果を確認する
examine_row = train_tv_df.iloc[0]
print(examine_row.sort_values(ascending=False))
TFIDF_government    0.367430
TFIDF_public        0.333237
TFIDF_present       0.315182
TFIDF_duty          0.238637
TFIDF_citizens      0.229644
Name: 0, dtype: float64
新しいデータへ適用する
test_tv_transformed = tv.transform(test_df['text_clean'])

test_tv_df = pd.DataFrame(test_tv_transformed.toarray(),
                          columns=tv.get_feature_names())\
                            .add_prefix('TFIDF_')

test_speech_df = pd.concat([test_speech_df, test_tv_df],
                           axis=1, sort=False)
練習しましょう!
Python で学ぶ Machine Learning のための特徴量エンジニアリング

