ハイパーパラメータの概要

Pythonでのハイパーパラメータチューニング

Alex Scriven

Data Scientist

ハイパーパラメータとは

ハイパーパラメータ:

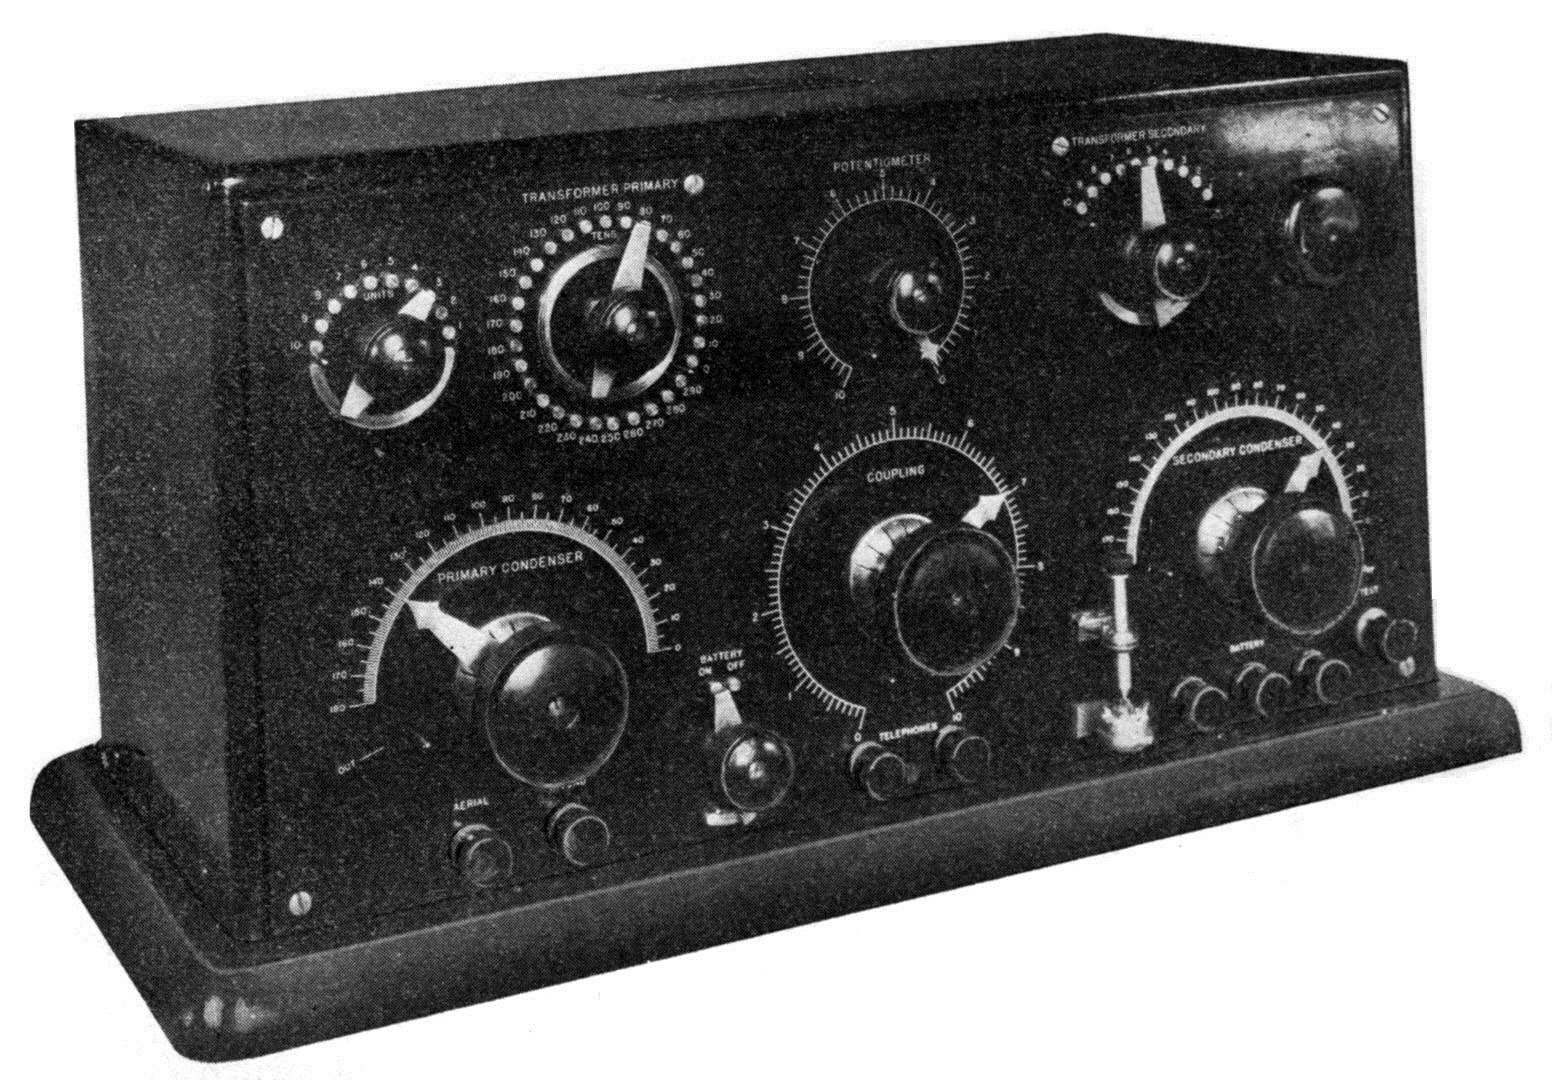
  • モデリング前に受講者が設定するもの(古いラジオのつまみのようなもの)
    • これらは「チューニング」もします
  • アルゴリズム自体は学習しません

つまみのある古いラジオ

Pythonでのハイパーパラメータチューニング

ランダムフォレストのハイパーパラメータ

シンプルなランダムフォレスト推定器を作成して出力します:

rf_clf = RandomForestClassifier()
print(rf_clf)

RandomForestClassifier(n_estimators='warn', criterion='gini', max_depth=None, max_features='auto', max_leaf_nodes=None, min_impurity_decrease=0.0, min_impurity_split=None, min_samples_leaf=1, min_samples_split=2, min_weight_fraction_leaf=0.0, n_jobs=None, oob_score=False, random_state=None, verbose=0,bootstrap=True, class_weight=None, warm_start=False)

詳細: http://scikit-learn.org

Pythonでのハイパーパラメータチューニング

単一ハイパーパラメータの例

n_estimators を例にします。

データ型とデフォルト値:

n_estimators : integer, optional (default=10)

定義:

森の木の本数。

Pythonでのハイパーパラメータチューニング

ハイパーパラメータの設定

推定器作成時に一部を設定します:

rf_clf = RandomForestClassifier(n_estimators=100, criterion='entropy')
print(rf_clf)
RandomForestClassifier(n_estimators=100, criterion='entropy',
            max_depth=None, max_features='auto', max_leaf_nodes=None,
            min_impurity_decrease=0.0, min_impurity_split=None,
            min_samples_leaf=1, min_samples_split=2,
            min_weight_fraction_leaf=0.0, n_jobs=None,
            oob_score=False, random_state=None, verbose=0,bootstrap=True,
            class_weight=None, warm_start=False)
Pythonでのハイパーパラメータチューニング

ロジスティック回帰のハイパーパラメータ

ロジスティック回帰のハイパーパラメータを確認します:

log_reg_clf = LogisticRegression()

print(log_reg_clf) LogisticRegression(C=1.0, class_weight=None, dual=False, fit_intercept=True, intercept_scaling=1, max_iter=100, multi_class='warn', n_jobs=None, penalty='l2', random_state=None, solver='warn', tol=0.0001, verbose=0, warm_start=False)

このアルゴリズムはチューニングすべき項目が少なめです。

Pythonでのハイパーパラメータチューニング

ハイパーパラメータの重要性


重要度の高いハイパーパラメータもあれば、低いものもあります。

モデル性能に寄与しないものもあります。

ランダムフォレスト分類器では:

  • n_jobs
  • random_state
  • verbose

すべてのハイパーパラメータを「学習」すべきとは限りません

Pythonでのハイパーパラメータチューニング

ランダムフォレスト: 重要なハイパーパラメータ


重要なハイパーパラメータ例:

  • n_estimators(大きめに)
  • max_features(複数試す)
  • max_depth と min_sample_leaf(過学習に影響)
  • (場合により)criterion

注意: あくまで目安です

Pythonでのハイパーパラメータチューニング

重要なハイパーパラメータの見つけ方


学ぶためのリソース:

  • 学術論文
  • 信頼できるブログ・チュートリアル(DataCamp など)
  • Scikit-learn のドキュメント
  • 実務経験
Pythonでのハイパーパラメータチューニング

Passons à la pratique !

Pythonでのハイパーパラメータチューニング

Preparing Video For Download...