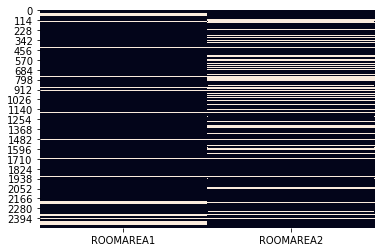
# Import library
import seaborn as sns

# subset the dataframe
sub_df = df.select(['ROOMAREA1'])

# sample the dataframe
sample_df = sub_df.sample(False, .5, 4)

# Convert to Pandas DataFrame
pandas_df = sample_df.toPandas()

# Plot it
sns.heatmap(data=pandas_df.isnull())
欠損値のヒートマップ
欠損値の補完
欠損値を置換するプロセス
ルールベース
ビジネスロジックに基づく値
統計ベース
平均・中央値などを使用
モデルベース
モデルで値を予測
欠損値の補完
** fillna(value, subset=None)
value 欠損値に代入する値
subset 対象とする列名のリスト
# Replacing missing values with zero
df.fillna(0, subset=['DAYSONMARKET'])
# Replacing with the mean value for that column
col_mean = df.agg({'DAYSONMARKET': 'mean'}).collect()[0][0]
df.fillna(col_mean, subset=['DAYSONMARKET'])