テキストベースの類似性

Pythonでつくるレコメンデーションエンジン

Rob O'Callaghan

Director of Data

明確な属性なしでの作業
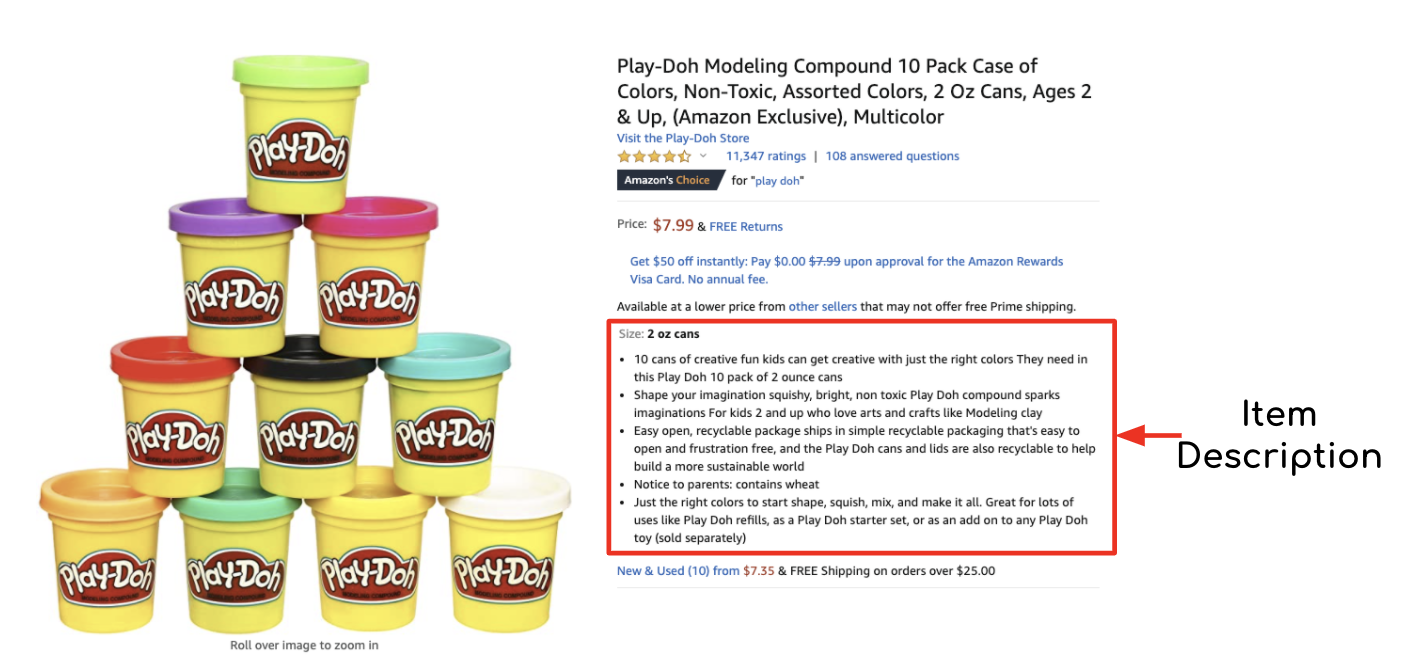
Amazon の商品説明例。

Pythonでつくるレコメンデーションエンジン

TF-IDF(単語の重要度)

$$ \Large{\text{TF-IDF} = \frac{\frac{\text{単語出現回数}}{\text{文書内の総単語数}}}{\log({\frac{\text{その単語を含む文書数}}{\text{総文書数}}})}} $$

Pythonでつくるレコメンデーションエンジン

データ

book_summary_df:

Book Description
The Hobbit "ビルボ・バギンズはシャイアでホビット仲間と質素に暮らしている…"
The Great Gatsby "ジャズ・エイジのニューヨークを舞台に、ジェイの悲劇を描く…"
A Game of Thrones "ロバートの反乱から15年、9年にわたる…"
Macbeth "勇敢なスコットランドの将軍が三人の魔女から予言を受ける…"
... ...
Pythonでつくるレコメンデーションエンジン

ベクトライザの作成

from sklearn.feature_extraction.text import TfidfVectorizer
tfidfvec = TfidfVectorizer(        ,           )
Pythonでつくるレコメンデーションエンジン

データのフィルタリング

from sklearn.feature_extraction.text import TfidfVectorizer
tfidfvec = TfidfVectorizer(min_df=2,           )
Pythonでつくるレコメンデーションエンジン

データのフィルタリング

from sklearn.feature_extraction.text import TfidfVectorizer
tfidfvec = TfidfVectorizer(min_df=2, max_df=0.7)
Pythonでつくるレコメンデーションエンジン

データのベクトル化

vectorized_data = tfidfvec.fit_transform(book_summary_df['Descriptions'])

print(tfidfvec.get_feature_names)
['age', 'ancient', 'angry', 'brave', 'battle', 'fellow', 'game', 'general', ...]
print(vectorized_data.to_array())
[[0.21,      0.53,    0.41,    0.64,     0.01,     0.02,     ...
 [0.31,      0.00,    0.42,    0.03,     0.00,     0.73,     ...
 [...,        ...,     ...,     ...,      ...,      ...,     ...
Pythonでつくるレコメンデーションエンジン

データの整形

tfidf_df = pd.DataFrame(vectorized_data.toarray(),
                        columns=tfidfvec.get_feature_names())

tfidf_df.index = book_summary_df['Book']
print(tfidf_df)
                   | 'age'| 'ancient'| 'angry'| 'brave'| 'battle'| 'fellow'|...
|------------------|------|----------|--------|--------|---------|---------|...
| The Hobbit       |  0.21|      0.53|    0.41|    0.64|     0.01|     0.02|...
| The Great Gatsby |  0.31|      0.00|    0.42|    0.03|     0.00|     0.73|...
| A Game of Thrones|  0.61|      0.42|    0.77|    0.31|     0.83|     0.03|...
|               ...|   ...|       ...|     ...|     ...|      ...|      ...|...
Pythonでつくるレコメンデーションエンジン

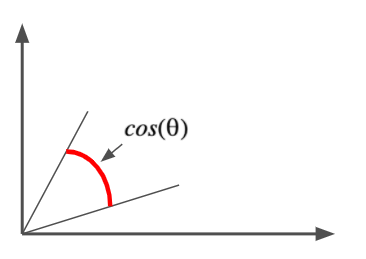
コサイン類似度

コサイン距離: $$cos(\theta)=\frac{A.B }{||A||\cdot||B||}$$
Pythonでつくるレコメンデーションエンジン

コサイン類似度

from sklearn.metrics.pairwise import cosine_similarity

# すべてのアイテム間の類似度
cosine_similarity_array = cosine_similarity(tfidf_summary_df)
# 2つのアイテム間の類似度
cosine_similarity(tfidf_df.loc['The Hobbit'].values.reshape(1, -1),
                  tfidf_df.loc['Macbeth'].values.reshape(1, -1))
Pythonでつくるレコメンデーションエンジン

練習しましょう!

Pythonでつくるレコメンデーションエンジン

Preparing Video For Download...