GitHub Actions によるモデルトレーニング

Machine Learning のための CI/CD

Ravi Bhadauria

Machine Learning Engineer

データセット: オーストラリアの気象予測

  • 二値分類
    • 明日の降雨を予測
  • カテゴリ特徴量 5 個
    • Location
    • WindGustDir
    • WindDir9am
    • WindDir3pm
    • RainToday
  • 数値特徴量 17 個
    • MinTemp
    • MaxTemp
    • Rainfall
    • Evaporation
    • ...
    • WindGustSpeed
    • Cloud3pm
    • Temp9am
    • RISK_MM
1 https://www.kaggle.com/datasets/rever3nd/weather-data
Machine Learning のための CI/CD

モデリングワークフロー

  • データ前処理
    • カテゴリ特徴量を数値に変換
    • 特徴量の欠損値を補完
    • 特徴量をスケーリング
  • Random Forest Classifier
    • max_depth = 2, n_estimators = 50
  • テストデータにおける標準的な評価指標
    • 性能プロット
      • 混同行列プロット
Machine Learning のための CI/CD

データ準備: ターゲットエンコーディング

def target_encode_categorical_features(
    df: pd.DataFrame, categorical_columns: List[str], target_column: str
) -> pd.DataFrame:
    encoded_data = df.copy()

    # Iterate through categorical columns
    for col in categorical_columns:
        # Calculate mean target value for each category
        encoding_map = df.groupby(col)[target_column].mean().to_dict()

        # Apply target encoding
        encoded_data[col] = encoded_data[col].map(encoding_map)

    return encoded_data
1 https://maxhalford.github.io/blog/target-encoding/
Machine Learning のための CI/CD

欠損値補完とスケーリング

def impute_and_scale_data(df_features: pd.DataFrame) -> pd.DataFrame:
    # Impute data with mean strategy
    imputer = SimpleImputer(strategy="mean")
    X_preprocessed = imputer.fit_transform(df_features.values)

    # Scale and fit with zero mean and unit variance
    scaler = StandardScaler()
    X_preprocessed = scaler.fit_transform(X_preprocessed)

    return pd.DataFrame(X_preprocessed, columns=df_features.columns)
Machine Learning のための CI/CD

トレーニング

  • 学習・テストデータの分割
from sklearn.model_selection import train_test_split

X_train, X_test, y_train, y_test = train_test_split(
  data.drop(TARGET_COLUMN), data[TARGET_COLUMN], random_state=1993)
  • Random Forest Classifier
from sklearn.ensemble import RandomForestClassifier

clf = RandomForestClassifier(
  max_depth=2, n_estimators=50, random_state=1993)
clf.fit(X_train, y_train)
Machine Learning のための CI/CD

評価指標

from sklearn.metrics import accuracy_score, f1_score, precision_score, recall_score

# Calculate predictions
y_pred = model.predict(X_test)

# Calculate accuracy accuracy = accuracy_score(y_test, y_pred)
# Calculate precision precision = precision_score(y_test, y_pred)
# Calculate recall recall = recall_score(y_test, y_pred)
# Calculate f1 score f1 = f1_score(y_test, y_pred)
1 https://scikit-learn.org/stable/modules/model_evaluation.html#classification-metrics
Machine Learning のための CI/CD

プロット

from sklearn.metrics import ConfusionMatrixDisplay
ConfusionMatrixDisplay.from_estimator(model, X_test, y_test,cmap=plt.cm.Blues)
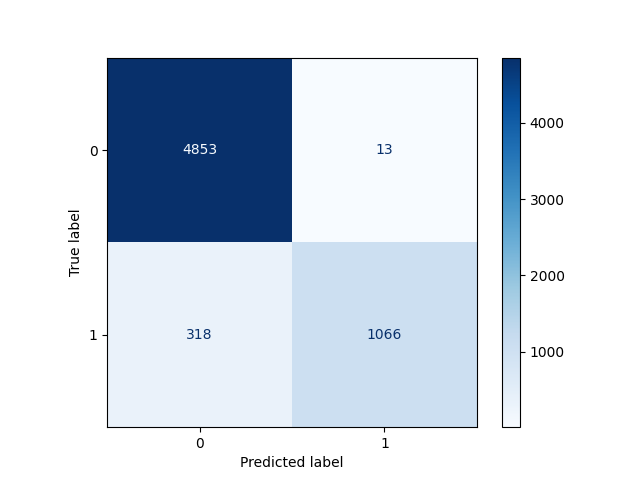
テストセットで計算した混同行列のプロット

Machine Learning のための CI/CD

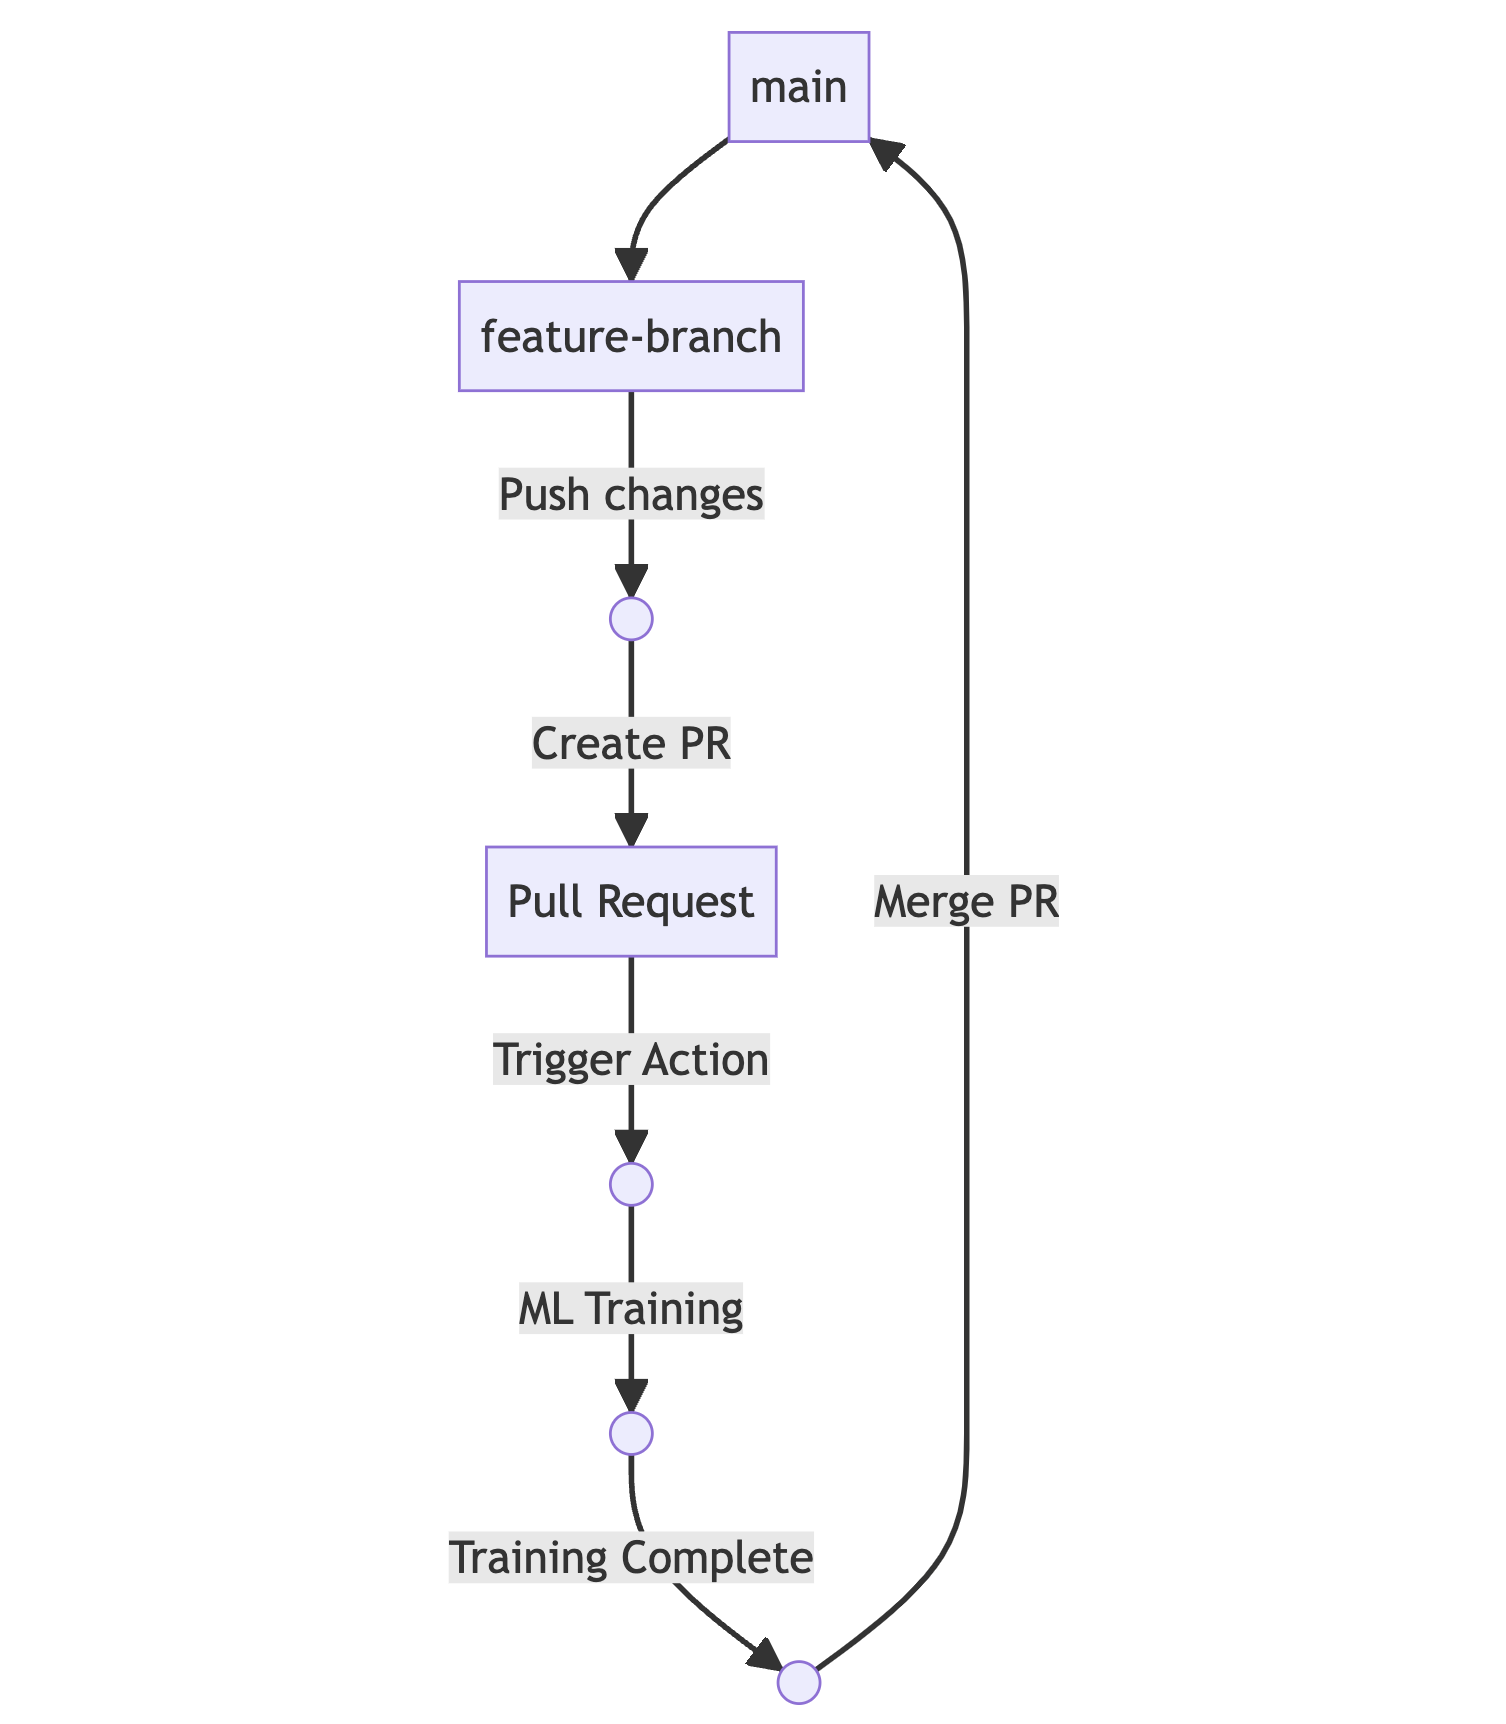
GitHub Actions ワークフロー

モデルトレーニングの継続的インテグレーションワークフローのプロット

  • Continuous Machine Learning(CML)
    • Machine Learning 向けの CI/CD ツール
    • GitHub Actions との統合
      • トレーニング用マシンのプロビジョニング
      • トレーニングと評価を実行
      • 実験の比較
      • データセットの監視
      • 視覚的なレポート
1 https://cml.dev/ 2 https://martinfowler.com/bliki/FeatureBranch.html
Machine Learning のための CI/CD

CML コマンド

# Enable setup-cml action to be used later
- uses: iterative/setup-cml@v1
- name: Train model
  run: |
    # Your ML workflow goes here
    pip install -r requirements.txt
    python3 train.py
1 https://www.markdownguide.org/basic-syntax/#images
Machine Learning のための CI/CD

CML コマンド

- name: Write CML report
  run: |
    # Add results and plots to markdown
    cat results.txt >> report.md
    echo "![training graph](./graph.png)" >> report.md

# Create comment from markdown report cml comment create report.md
env: REPO_TOKEN: ${{ secrets.GITHUB_TOKEN }}
Machine Learning のための CI/CD

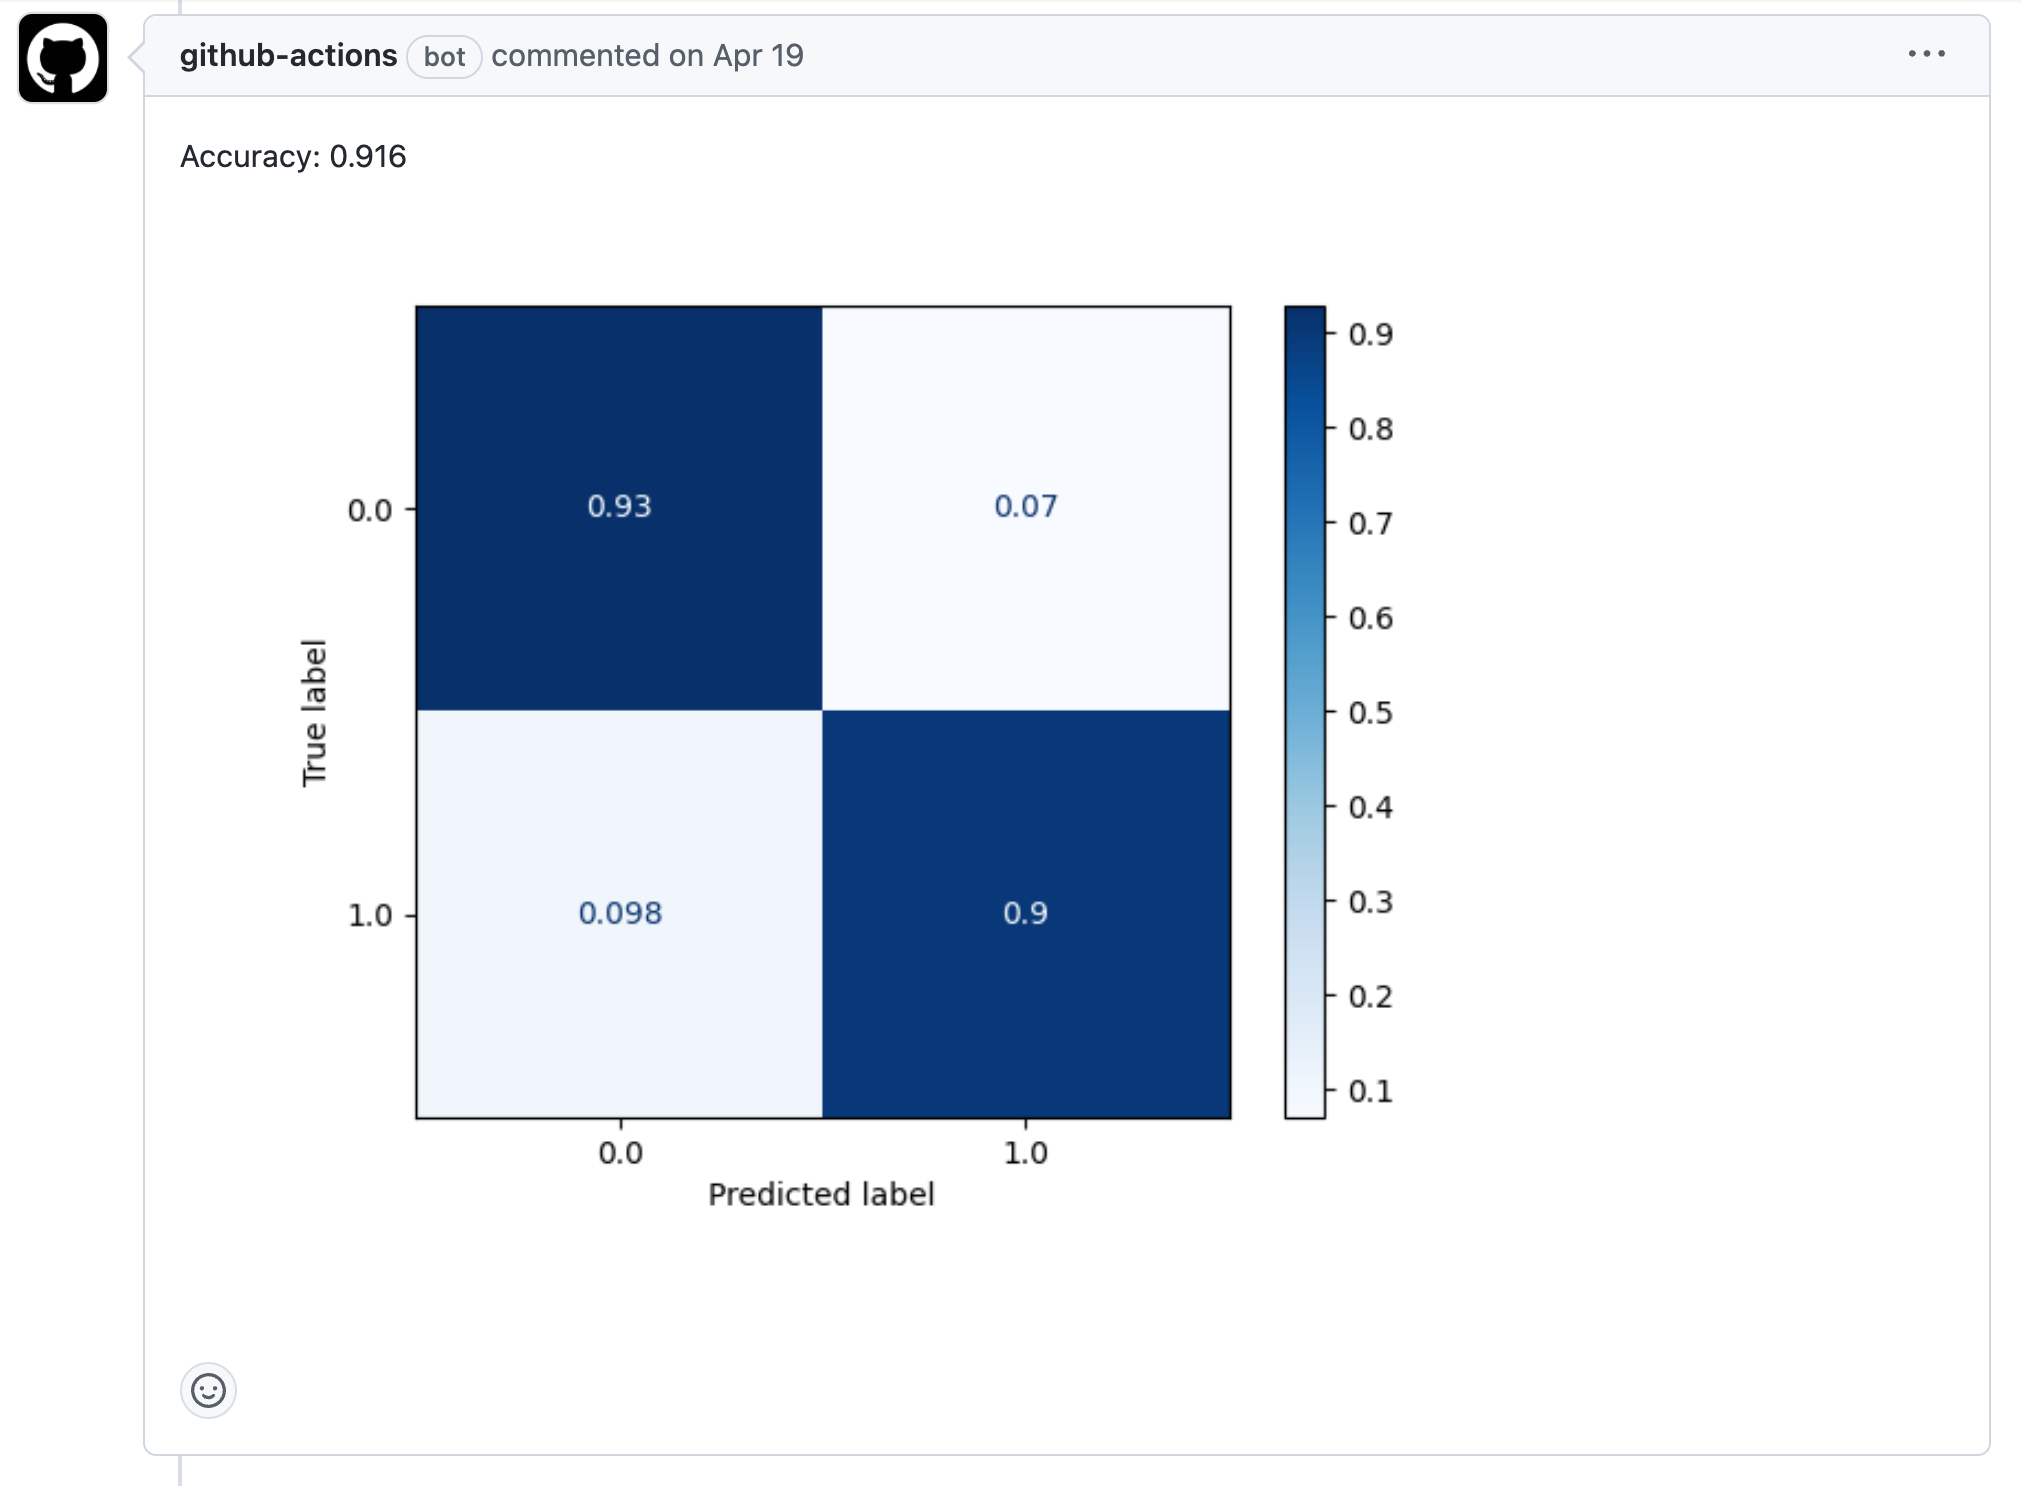
出力

CML が生成したコメントを表示するプルリクエストページのスクリーンショット

Machine Learning のための CI/CD

練習しましょう!

Machine Learning のための CI/CD

Preparing Video For Download...