Inference for Numerical Data in R
Mine Cetinkaya-Rundel
Associate Professor of the Practice, Duke University
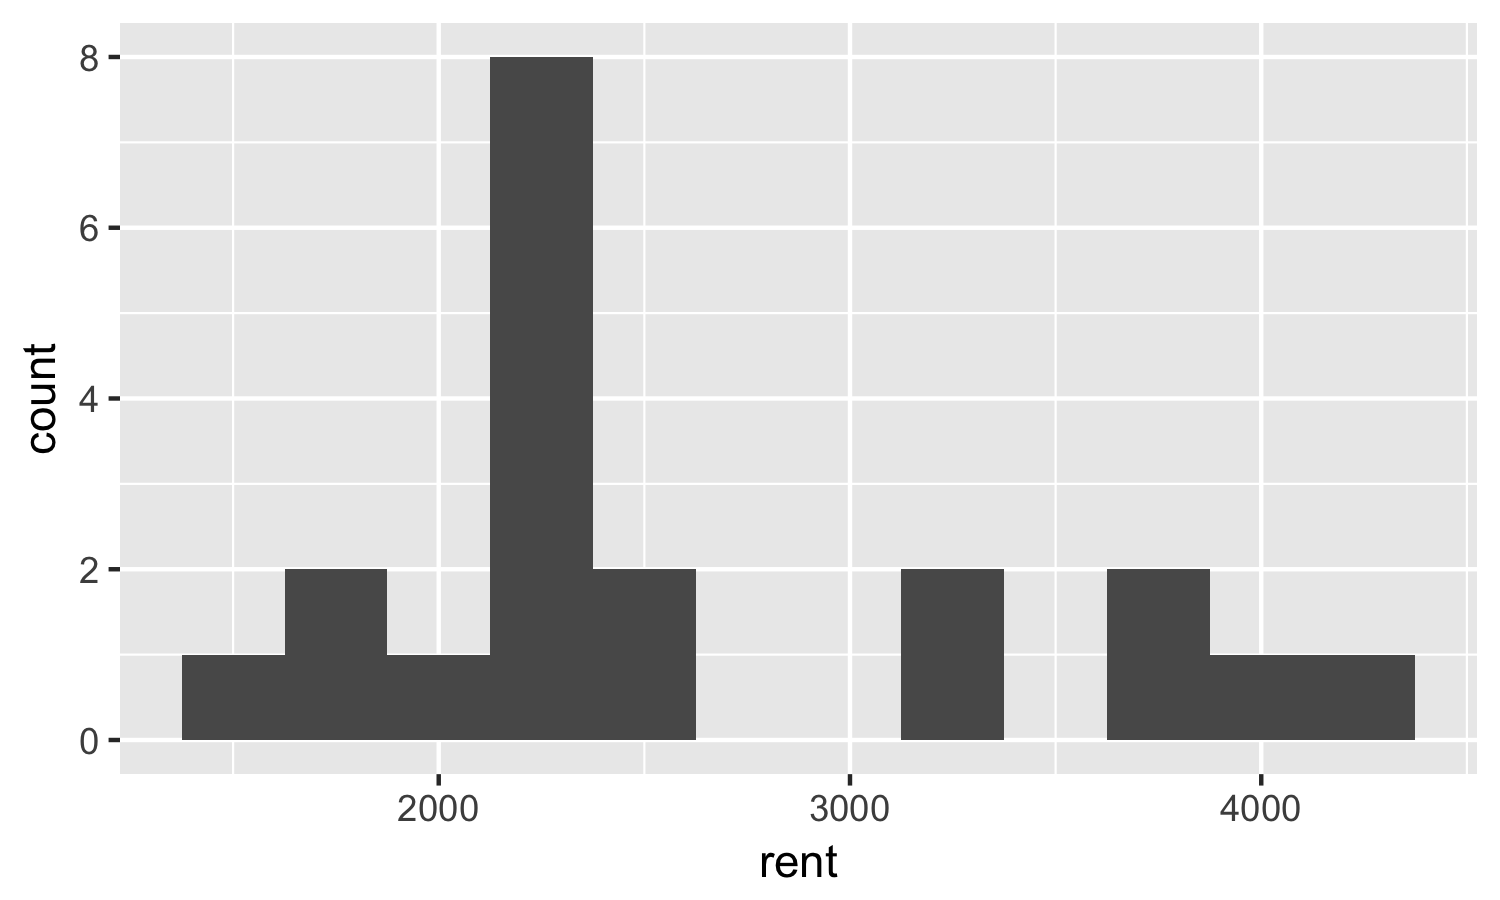
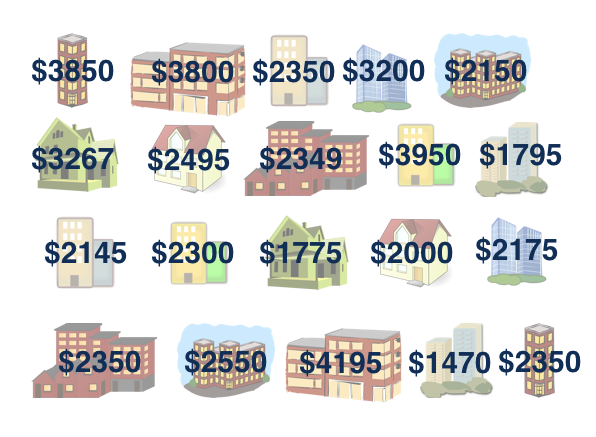
V daný den bylo na Craigslist Manhattan náhodně vybráno dvacet bytů 1+kk inzerovaných jako „od majitele" (nikoli přes realitní agenturu).
Co lépe vystihuje typický nájem na Manhattanu – průměr, nebo medián?

medián vzorku = $2 350


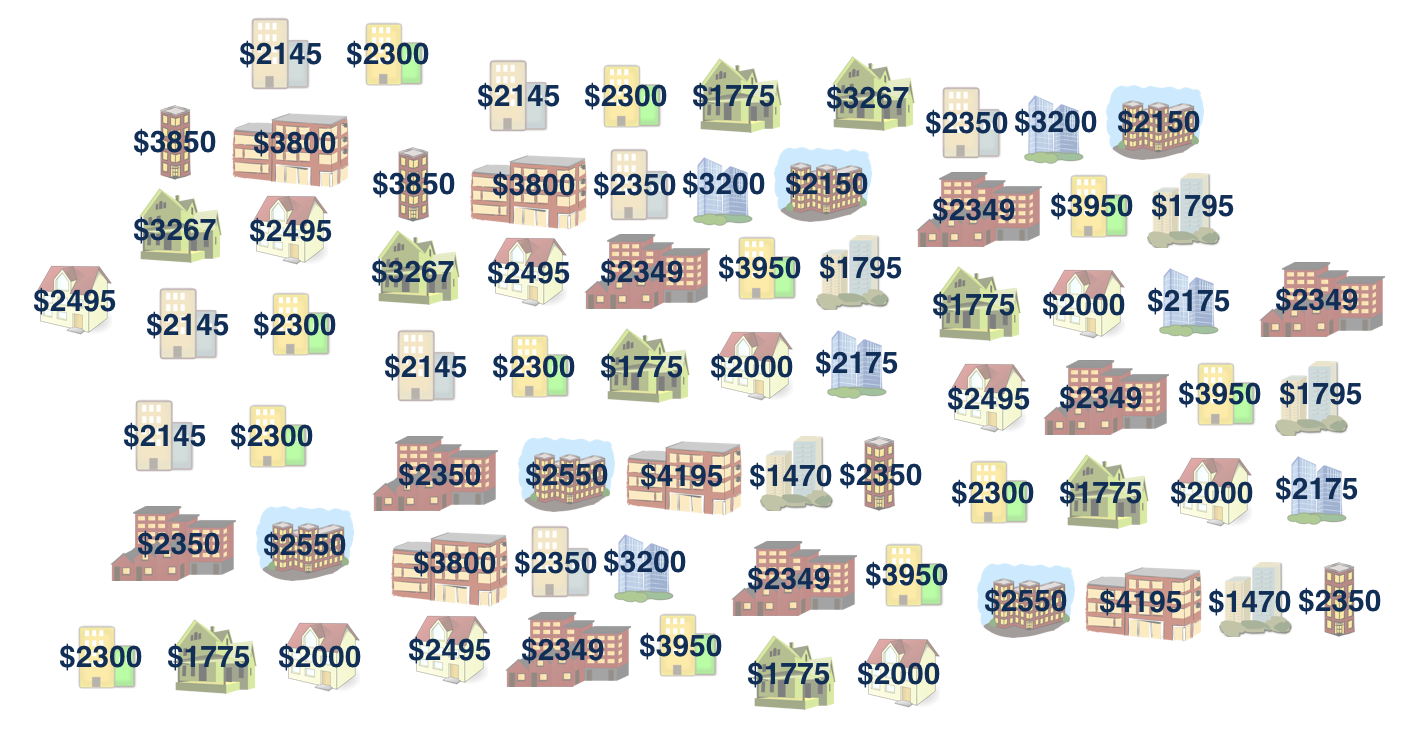
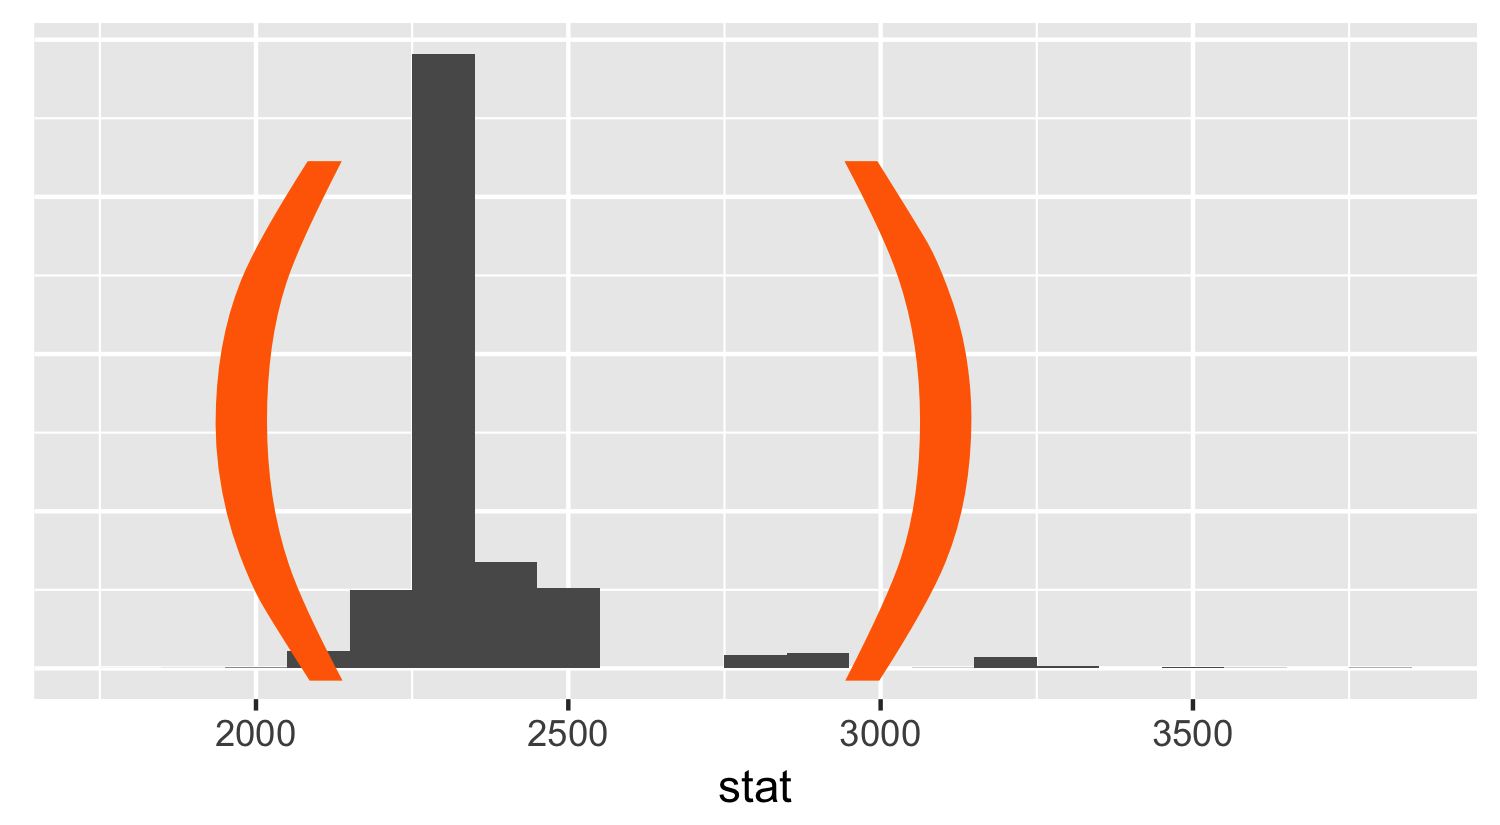
Vezměte bootstrapový vzorek – náhodný výběr s opakováním ze základního vzorku, stejně velký jako původní vzorek.
Vypočítejte bootstrapovou statistiku – např. průměr, medián nebo podíl – ze získaných vzorků.
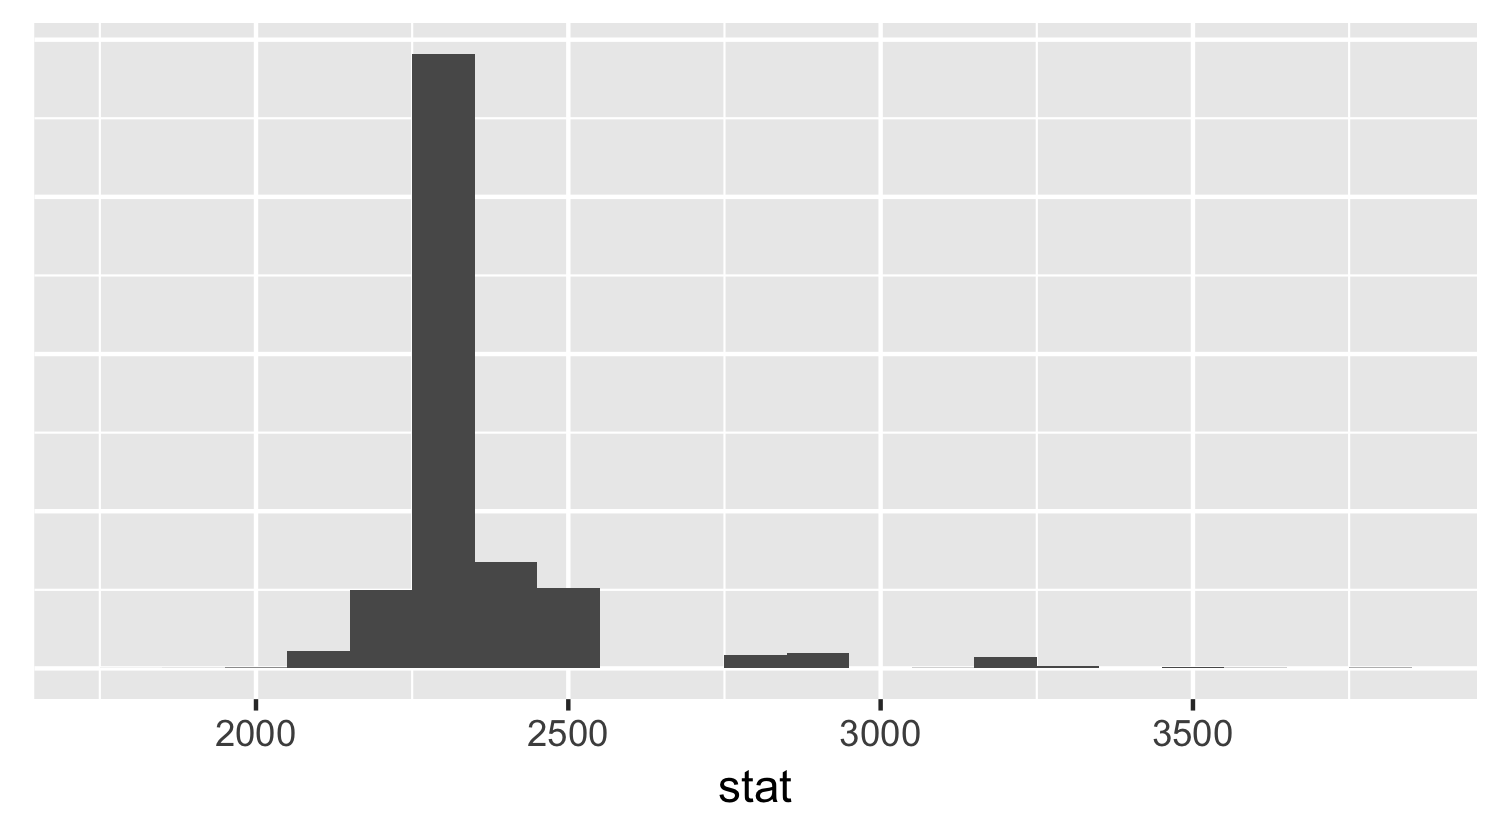
Opakujte kroky (1) a (2) mnohokrát a vytvořte bootstrapové rozdělení – rozdělení bootstrapových statistik.
library(infer)
___ %>% # start with data frame
specify(response = ___) %>% # specify the variable of interest
library(infer)
___ %>% # start with data frame
specify(response = ___) %>% # specify the variable of interest
generate(reps = ___, type = "bootstrap") %>% # generate bootstrap samples
library(infer)
___ %>% # start with data frame
specify(response = ___) %>% # specify the variable of interest
generate(reps = ___, type = "bootstrap") %>% # generate bootstrap samples
calculate(stat = "___") # calculate bootstrap statistic
library(infer)
___ %>% # start with data frame
specify(response = ___) %>% # specify the variable of interest
generate(reps = ___, type = "bootstrap") %>% # generate bootstrap samples
calculate(stat = "___") # calculate bootstrap statistic
library(infer)
___ %>% # start with data frame
specify(response = ___) %>% # specify the variable of interest
generate(reps = ___, type = "bootstrap") %>% # generate bootstrap samples
calculate(stat = "___") # calculate bootstrap statistic

Inference for Numerical Data in R