清洗并改进数据

Python 中的时间序列机器学习

Chris Holdgraf

Fellow, Berkeley Institute for Data Science

数据是混乱的

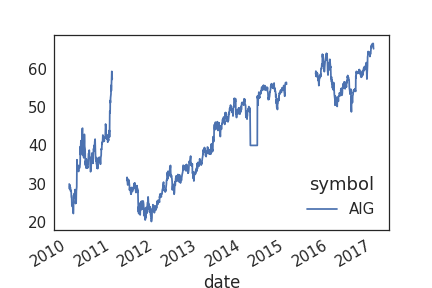
  • 真实世界数据常常很乱
  • 最常见的两个问题是"缺失值"和"异常值"
  • 原因包括人工失误、传感器故障、数据库失败等
  • 可视化原始数据更易发现问题
Python 中的时间序列机器学习

混乱数据长什么样

Python 中的时间序列机器学习

插值:用时间填补缺失数据

  • 处理缺失值的常见方法是"插值"
  • 对于时间序列,可利用时间信息辅助插值。
  • 这里的"插值"指用缺口两侧的已知值来推断缺失部分。
Python 中的时间序列机器学习

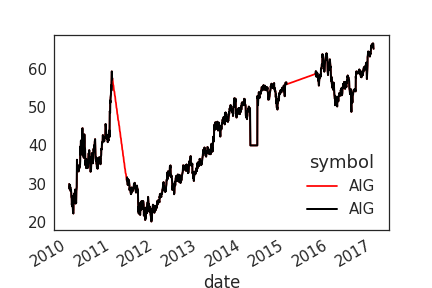
在 Pandas 中进行插值

# Return a boolean that notes where missing values are
missing = prices.isna()

# Interpolate linearly within missing windows
prices_interp = prices.interpolate('linear')

# Plot the interpolated data in red and the data w/ missing values in black
ax = prices_interp.plot(c='r')
prices.plot(c='k', ax=ax, lw=2)
Python 中的时间序列机器学习

可视化插值结果

Python 中的时间序列机器学习

用滚动窗口转换数据

  • 滚动窗口的另一常见用途是转换数据
  • 我们已用它来"平滑"数据
  • 还可用于更复杂的转换
Python 中的时间序列机器学习

转换数据以标准化方差

  • 常见转换是随时间标准化均值和方差,方法多样。
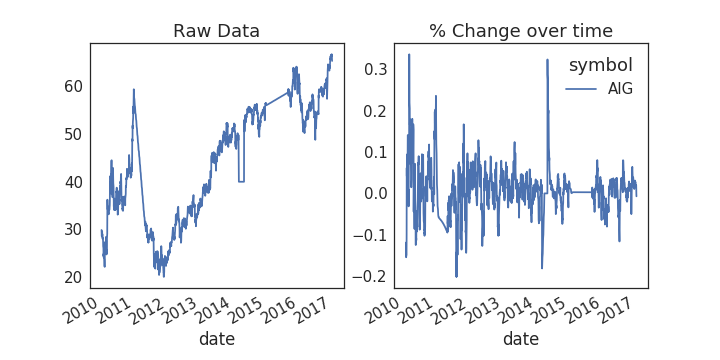
  • 此处将把数据集转换为:每个点表示"相对前一窗口的百分比变化"。
  • 当数值波动大时,使各时间点更可比
Python 中的时间序列机器学习

用 Pandas 转换为百分比变化

def percent_change(values):
    """Calculates the % change between the last value 
    and the mean of previous values"""
    # Separate the last value and all previous values into variables
    previous_values = values[:-1]
    last_value = values[-1]

    # Calculate the % difference between the last value 
    # and the mean of earlier values
    percent_change = (last_value - np.mean(previous_values)) \
    / np.mean(previous_values)
    return percent_change
Python 中的时间序列机器学习

将其应用到我们的数据

# Plot the raw data
fig, axs = plt.subplots(1, 2, figsize=(10, 5))
ax = prices.plot(ax=axs[0])

# Calculate % change and plot
ax = prices.rolling(window=20).aggregate(percent_change).plot(ax=axs[1])
ax.legend_.set_visible(False)
Python 中的时间序列机器学习

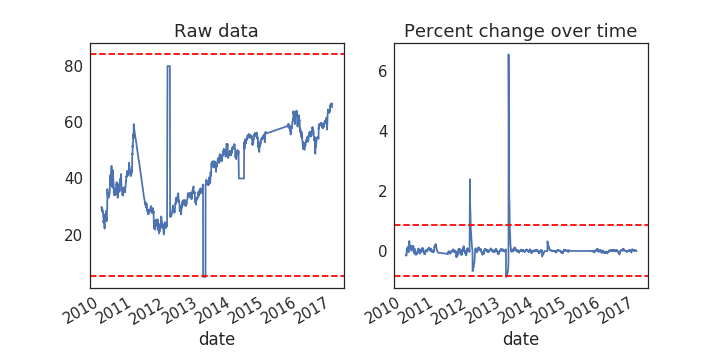
在数据中查找异常值

  • 异常值是与整体数据显著不同的点。
  • 它会削弱模型预测力,使其偏离"真实"值
  • 可通过"删除"或"替换"为更具代表性的值来处理

请务必谨慎——很难判断极端值是真实波动还是异常

Python 中的时间序列机器学习

为数据绘制阈值线

fig, axs = plt.subplots(1, 2, figsize=(10, 5))
for data, ax in zip([prices, prices_perc_change], axs):
    # Calculate the mean / standard deviation for the data
    this_mean = data.mean()
    this_std = data.std()

    # Plot the data, with a window that is 3 standard deviations 
    # around the mean
    data.plot(ax=ax)
    ax.axhline(this_mean + this_std * 3, ls='--', c='r')
    ax.axhline(this_mean - this_std * 3, ls='--', c='r')
Python 中的时间序列机器学习

可视化异常值阈值

Python 中的时间序列机器学习

用阈值替换异常值

# Center the data so the mean is 0
prices_outlier_centered = prices_outlier_perc - prices_outlier_perc.mean()

# Calculate standard deviation
std = prices_outlier_perc.std()

# Use the absolute value of each datapoint 
# to make it easier to find outliers
outliers = np.abs(prices_outlier_centered) > (std * 3)

# Replace outliers with the median value
# We'll use np.nanmean since there may be nans around the outliers
prices_outlier_fixed = prices_outlier_centered.copy()
prices_outlier_fixed[outliers] = np.nanmedian(prices_outlier_fixed)

Python 中的时间序列机器学习

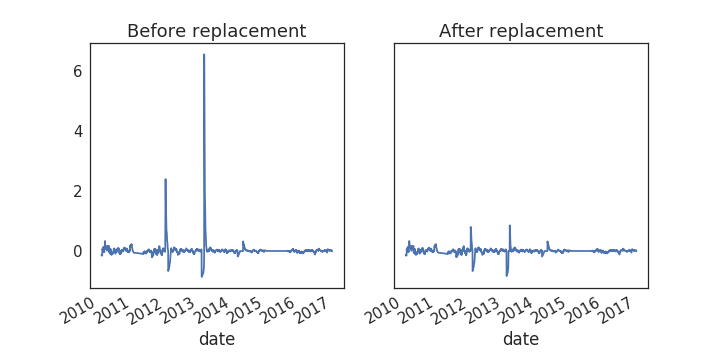
可视化结果

fig, axs = plt.subplots(1, 2, figsize=(10, 5))
prices_outlier_centered.plot(ax=axs[0])
prices_outlier_fixed.plot(ax=axs[1])
Python 中的时间序列机器学习

Passons à la pratique !

Python 中的时间序列机器学习

Preparing Video For Download...