使用 PySpark 进行特征工程
John Hogue
Lead Data Scientist, General Mills
df.select(['NO', 'UNITNUMBER', 'CLASS']).show()
+----+----------+-----+
|  NO|UNITNUMBER|CLASS|
+----+----------+-----+
|   1|      null|   SF|
| 156|        A8|   SF|
| 157|       207|   SF|
| 158|      701G|   SF|
| 159|        36|   SF|
多列对我们的分析无用
drop(*cols)
*cols
# 待删除的列
cols_to_drop = ['NO', 'UNITNUMBER', 'CLASS']

# 删除这些列
df = df.drop(*cols_to_drop)
# 待删除的列 cols_to_drop = ['NO', 'UNITNUMBER', 'CLASS']
# 删除这些列 df = df.drop(*cols_to_drop)
where(condition)
types.BooleanType
like(other)
~
df = df.where(~df['POTENTIALSHORTSALE'].like('Not Disclosed'))
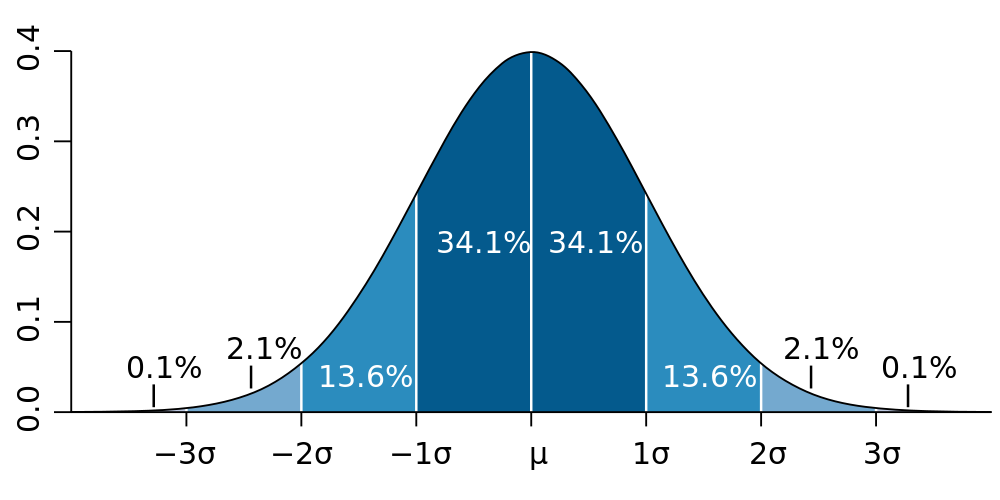
将数据筛选在均值(μ)± 三个标准差(3σ)内
# 计算用于筛选的值
std_val = df.agg({'SALESCLOSEPRICE': 'stddev'}).collect()[0][0]
mean_val = df.agg({'SALESCLOSEPRICE': 'mean'}).collect()[0][0]

# 构建三倍标准差范围(μ ± 3σ)的上下界
hi_bound = mean_val + (3 * std_val)
low_bound = mean_val - (3 * std_val)

# 使用 where() 在区间内筛选 DataFrame
df = df.where((df['LISTPRICE'] < hi_bound) & (df['LISTPRICE'] > low_bound))
# 计算用于筛选的值 std_val = df.agg({'SALESCLOSEPRICE': 'stddev'}).collect()[0][0] mean_val = df.agg({'SALESCLOSEPRICE': 'mean'}).collect()[0][0]
# 构建三倍标准差范围(μ ± 3σ)的上下界 hi_bound = mean_val + (3 * std_val) low_bound = mean_val - (3 * std_val)
# 使用 where() 在区间内筛选 DataFrame df = df.where((df['LISTPRICE'] < hi_bound) & (df['LISTPRICE'] > low_bound))
DataFrame.dropna()
how
thresh
subset
# 删除含有任意 NULL 的记录
df = df.dropna()

# 若 LISTPRICE 和 SALESCLOSEPRICE 均为 NULL 则删除
df = df.dropna(how='all', subset['LISTPRICE', 'SALESCLOSEPRICE '])

# 至少有两列为 NULL 时删除记录
df = df.dropna(thresh=2)
# 删除含有任意 NULL 的记录 df = df.dropna()
# 若 LISTPRICE 和 SALESCLOSEPRICE 均为 NULL 则删除 df = df.dropna(how='all', subset['LISTPRICE', 'SALESCLOSEPRICE '])
# 至少有两列为 NULL 时删除记录 df = df.dropna(thresh=2)
什么是重复值?
dropDuplicates()
# 整个 DataFrame
df.dropDuplicates()

# 仅检查部分列
df.dropDuplicates(['streetaddress'])
# 整个 DataFrame df.dropDuplicates()
# 仅检查部分列 df.dropDuplicates(['streetaddress'])