带经验回放的 DQN

Python 中的深度强化学习

Timothée Carayol

Principal Machine Learning Engineer, Komment

经验回放简介


  • 基础版 DQN 仅从最新经验学习
    • 连续更新高度相关
    • 容易遗忘
  • 方案:经验回放
    • 将经验存入缓冲区
    • 每步从过去经验中随机采样一批来学习


树篱迷宫的航拍图

Python 中的深度强化学习

双端队列(Deque)


from collections import deque

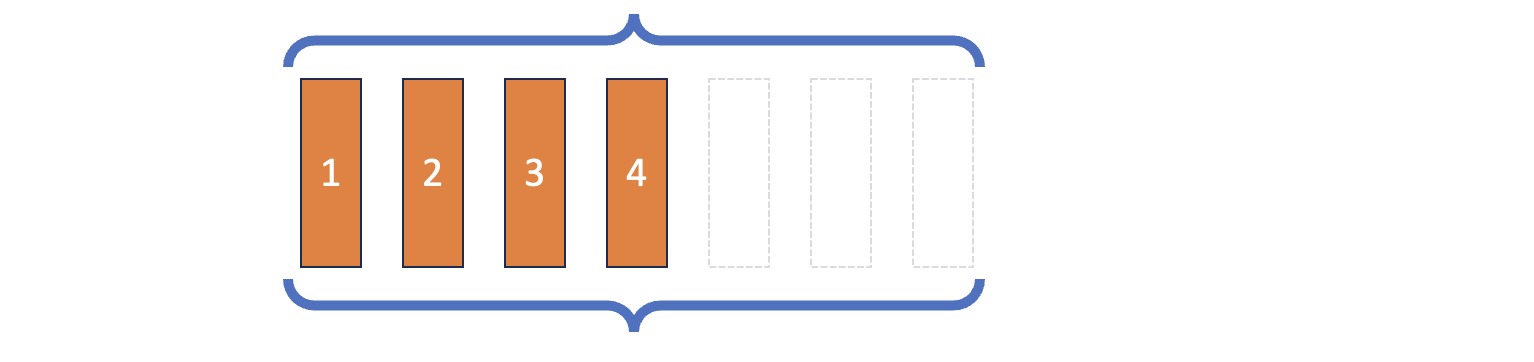
# Instantiate with limited capacity buffer = deque([1,2,3,4], maxlen=7)
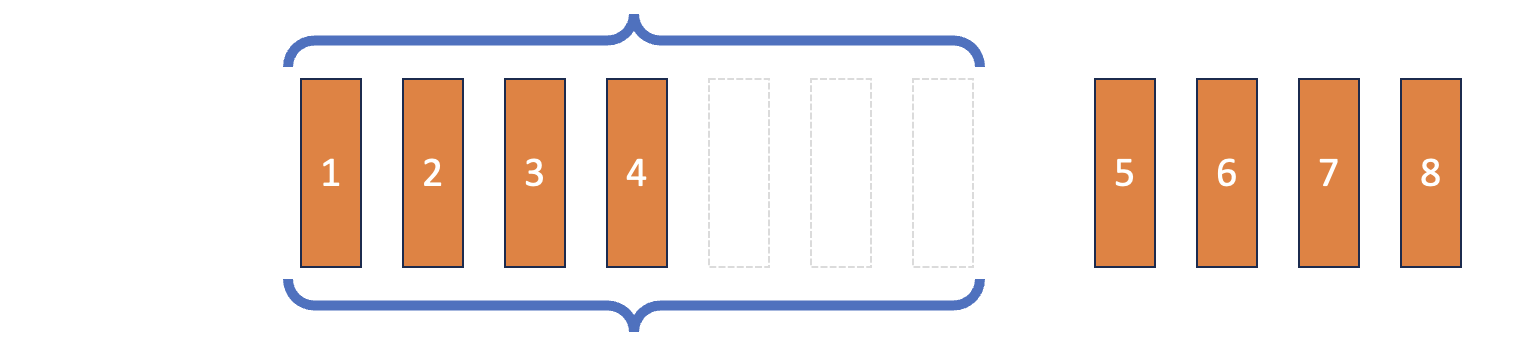
# Extend to the right side buffer.extend([5,6,7,8])
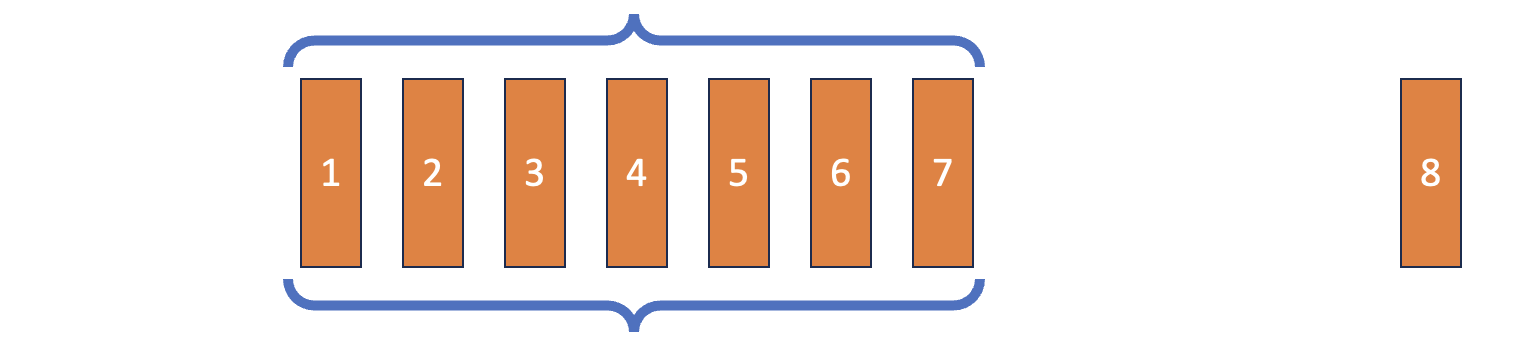
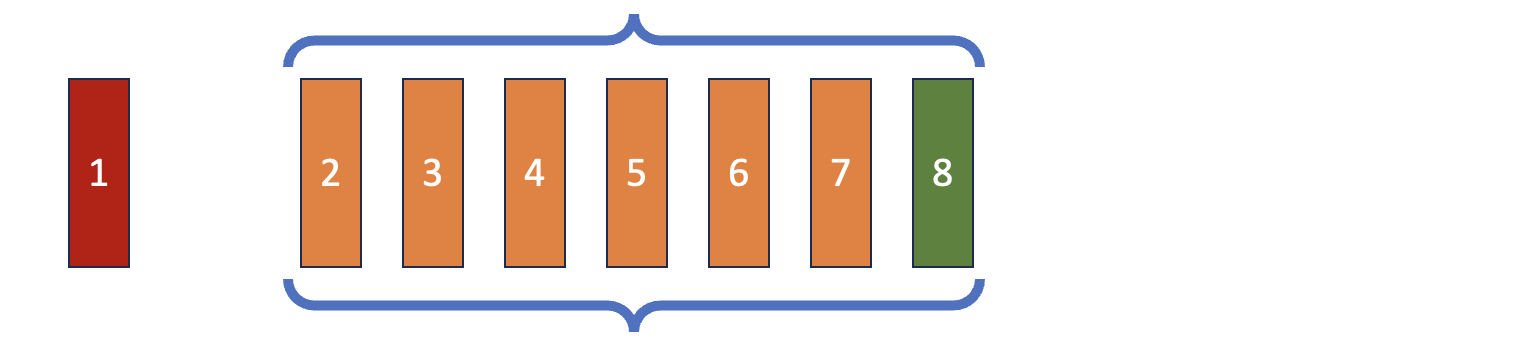
  • 超出容量时,最旧元素被丢弃

容量为 7 的 deque,含 1 到 4 四个元素。

容量为 7 的 deque,含 1 到 4。右侧可见 5 到 8 四个元素。

容量为 7 的 deque,含 1 到 7 七个元素。右侧可见元素 8。

容量为 7 的 deque,含 2 到 8 七个元素。左侧可见元素 1。

Python 中的深度强化学习

实现 Replay Buffer

import random

class ReplayBuffer:
def __init__(self, capacity):
self.memory = deque([], maxlen=capacity)
def push(self, state, action, reward, next_state, done):
experience_tuple = (state, action, reward, next_state, done)
self.memory.append(experience_tuple)
def __len__(self): return len(self.memory)
...
  • 回放内存:有限容量的 deque
  • .push():
    • 用转移元组表示一次经验
    • 追加到缓冲区
    • 达到容量时:丢弃最旧经验
Python 中的深度强化学习

实现 Replay Buffer

...
def sample(self, batch_size):

batch = random.sample(self.memory, batch_size)
states, actions, rewards, next_states, dones = ( zip(*batch))
states_tensor = torch.tensor( states, dtype=torch.float32) ... # repeat identically for # rewards, next_states, dones
actions_tensor = torch.tensor( actions, dtype=torch.long).unsqueeze(1)
return states_tensor, actions_tensor, rewards_tensor, next_states_tensor, dones_tensor


  • 从历史经验中随机抽样
  • batch:由转移元组列表…
  • …变为列表的元组…
  • …再变为 PyTorch 张量的元组
Python 中的深度强化学习

在 DQN 中集成经验回放

  1. 训练前:replay_buffer = ReplayBuffer(10000)

  2. 训练中,选动作后:

replay_buffer.push((state, action, 
                    reward, next_state, done))

if len(replay_buffer) >= batch_size:
states, actions, rewards, next_states, dones = ( replay_buffer.sample(batch_size))
q_values = ( q_network(states).gather(1, actions).squeeze(1))
next_states_q_values = q_network(next_states).amax(1)
target_q_values = ( rewards + gamma * next_states_q_values * (1-dones))
loss = nn.MSELoss()(target_q_values, q_values)
  • 初始化重放缓冲区
  • 将最新转移推入缓冲区

当缓冲区长度 ≥ batch_size:

  • 随机采样一批并计算损失
  • 损失计算思路不变
  • 重放批上的均方贝尔曼误差
    • 学习更稳定、更高效
Python 中的深度强化学习

Passons à la pratique !

Python 中的深度强化学习

Preparing Video For Download...