课程导入与动机
R 中的欺诈检测

Bart Baesens
Professor Data Science at KU Leuven
讲师
讲师
讲师
什么是欺诈?
欺诈是一种罕见、深思熟虑、隐蔽、随时间演变且常被精心组织的犯罪,形式多样。
成功的欺诈分析模型的关键特征
成功的欺诈分析模型的关键特征
成功的欺诈分析模型的关键特征
成功的欺诈分析模型的关键特征
成功的欺诈分析模型的关键特征
欺诈检测模型的挑战
欺诈检测模型的挑战
欺诈检测模型的挑战
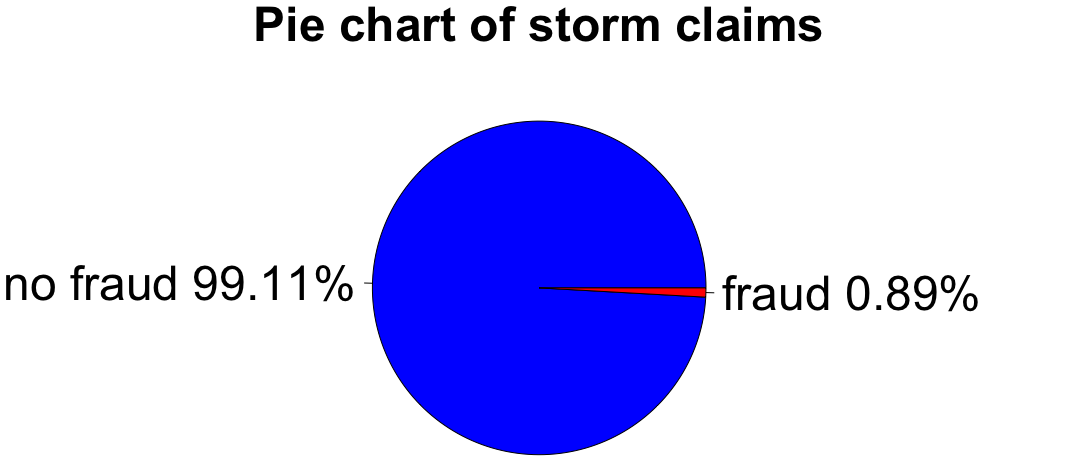
用饼图展示不平衡
labels <- c("no fraud", "fraud")
labels <- paste(labels, round(100 * prop.table(table(fraud_label)), 2), "%")
pie(table(fraud_label), labels, col = c("blue", "red"),
      main = "Pie chart of storm claims")
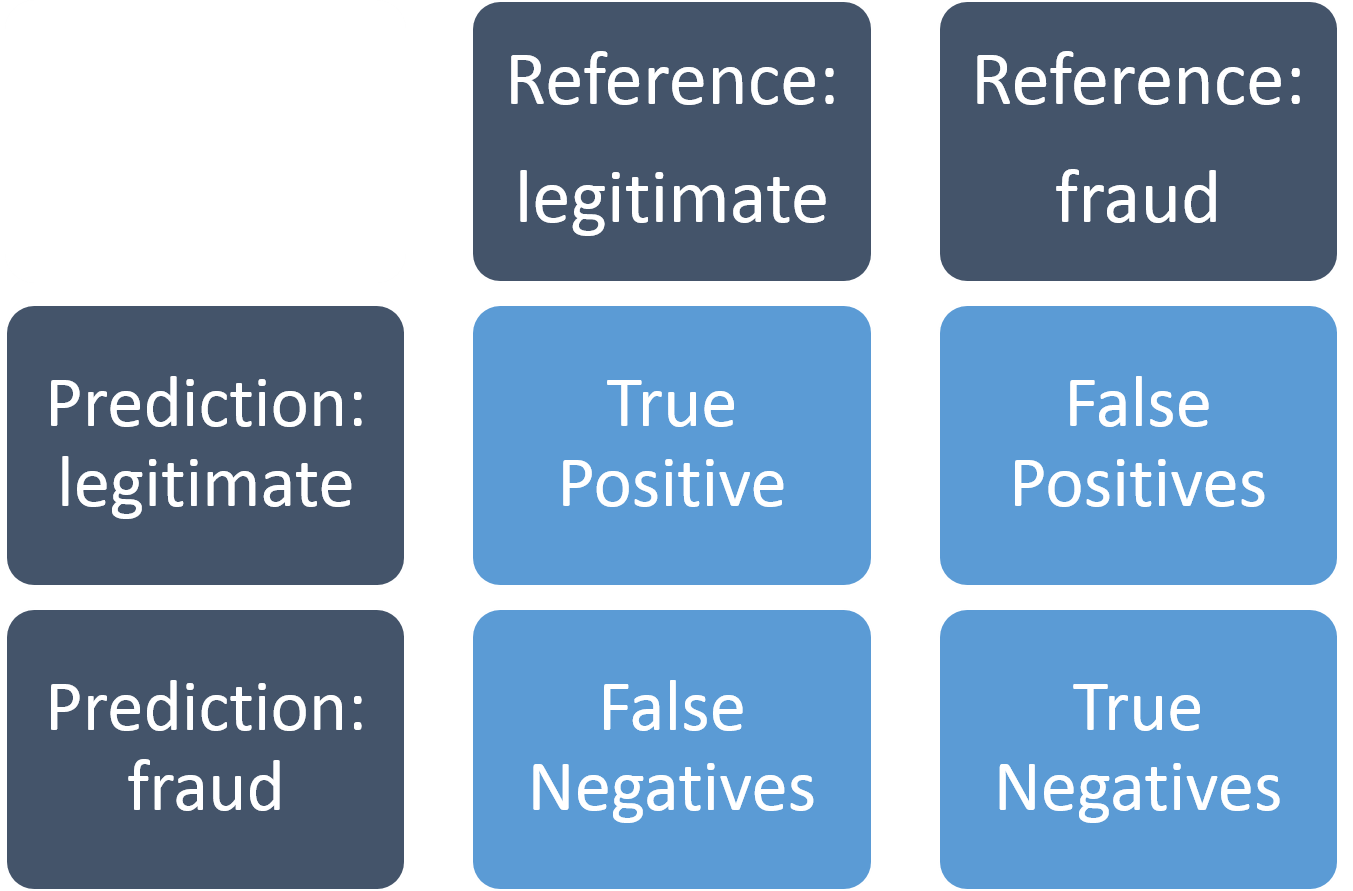
混淆矩阵
用于评估欺诈检测模型: