构建延迟管道
Python 中的 Dask 并行编程

James Fulton
Climate Informatics Researcher
数据分块
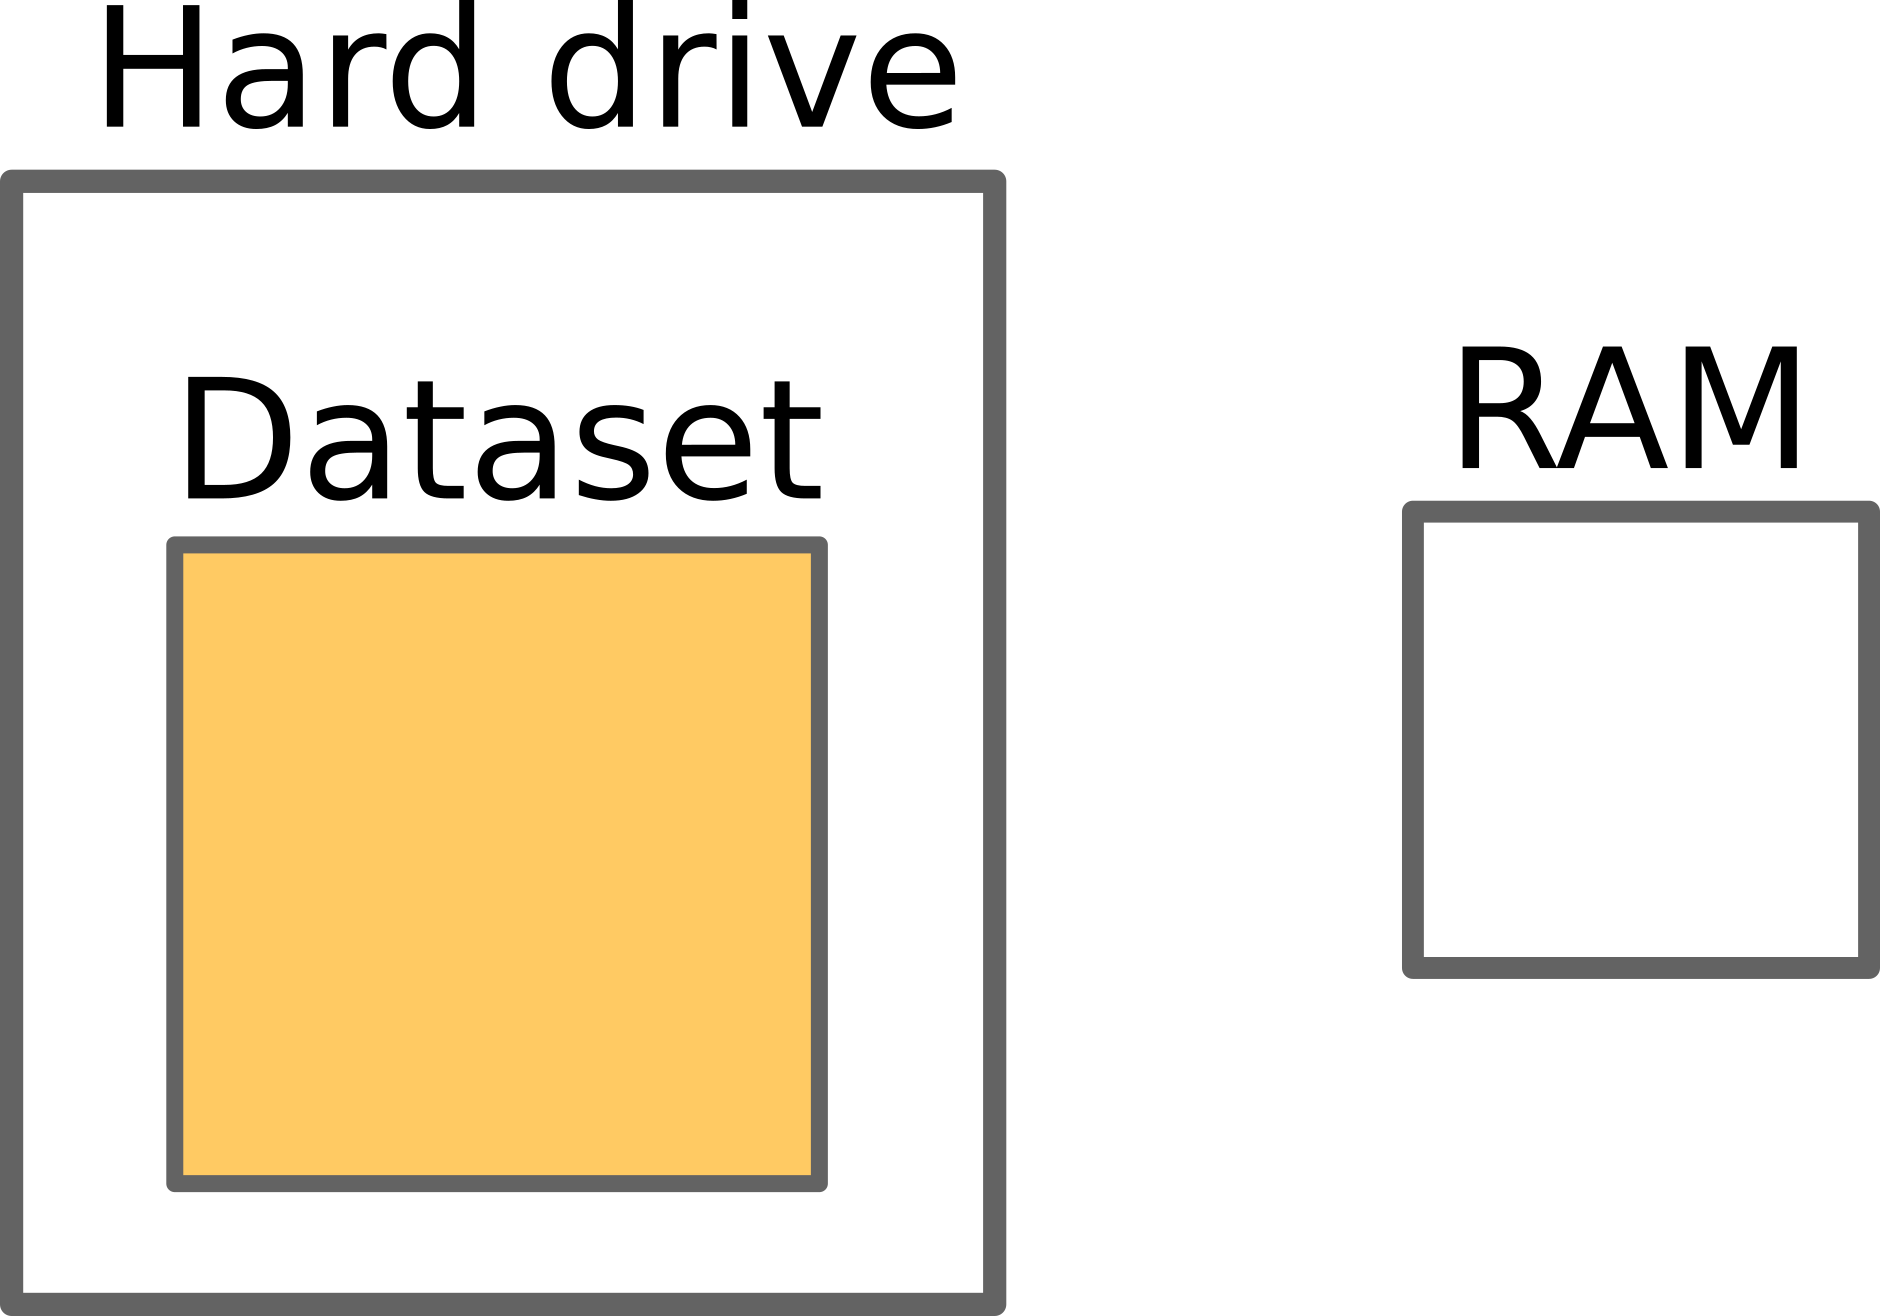
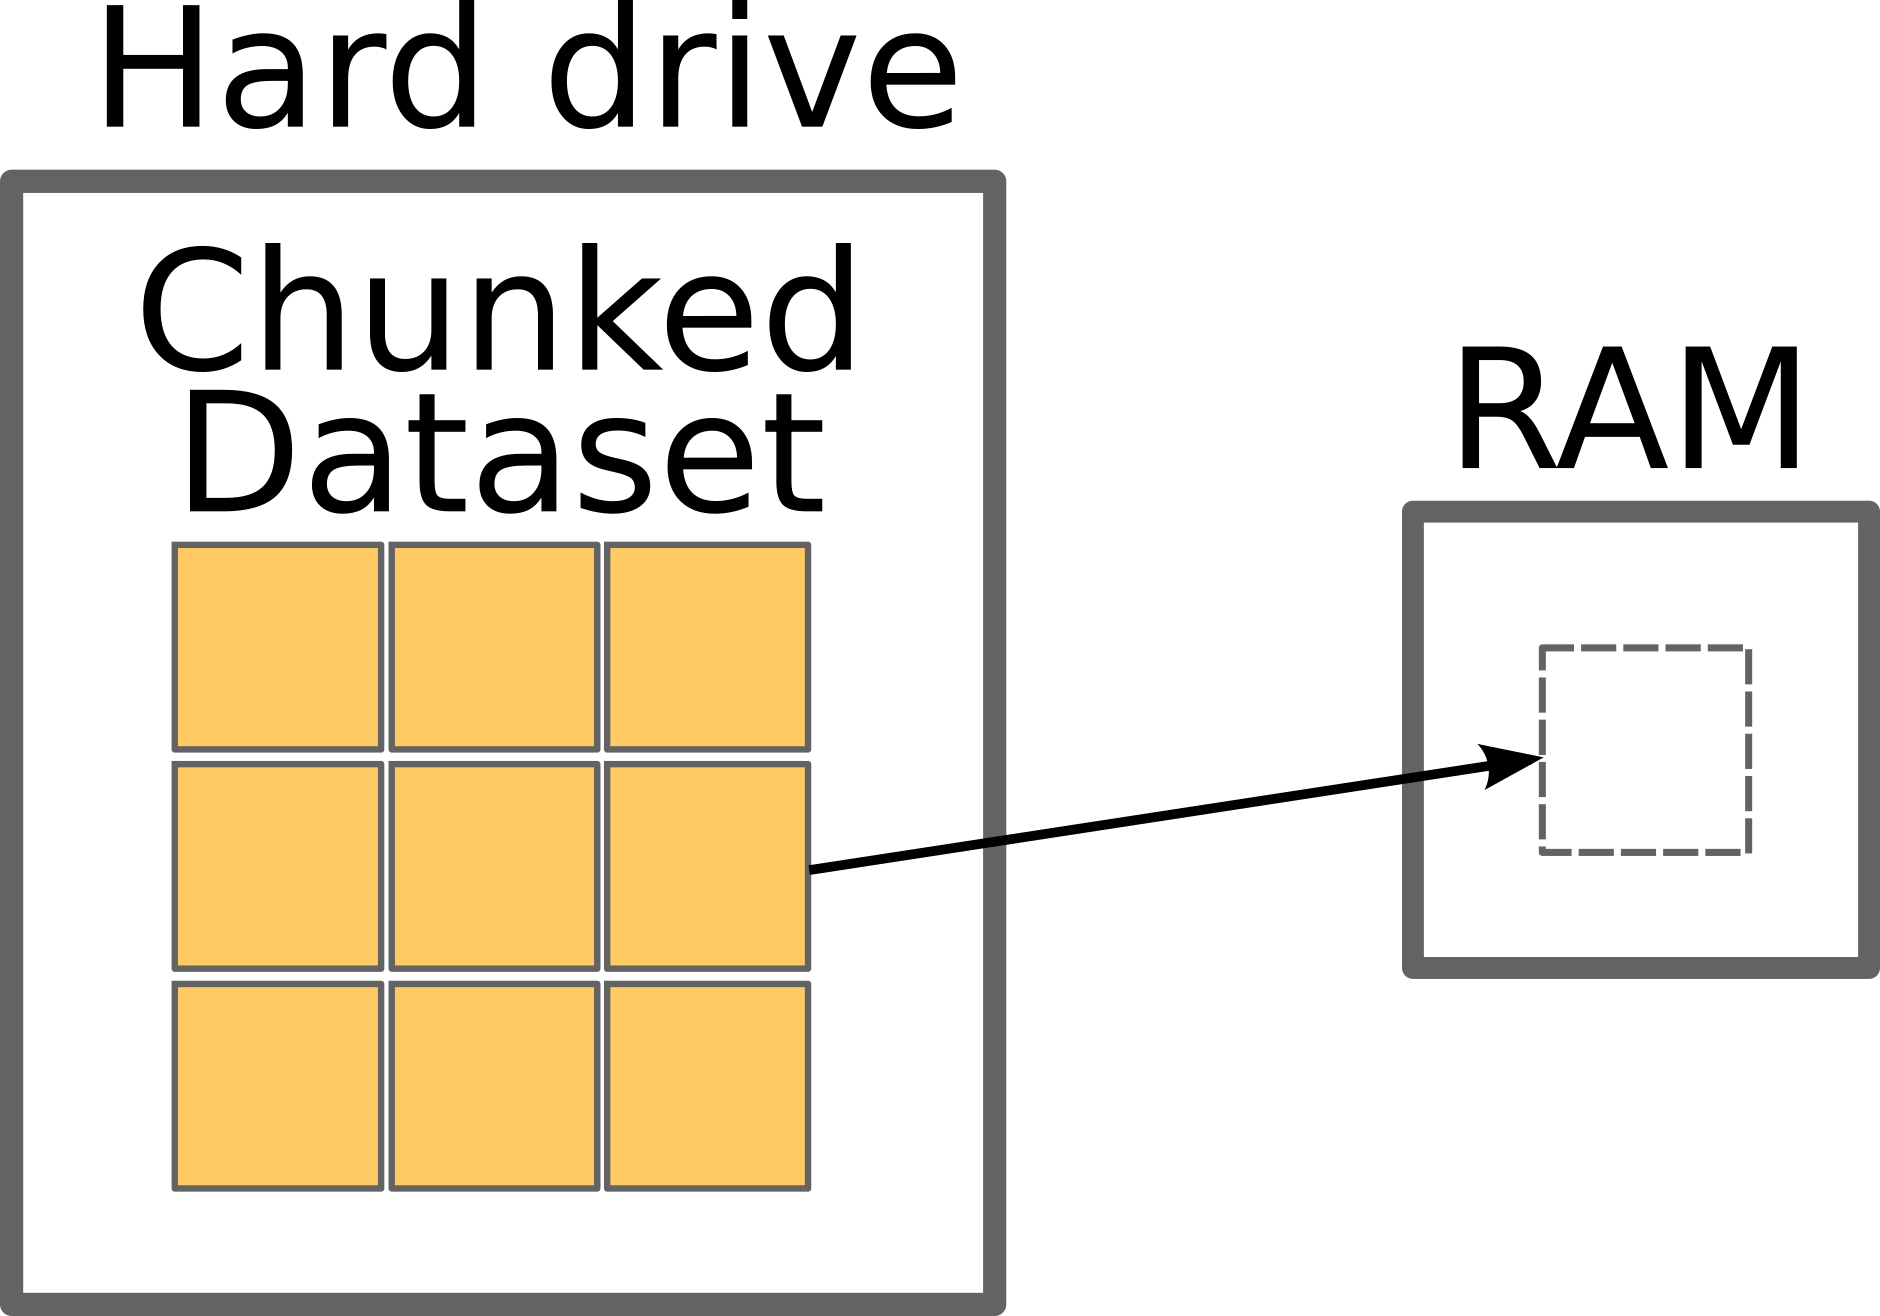
Spotify 歌曲数据集
files = [
  '2005_tracks.csv',
  '2006_tracks.csv',
  '2007_tracks.csv',
  '2008_tracks.csv',
  '2009_tracks.csv',
  '2010_tracks.csv',
  ...
  '2020_tracks.csv',
]
Spotify 歌曲数据集
                       name  duration_ms release_date  ...
0     Aldrig (feat. Carmon)       247869   2019-01-01  ...
2  2019 - The Year to Build       288105   2019-01-01  ...
3                 Na zawsze       186812   2019-01-01  ...
4         Humo en la Trampa       258354   2019-01-01  ...
5                     Au Au       176000   2019-01-01  ...
...                     ...          ...          ...  ...
数据分析
import pandas as pd maximums = [] for file in files: # 读取每个文件 df = pd.read_csv(file)# 查找每个文件中的最大曲长 max_length = df['duration_ms'].max()# 存储该最大值 maximums.append(max_length)# 在所有最大值中取最大 absolute_maximum = max(maximums)
数据分析
import pandas as pd

maximums = []

for file in files:
    # 读取每个文件
    df = delayed(pd.read_csv)(file) # <------- 延迟加载
    # 查找每个文件中的最大曲长
    max_length = df['duration_ms'].max()
    # 存储该最大值
    maximums.append(max_length)

# 在所有最大值中取最大
absolute_maximum = max(maximums)
数据分析
import pandas as pd

maximums = []

for file in files:
    # 读取每个文件
    df = delayed(pd.read_csv)(file) # <------- 延迟加载
    # 查找每个文件中的最大曲长
    max_length = df['duration_ms'].max()
    # 存储该最大值
    maximums.append(max_length)

# 在所有最大值中取最大
absolute_maximum = delayed(max)(maximums) # <------- 延迟 max() 函数
使用延迟对象的方法
import pandas as pd

maximums = []

for file in files:
    df = delayed(pd.read_csv)(file)
    # 使用 .max() 方法
    max_length = df['duration_ms'].max()

    maximums.append(max_length)


absolute_maximum = delayed(max)(maximums)
print(max_length)
Delayed('max-0602855d-3ee6-4c43-a4d2-...')
- 延迟对象的方法和属性会返回新的延迟对象
print(df.shape)
print(df.shape.compute())
Delayed('getattr-bc1e8838ab...')
(11907, 12)
使用延迟对象的方法
import pandas as pd

maximums = []

for file in files:
    df = delayed(pd.read_csv)(file)
    # 使用不存在的方法
    max_length = df['duration_ms'].fake()

    maximums.append(max_length)


absolute_maximum = delayed(max)(maximums)
print(max_length)
Delayed('max-6c026036-5daf-4b2-...')
- 仅在调用
.compute()后才会执行方法
print(max_length.compute())
...
AttributeError: 'Series' object has no
attribute 'fake'
使用延迟对象的方法
import pandas as pd

maximums = []

for file in files:
    df = delayed(pd.read_csv)(file)

    max_length = df['duration_ms'].max()
    # 将延迟对象加入列表
    maximums.append(max_length)

# 对延迟对象列表执行延迟 max
absolute_maximum = delayed(max)(maximums)
maximums 是延迟对象的列表
print(maximums)
[Delayed('max-80b...'),
Delayed('max-fa15d...',
...]
计算延迟对象列表
import pandas as pd

maximums = []

for file in files:
    df = delayed(pd.read_csv)(file)

    max_length = df['duration_ms'].max()
    # 将延迟对象加入列表(拼写错误原样保留)
    maximums.append(max_length)

# 计算所有最大值
all_maximums = dask.compute(maximums)
print(all_maximums)
([2539418, 4368000, ...
... 4511716, 4864333],)
计算延迟对象列表
import pandas as pd

maximums = []

for file in files:
    df = delayed(pd.read_csv)(file)

    max_length = df['duration_ms'].max()

    maximums.append(max_length)

# 计算所有最大值
all_maximums = dask.compute(maximums)[0]
print(all_maximums)
[2539418, 4368000, ...
... 4511716, 4864333]
是否需要延迟
def get_max_track(df):
    return df['duration_ms'].max()

for file in files:
    df = delayed(pd.read_csv)(file)
    # 用函数求最大值
    max_length = get_max_track(df)

    maximums.append(max_length)


absolute_maximum = delayed(max)(maximums)
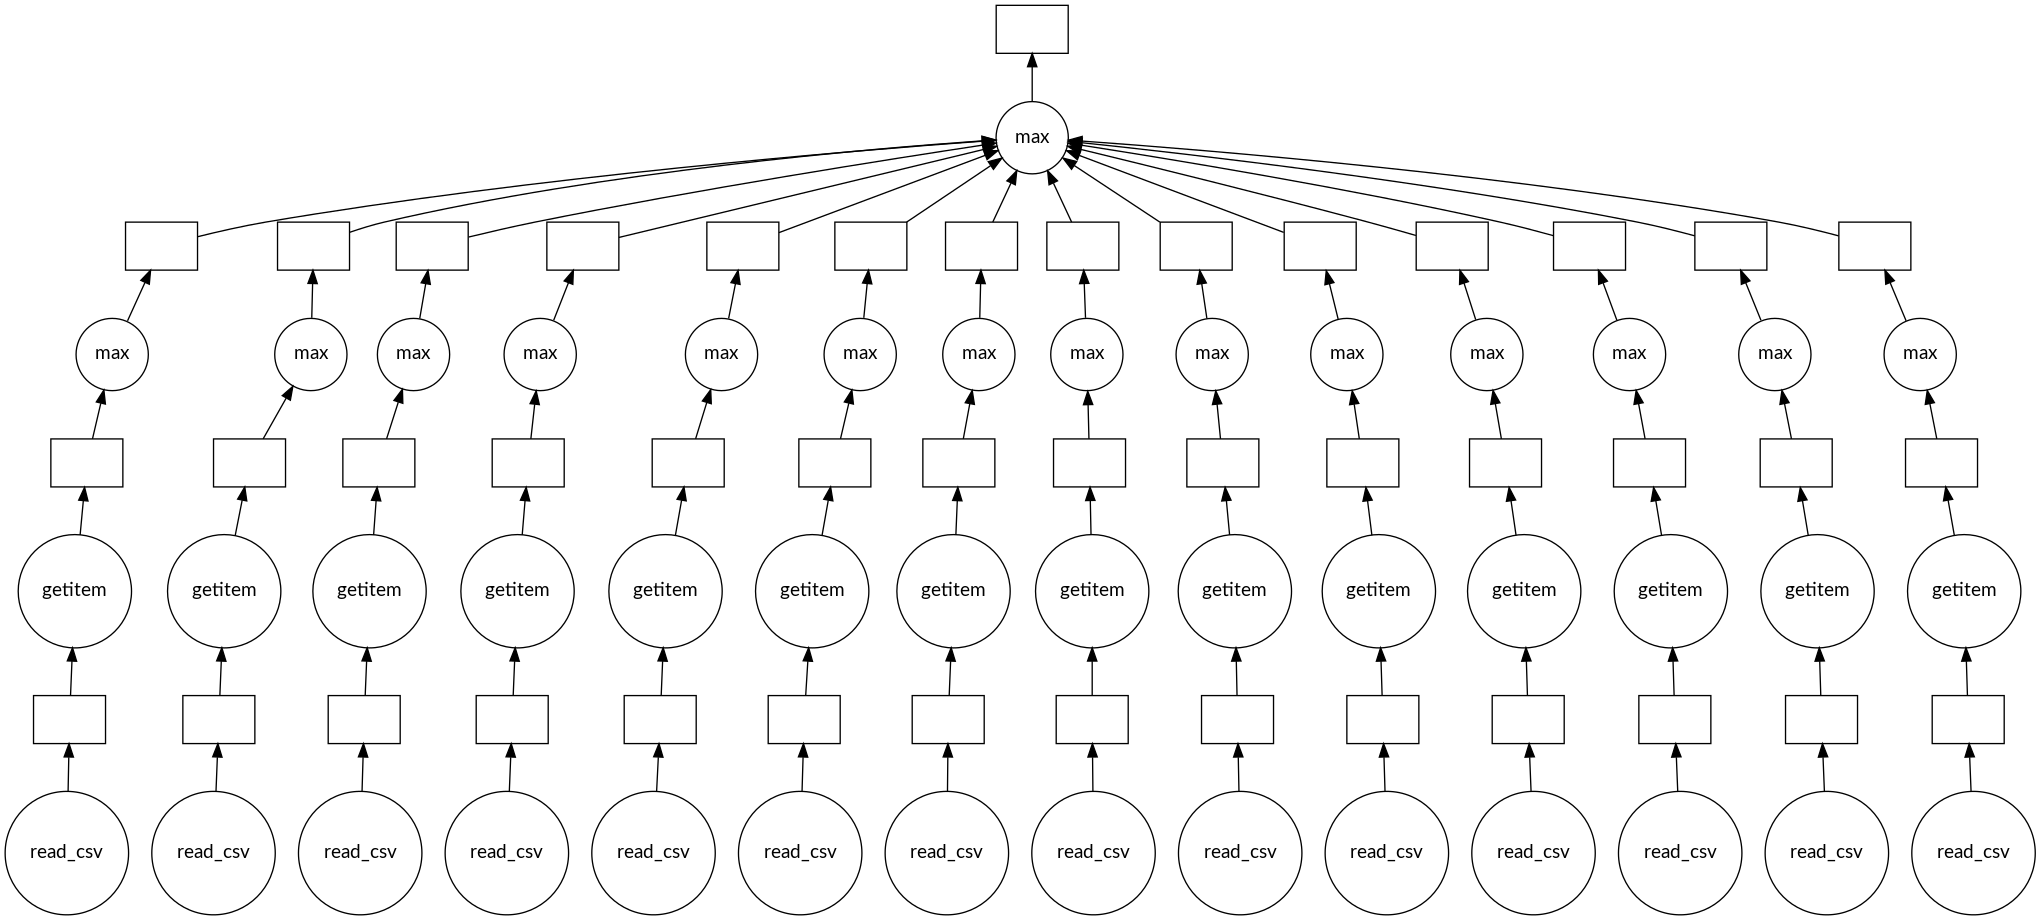
更深的任务图
absolute_maximum.visualize()
Passons à la pratique !
Python 中的 Dask 并行编程

