推文的主题建模

用 R 分析社交媒体数据

Vivek Vijayaraghavan

Data Science Coach

课程概览

  • 主题建模基础
  • 创建文档-词项矩阵(DTM)
  • 基于 DTM 构建主题模型
用 R 分析社交媒体数据

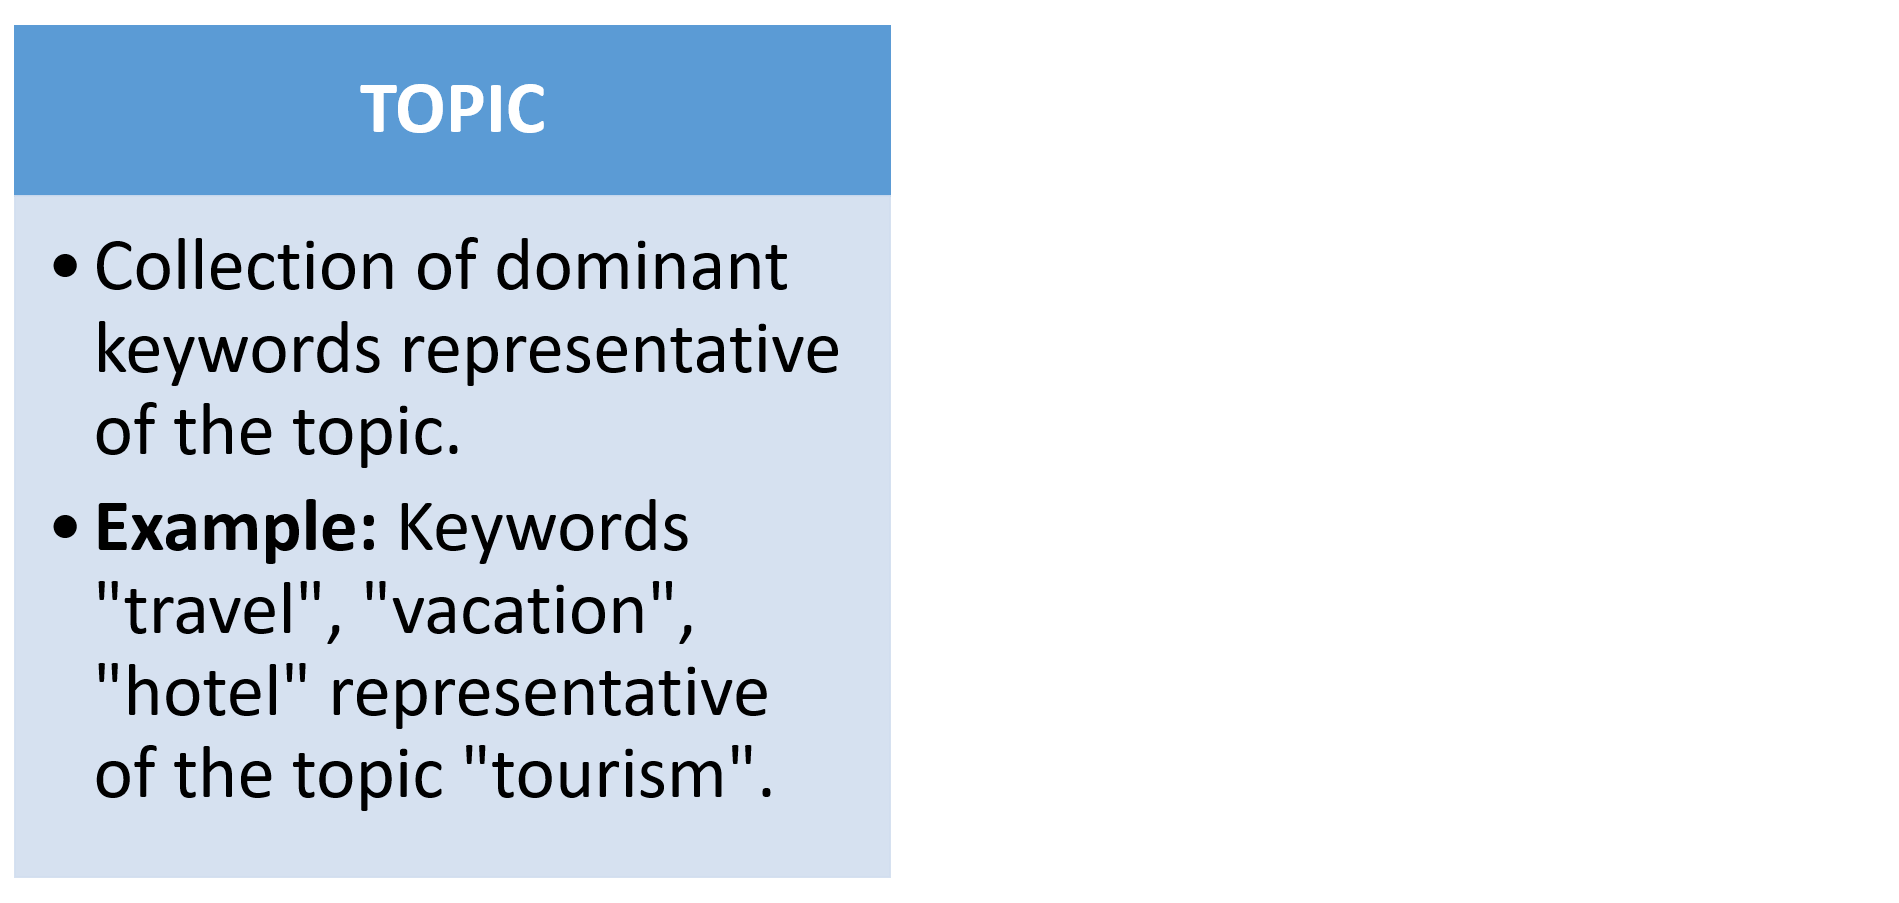
主题与文档

主题定义与示例

用 R 分析社交媒体数据

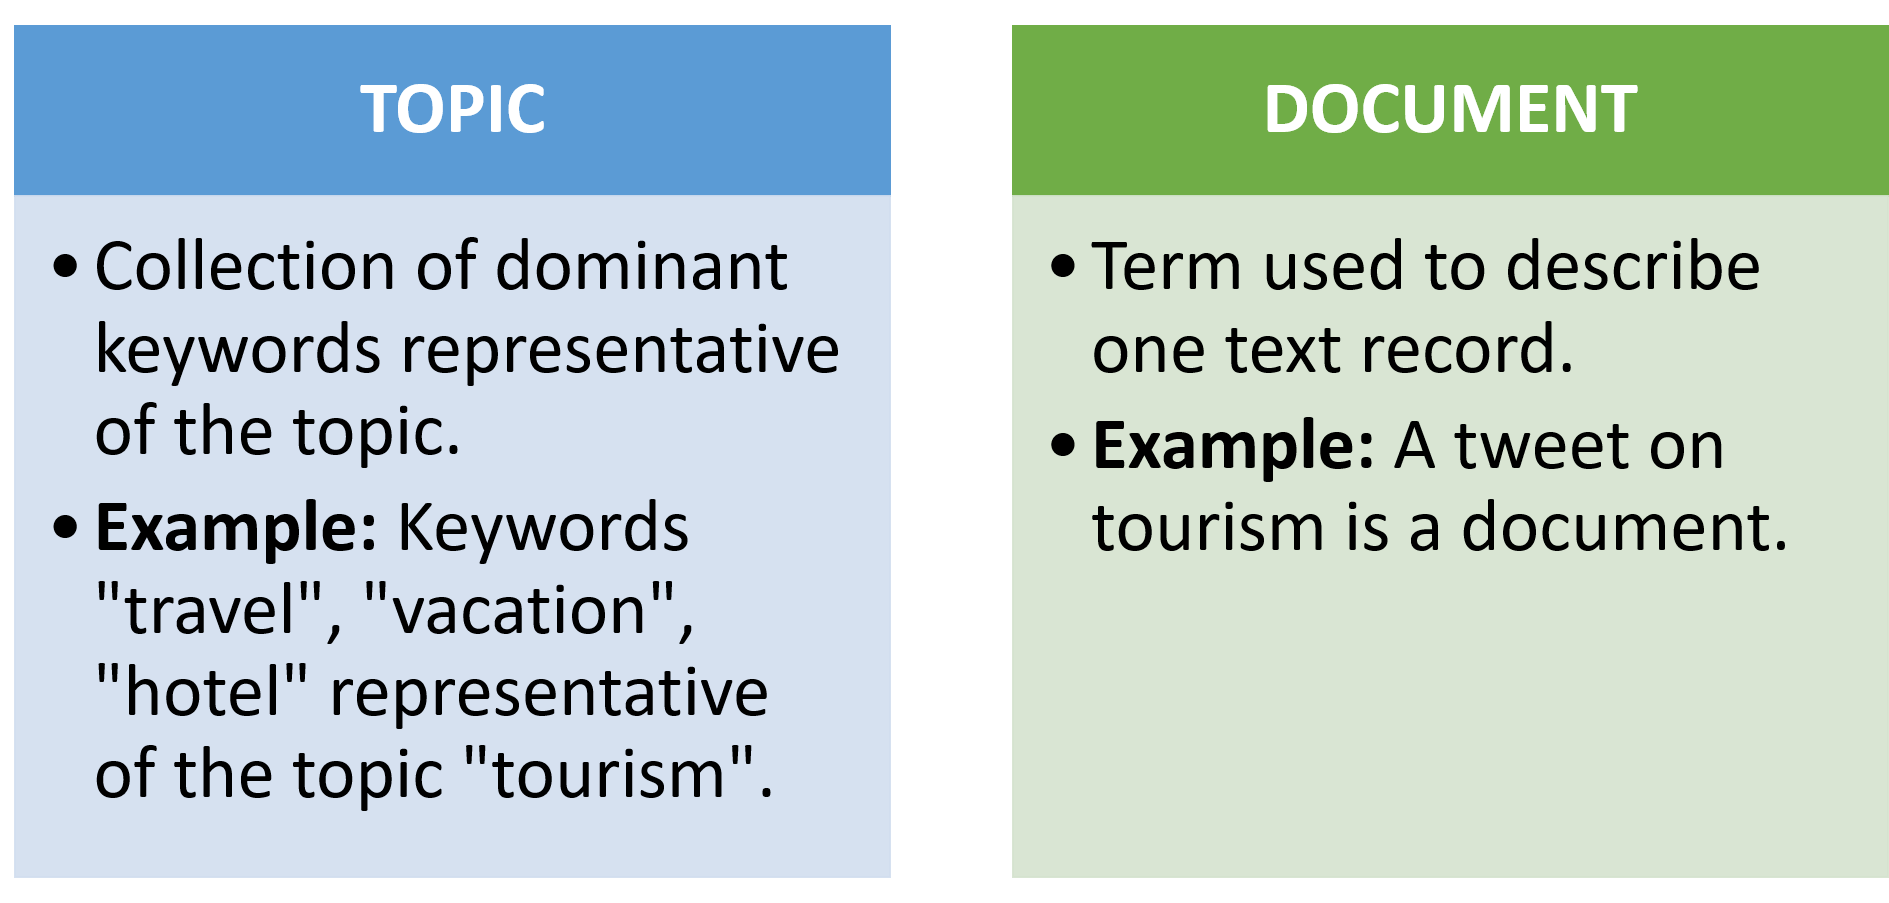
主题与文档

文档定义与示例

用 R 分析社交媒体数据

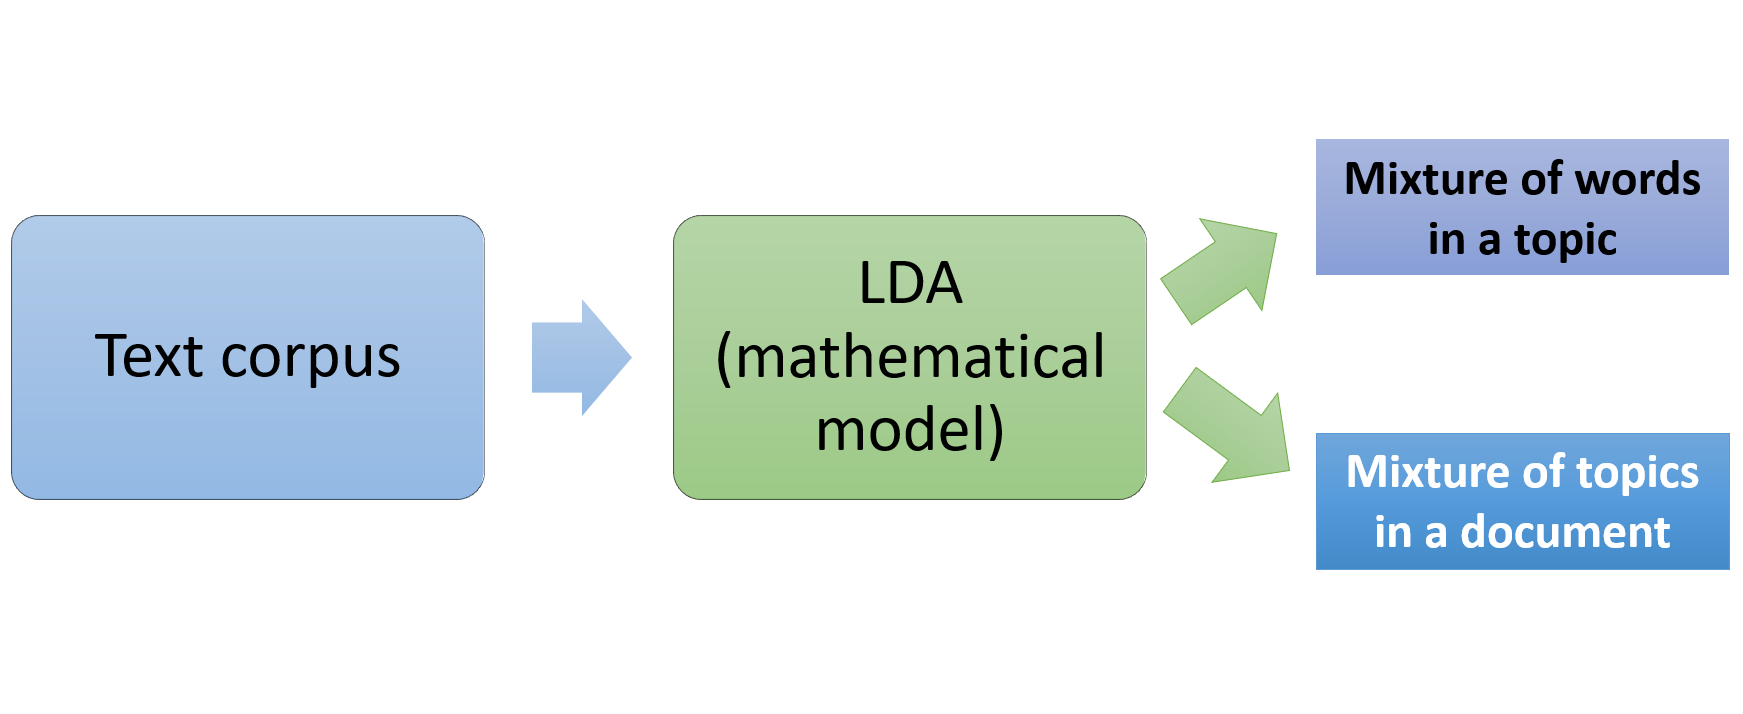
主题建模

  • 自动发现主题的任务
  • 从大型数据中提取核心讨论主题
  • 快速将海量信息归纳为主题
用 R 分析社交媒体数据

LDA 的工作原理

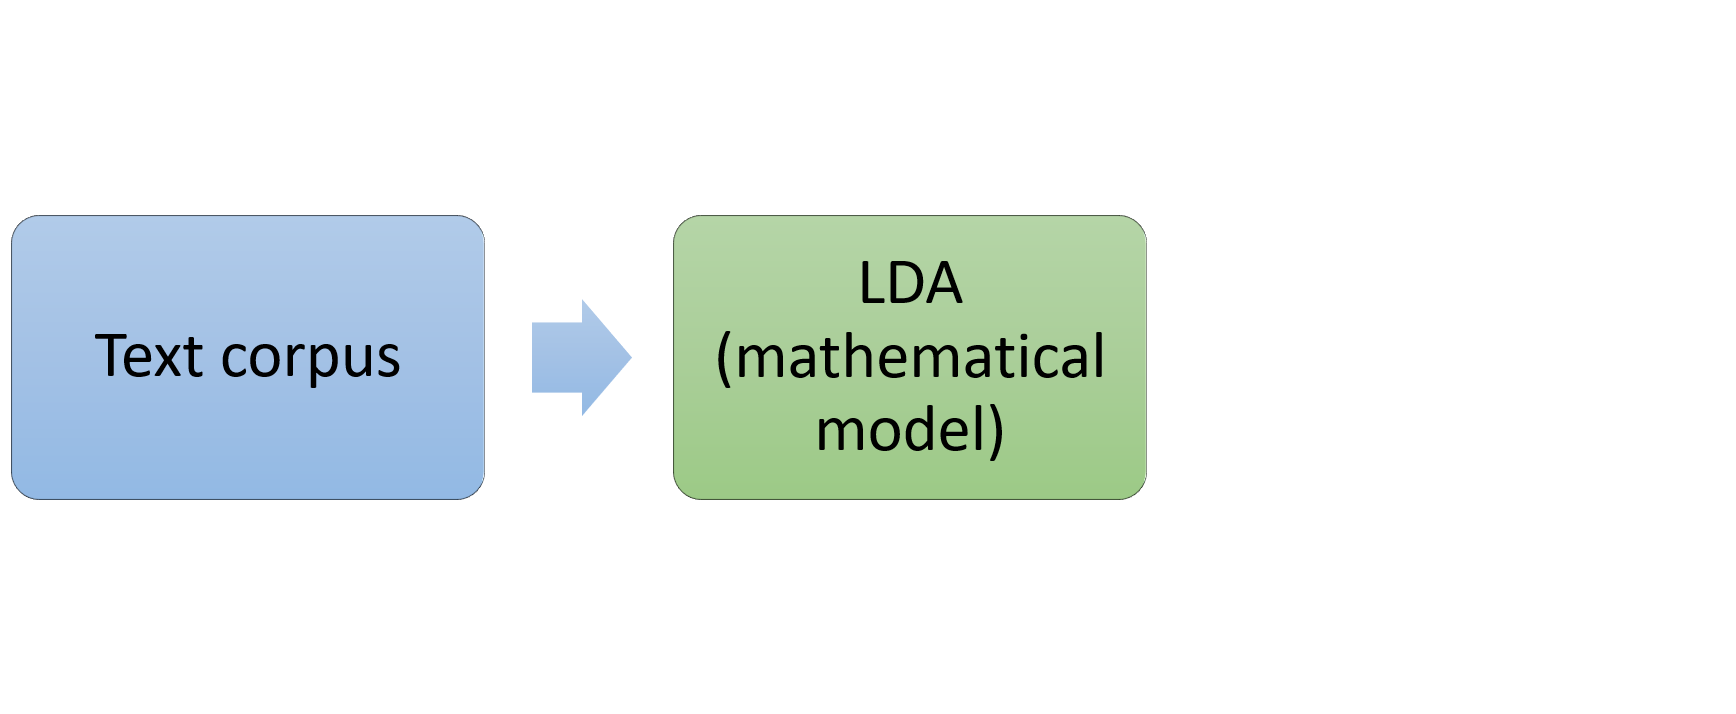
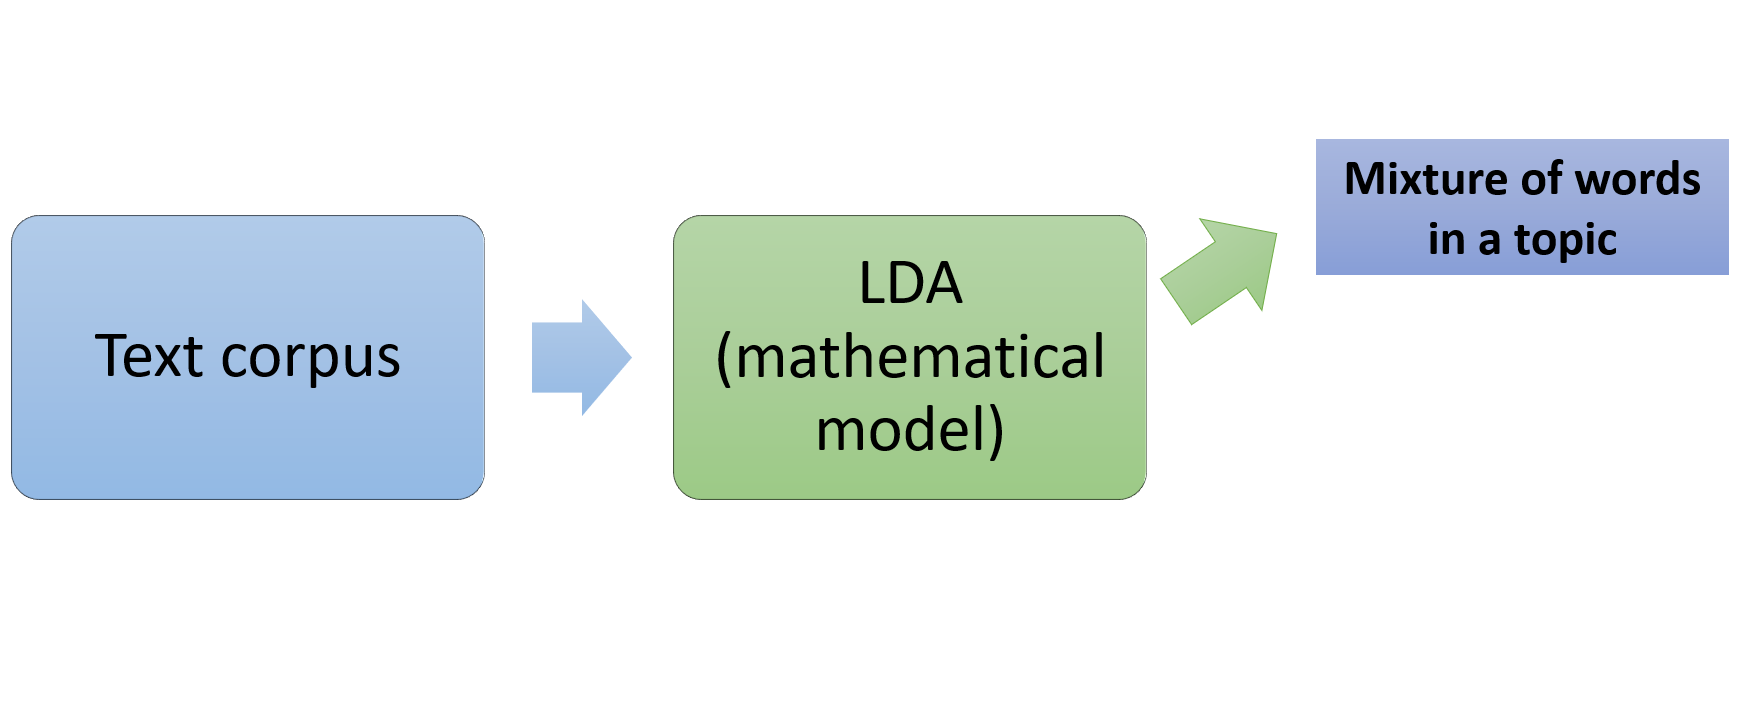
  • 用潜在狄利克雷分配(LDA)进行主题建模

LDA 的工作原理

用 R 分析社交媒体数据

LDA 的工作原理

LDA 的工作原理

用 R 分析社交媒体数据

LDA 的工作原理

LDA 的工作原理

用 R 分析社交媒体数据

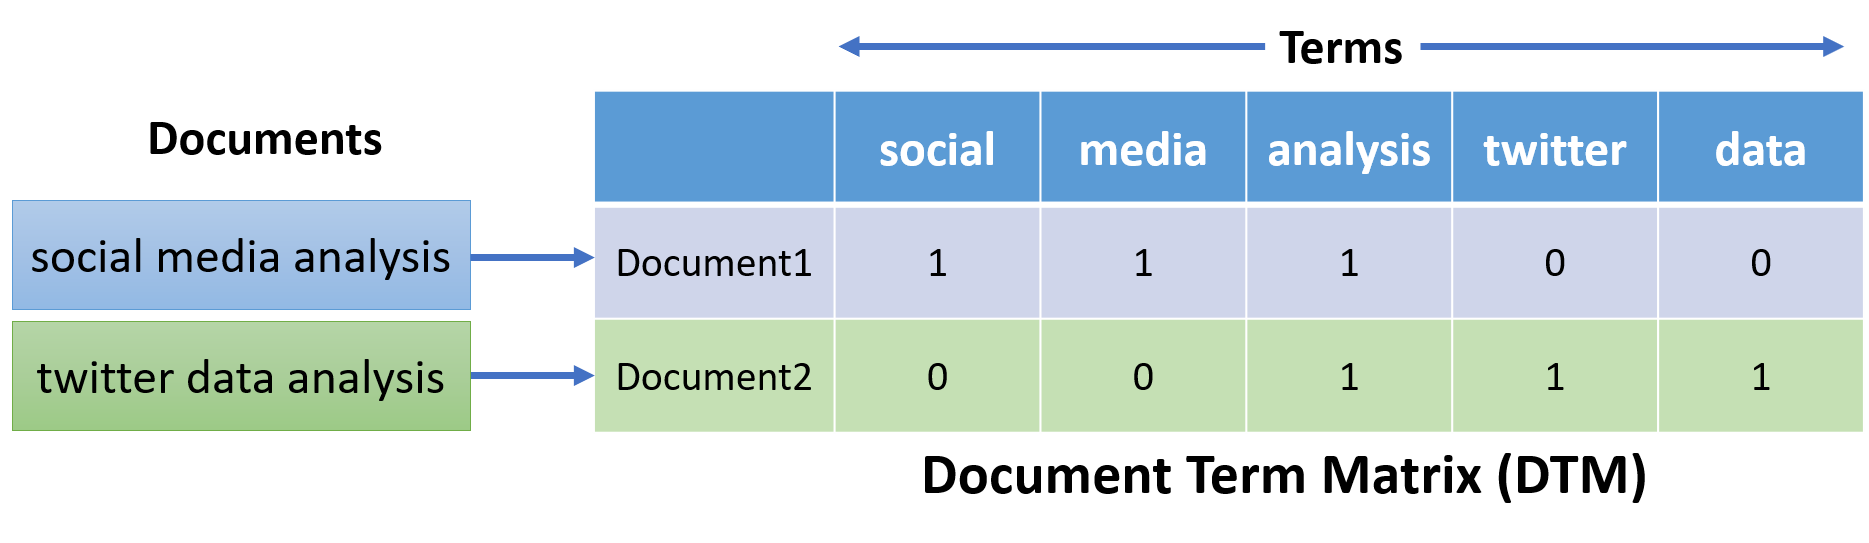
文档-词项矩阵(DTM)

  • 创建文档-词项矩阵(DTM)
  • DTM 是语料库的矩阵表示
  • 文档为行,单词/词项为列

文档-词项矩阵(DTM)

用 R 分析社交媒体数据

创建文档-词项矩阵

# Create a document term matrix
dtm <- DocumentTermMatrix(twt_corpus_refined)
用 R 分析社交媒体数据

创建文档-词项矩阵

# Inspect the DTM
inspect(dtm)
用 R 分析社交媒体数据

创建文档-词项矩阵

<<DocumentTermMatrix (documents: 1000, terms: 5079)>>
Non-/sparse entries: 12862/5066138
Sparsity           : 100%
Maximal term length: 29
Weighting          : term frequency (tf)
Sample             :
     Terms
Docs    california child diabetes fat food health people ranks rates weight
  131          0     0        0   0    0      0      0     0     0      0
  161          0     0        0   2    0      0      0     0     0      1
  295          0     0        0   0    1      0      1     0     0      0
  418          0     0        0   0    0      0      0     0     1      0
  604          0     0        1   0    0      1      0     0     0      0
用 R 分析社交媒体数据

准备 DTM

  • 过滤 DTM:仅保留行和大于 0 的文档
# Find the sum of word counts in each Document 
rowTotals <- apply(dtm , 1, sum)
# Select rows from DTM with row totals greater than zero
tweet_dtm_new <- dtm[rowTotals> 0, ]
用 R 分析社交媒体数据

构建主题模型

  • 使用 LDA() 创建主题模型
# Build the topic model
library(topicmodels)
lda_5 <- LDA(tweet_dtm_new, k = 5)
用 R 分析社交媒体数据

构建主题模型

  • 从推文语料中提取 5 个主题
# View top 10 terms in the topic model
top_10terms <- terms(lda_5,10)
top_10terms
用 R 分析社交媒体数据

查看主题模型的前 10 个词

     Topic 1        Topic 2        Topic 3     Topic 4      Topic 5   
 [1,] "disease"      "people"       "black"     "child"      "weight"  
 [2,] "health"       "health"       "fat"       "rates"      "diet"    
 [3,] "cancer"       "diabetes"     "trump"     "ranks"      "food"    
 [4,] "meghanmccain" "overweight"   "childhood" "california" "diabetes"
 [5,] "realcandaceo" "fat"          "health"    "fat"        "health"  
 [6,] "food"         "meghanmccain" "professor" "eat"        "bmi"     
 [7,] "risk"         "realcandaceo" "gender"    "people"     "problem" 
 [8,] "heart"        "body"         "studies"   "epidemic"   "eating"  
 [9,] "weight"       "weight"       "healthy"   "health"     "disease" 
[10,] "diabetes"     "obese"        "problem"   "healthy"    "family"
  • 肥胖管理项目可围绕核心主题设置主线
用 R 分析社交媒体数据

让我们来练习!

用 R 分析社交媒体数据

Preparing Video For Download...