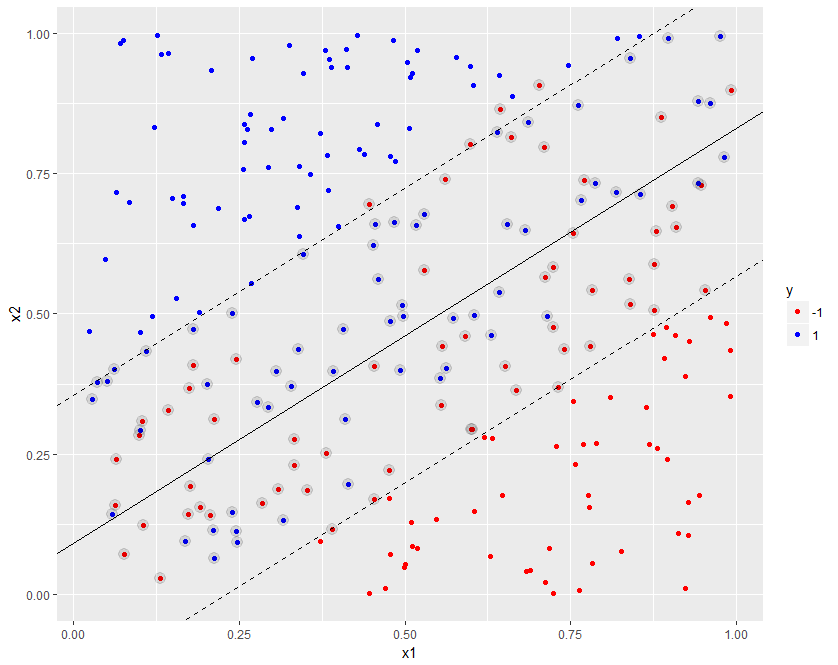
library(e1071)
svm_model <- svm(y ~ .,
                data = trainset,
                type = "C-classification",
                kernel = "linear",
                scale = FALSE)
# Print model summary
svm_model
Call:
svm(formula = y ~ .,
    data = trainset,
    type = "C-classification",
    kernel = "linear",
    scale = FALSE)

Parameters:
SVM-Type:  C-classification
 SVM-Kernel:  linear
       cost:  1
      gamma:  0.5
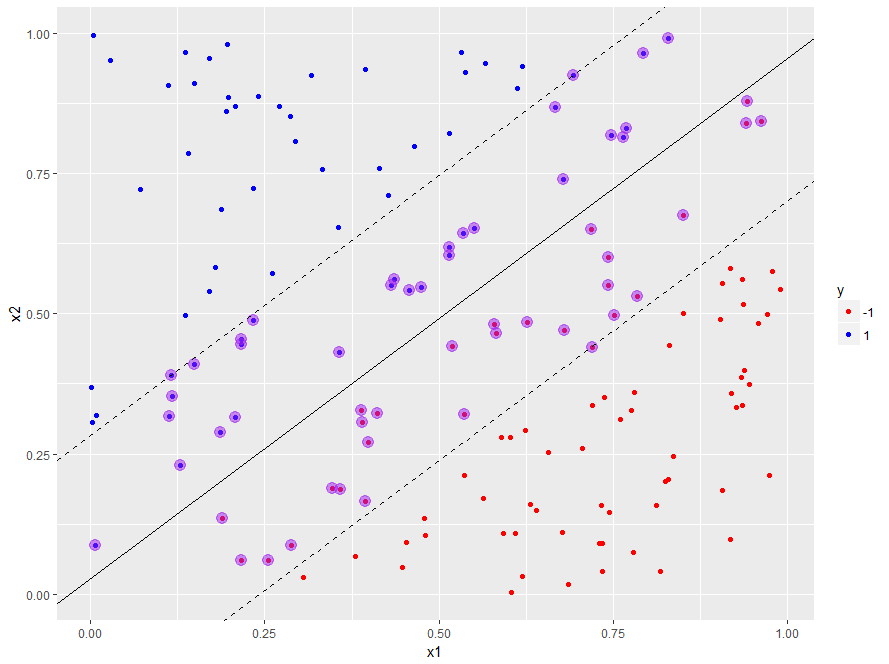
Number of Support Vectors:  55
线性 SVM(cost = 100)
library(e1071)
svm_model <- svm(y ~ .,
                data = trainset,
                type = "C-classification",
                kernel = "linear",
                cost = 100,
                scale = FALSE)
# Print model summary
svm_model
Call:
svm(formula = y ~ .,
    data = trainset,
    type = "C-classification",
    kernel = "linear",
    cost = 100,
    scale = FALSE)

Parameters:
SVM-Type:  C-classification
 SVM-Kernel:  linear
       cost:  100
      gamma:  0.5
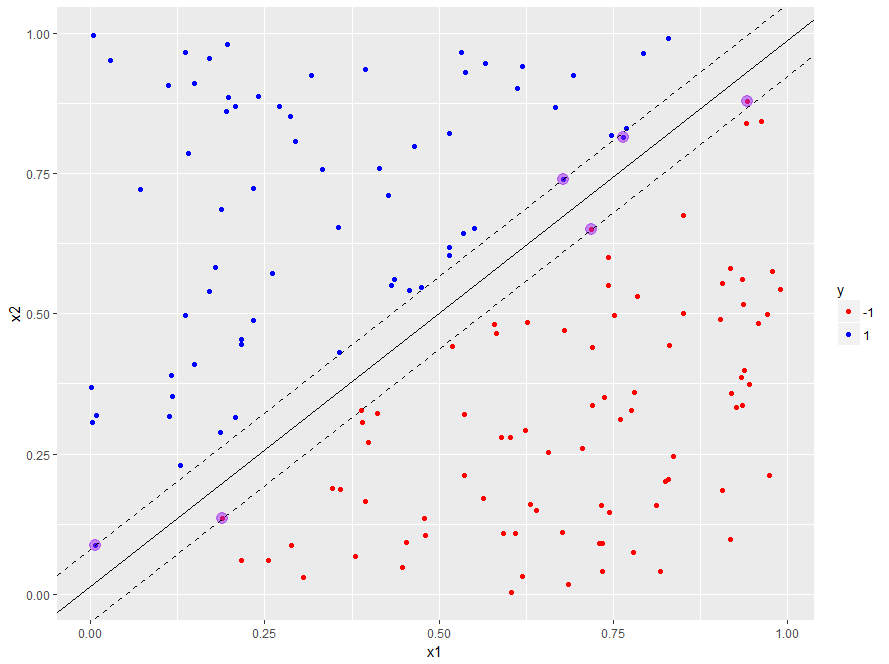
Number of Support Vectors:  6
含义
若已知决策边界为线性,可适当减小间隔
但现实中很少如此
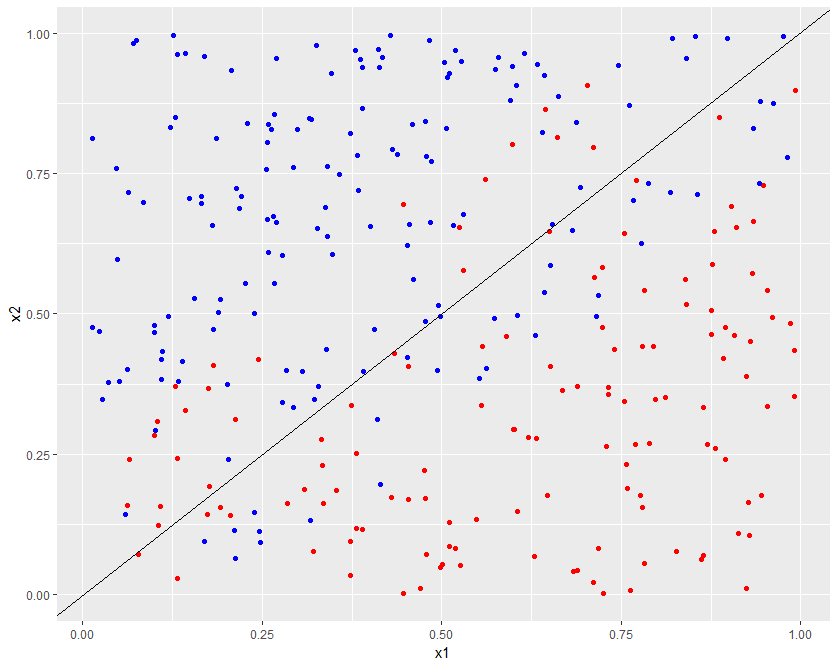
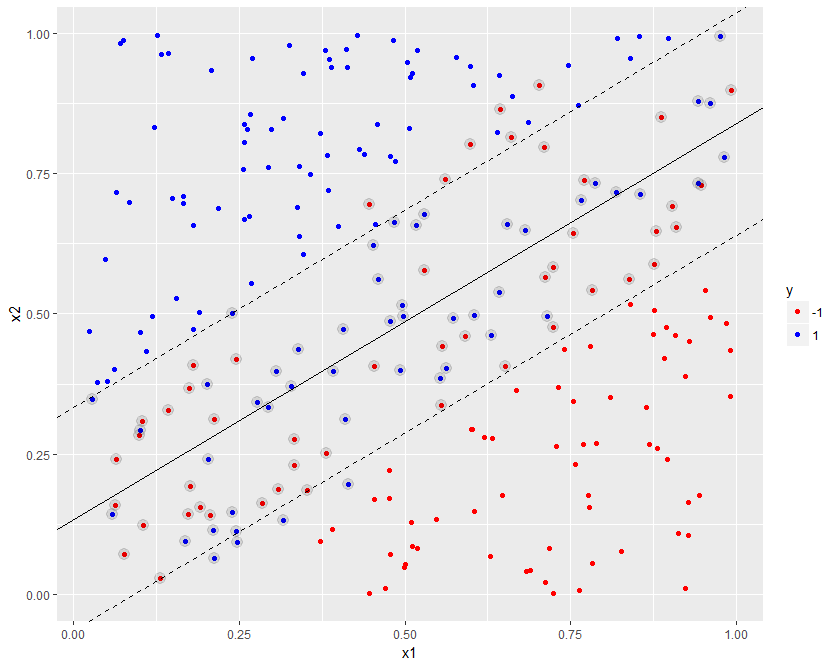
非线性数据集,线性 SVM(cost = 100)
使用 80% 训练集,构建 cost=100 的模型
# Build model
library(e1071)
svm_model<- svm(y ~ .,
                data = trainset,
                type = "C-classification",
                kernel = "linear",
                cost = 100,
                scale = FALSE)
计算准确率
# Train and test accuracy
pred_train <- predict(svm_model, trainset)
mean(pred_train == trainset$y)
# Trainset contains 80% of data
# Same train/test split as before.
# Build model
svm_model <- svm(y ~ .,
data = trainset,
type = "C-classification",
kernel = "linear",
cost = 1,
scale = FALSE)
计算测试集准确率
# Test accuracy
pred_test <- predict(svm_model, testset)
mean(pred_test == testset$y)