Similarități bazate pe text

Construirea motoarelor de recomandare în Python

Rob O'Callaghan

Director of Data

Lucrul fără atribute clare
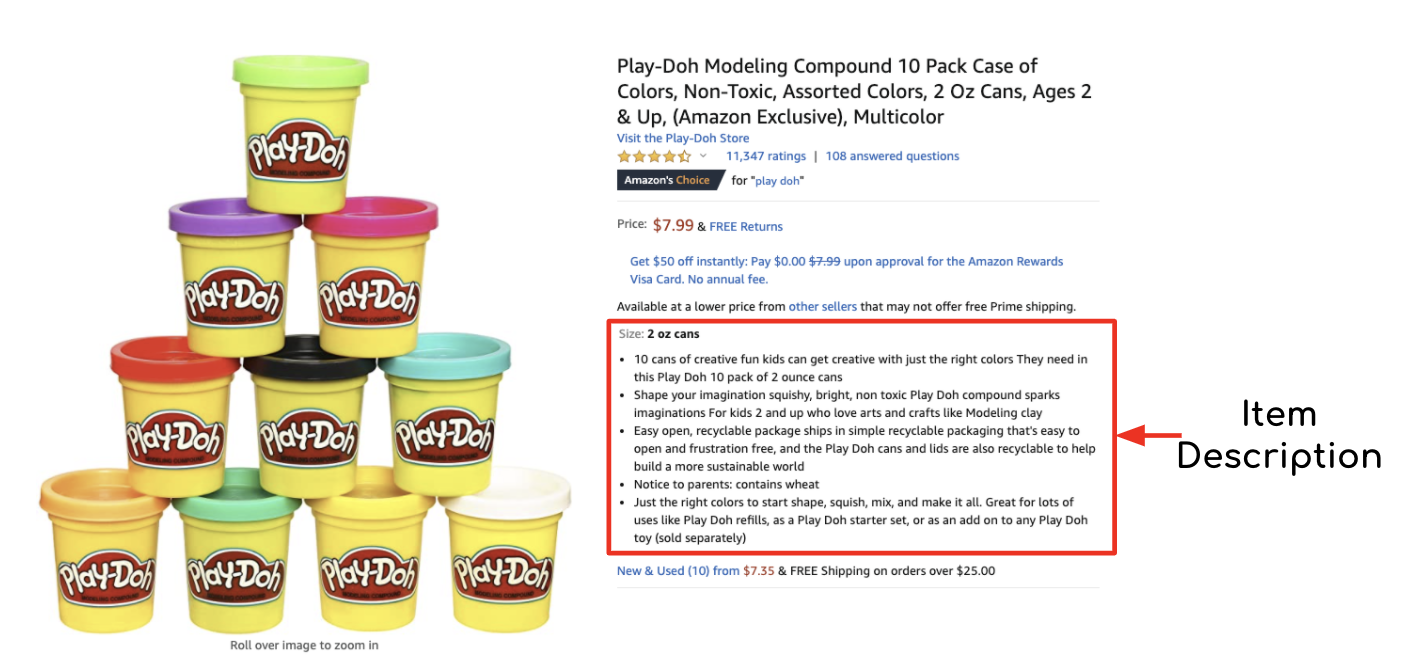
Exemplu de descriere a unui produs pe Amazon.

Construirea motoarelor de recomandare în Python

Frecvența termenului-frecvența inversă a documentului

$$ \Large{\text{TF-IDF} = \frac{\frac{\text{Numărul de apariții ale cuvântului}}{\text{Total cuvinte în document}}}{\log({\frac{\text{Numărul de documente cu cuvântul}}{\text{Total documente}}})}} $$

Construirea motoarelor de recomandare în Python

Datele noastre

book_summary_df:

Carte Descriere
The Hobbit "Bilbo Baggins duce o viață simplă alături de ceilalți hobbits din ținut..."
The Great Gatsby "Plasat în New York-ul Epocii de Jazz, romanul povestește tragedia lui Jay..."
A Game of Thrones "Au trecut 15 ani de la rebeliunea lui Robert, cu o perioadă de nouă ani..."
Macbeth "Un viteaz general scoțian primește o profeție de la trei vrăjitoare..."
... ...
Construirea motoarelor de recomandare în Python

Instanțierea vectorizatorului

from sklearn.feature_extraction.text import TfidfVectorizer
tfidfvec = TfidfVectorizer(        ,           )
Construirea motoarelor de recomandare în Python

Filtrarea datelor

from sklearn.feature_extraction.text import TfidfVectorizer
tfidfvec = TfidfVectorizer(min_df=2,           )
Construirea motoarelor de recomandare în Python

Filtrarea datelor

from sklearn.feature_extraction.text import TfidfVectorizer
tfidfvec = TfidfVectorizer(min_df=2, max_df=0.7)
Construirea motoarelor de recomandare în Python

Vectorizarea datelor

vectorized_data = tfidfvec.fit_transform(book_summary_df['Descriptions'])

print(tfidfvec.get_feature_names)
['age', 'ancient', 'angry', 'brave', 'battle', 'fellow', 'game', 'general', ...]
print(vectorized_data.to_array())
[[0.21,      0.53,    0.41,    0.64,     0.01,     0.02,     ...
 [0.31,      0.00,    0.42,    0.03,     0.00,     0.73,     ...
 [...,        ...,     ...,     ...,      ...,      ...,     ...
Construirea motoarelor de recomandare în Python

Formatarea datelor

tfidf_df = pd.DataFrame(vectorized_data.toarray(),
                        columns=tfidfvec.get_feature_names())

tfidf_df.index = book_summary_df['Book']
print(tfidf_df)
                   | 'age'| 'ancient'| 'angry'| 'brave'| 'battle'| 'fellow'|...
|------------------|------|----------|--------|--------|---------|---------|...
| The Hobbit       |  0.21|      0.53|    0.41|    0.64|     0.01|     0.02|...
| The Great Gatsby |  0.31|      0.00|    0.42|    0.03|     0.00|     0.73|...
| A Game of Thrones|  0.61|      0.42|    0.77|    0.31|     0.83|     0.03|...
|               ...|   ...|       ...|     ...|     ...|      ...|      ...|...
Construirea motoarelor de recomandare în Python

Similaritatea cosinus

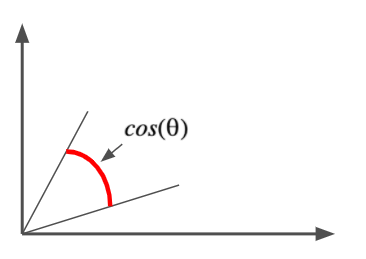
Distanța cosinus: $$cos(\theta)=\frac{A.B }{||A||\cdot||B||}$$
Construirea motoarelor de recomandare în Python

Similaritatea cosinus

from sklearn.metrics.pairwise import cosine_similarity

# Find similarity between all items
cosine_similarity_array = cosine_similarity(tfidf_summary_df)
# Find similarity between two items
cosine_similarity(tfidf_df.loc['The Hobbit'].values.reshape(1, -1),
                  tfidf_df.loc['Macbeth'].values.reshape(1, -1))
Construirea motoarelor de recomandare în Python

Să exersăm!

Construirea motoarelor de recomandare în Python

Preparing Video For Download...