Reprezentarea bag-of-words

Introducere în Prelucrarea Limbajului Natural în R

Kasey Jones

Research Data Scientist

Exemplul anterior

animal_farm %>%
  unnest_tokens(output = "word", token = "words",
                input = text_column) %>%
  anti_join(stop_words) %>%
  count(word, sort = TRUE)
# A tibble: 3,611 x 2
   word         n
   <chr>    <int>
 1 animals    248
 2 farm       163
 ...
Introducere în Prelucrarea Limbajului Natural în R

Reprezentarea bag-of-words

text1 <- c("Few words are important.")
text2 <- c("All words are important.")
text3 <- c("Most words are important.")

Cuvinte unice:

  • few: doar în text1
  • all: doar în text2
  • most: doar în text3
  • words, are, important
Introducere în Prelucrarea Limbajului Natural în R

Reprezentări vectoriale tipice

# Lowercase, without stop words
word_vector <- c("few", "all", "most", "words", "important")
# Representation for text1
text1 <- c("Few words are important.")
text1_vector <- c(1, 0, 0, 1, 1)
# Representation for text2
text2 <- c("All words are important.")
text2_vector <- c(0, 1, 0, 1, 1)
# Representation for text3
text3 <- c("Most words are important.")
text3_vector <- c(0, 0, 1, 1, 1)
Introducere în Prelucrarea Limbajului Natural în R

Reprezentarea tidytext

words <- animal_farm %>%
    unnest_tokens(output = "word", token = "words", input = text_column) %>%
    anti_join(stop_words) %>%
    count(chapter, word, sort = TRUE)
words
# A tibble: 6,807 x 3
   chapter    word         n
   <chr>      <chr>    <int>
 1 Chapter 8  napoleon    43
 2 Chapter 8  animals     41
 3 Chapter 9  boxer       34
...
Introducere în Prelucrarea Limbajului Natural în R

Exemplu cu un singur cuvânt

words %>%
  filter(word == 'napoleon') %>%
  arrange(desc(n))
# A tibble: 9 x 3
  chapter    word         n
  <chr>      <chr>    <int>
1 Chapter 8  napoleon    43
2 Chapter 7  napoleon    24
3 Chapter 5  napoleon    22
...
8 Chapter 3  napoleon     3
9 Chapter 4  napoleon     1
Introducere în Prelucrarea Limbajului Natural în R

Matrice rare

library(tidytext); library(dplyr)
russian_tweets <- read.csv("russian_1.csv")
russian_tweets <- as_tibble(russian_tweets)

tidy_tweets <- russian_tweets %>%
  unnest_tokens(word, content) %>%
  anti_join(stop_words)
tidy_tweets %>%
  count(word, sort = TRUE)
# A tibble: 43,666 x 2
...
Introducere în Prelucrarea Limbajului Natural în R

Matrice rare (continuare)

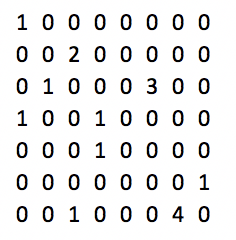
Matrice rară

  • 20.000 de rânduri (tweet-urile)
  • 43.000 de coloane (cuvintele)
  • 20.000 * 43.000 = 860.000.000
  • Doar 177.000 de intrări nenule. Aprox. 0,02%

Exemplu de matrice rară: Matricele rare au foarte puține intrări nenule. O matrice rară arată aproape numai zerouri.

Introducere în Prelucrarea Limbajului Natural în R

Exersați BoW

Introducere în Prelucrarea Limbajului Natural în R

Preparing Video For Download...