Confidențialitatea datelor și anonimizarea în Python
Rebeca Gonzalez
Data engineer
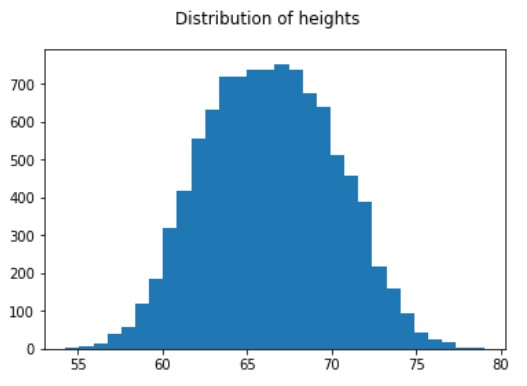
Putem crea seturi de date prin eșantionare din distribuții de probabilitate
Precum distribuția normală
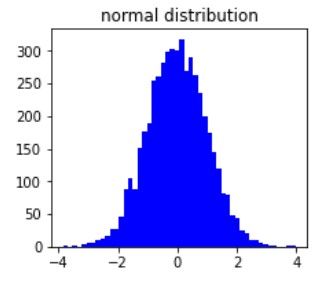
Apar frecvent în natură

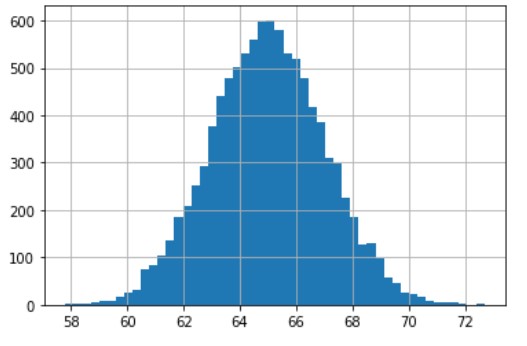
import numpy as np# Create new pandas DataFrame new_measures = pd.DataFrame()# Selecting the mean/center values and the standard deviation of the sample mean = 65 standard_deviation = 2# Generating the sample new_measures['Height'] = np.random.normal(mean, standard_deviation, 10000)
# Draw histogram to see the resulting heights distribution
new_measures['Height'].hist(bins=50)
Scikit-learn oferă funcții simple pentru generarea de seturi de date pentru:
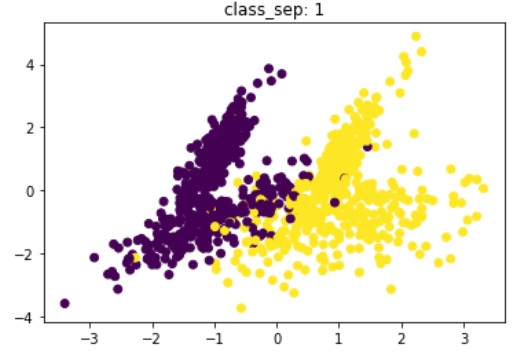
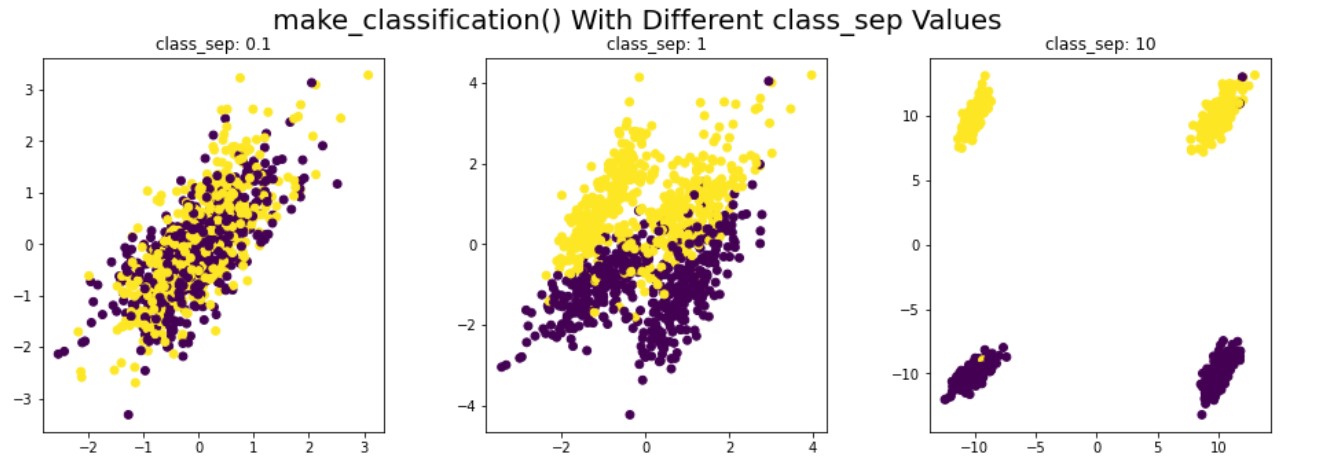
make_classification()make_blobs()# Import make_classification from sklearn datasets module from sklearn.datasets import make_classification# Generate the samples and their labels x, y = make_classification(n_samples=1000,n_classes=2,n_informative=2,n_features=4,n_clusters_per_class=2,class_sep=1)
# See the generated data and labels
print(x.shape)
print(y.shape)
print(x)
(1000, 4)
(1000,)
[[ 1.22914870e+00 -2.62386795e+00 2.25878743e+00 2.55377055e+00]
[-1.10279812e+00 -1.15816087e+00 1.55571279e+00 7.80565898e-02]
[ 2.65581977e-03 -2.33278818e+00 2.37837858e+00 1.57533194e+00]
...
[ 4.51006972e-01 7.53435745e-01 -9.21597108e-01 -2.20659747e-01]
[ 5.31925876e-01 7.42210504e-01 -9.37625248e-01 -1.61488855e-01]
[ 1.62862108e+00 -2.72435345e+00 2.22562940e+00 2.87628246e+00]]


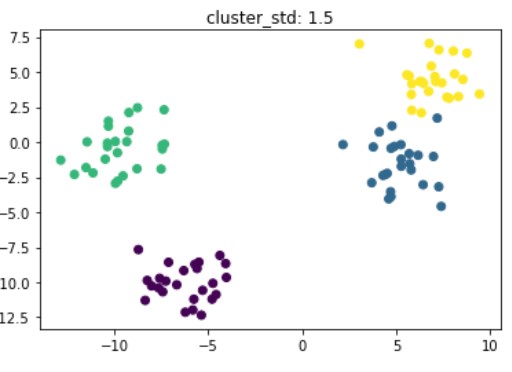
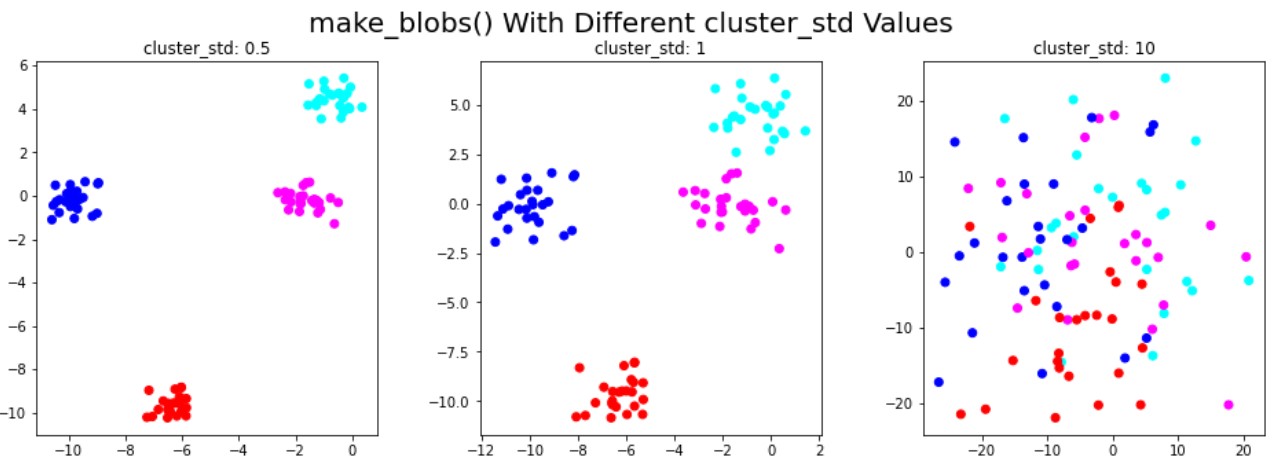
# Import the datasets module for generating clustering datasets from sklearn.datasets import make_blobs# Specify a value for standard deviation standard_deviation = 1.5# Generate the data and labels of the dataset x, labels = make_blobs(n_features=3, centers=4, cluster_std=standard_deviation)# See the shape of the generated data print(x.shape)
(100, 3)


Confidențialitatea datelor și anonimizarea în Python