ज़ीरो-शॉट वीडियो क्लासिफिकेशन

Hugging Face के साथ मल्टी-मोडल मॉडल्स

James Chapman

Curriculum Manager, DataCamp

ज़ीरो-शॉट वीडियो क्लासिफिकेशन
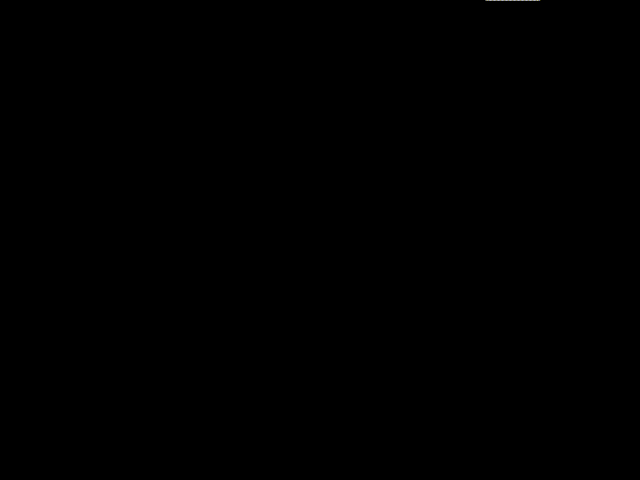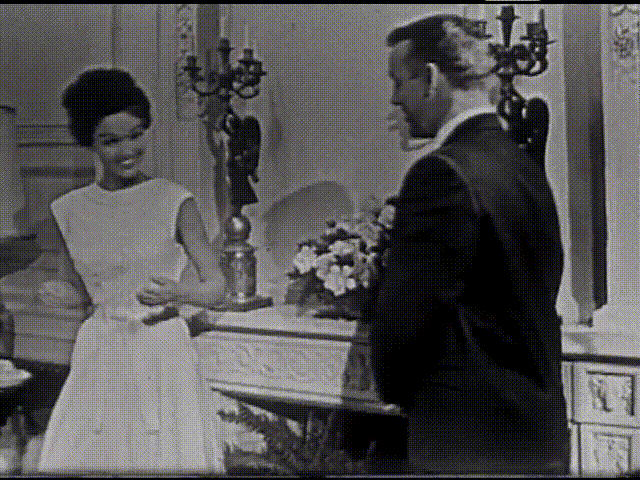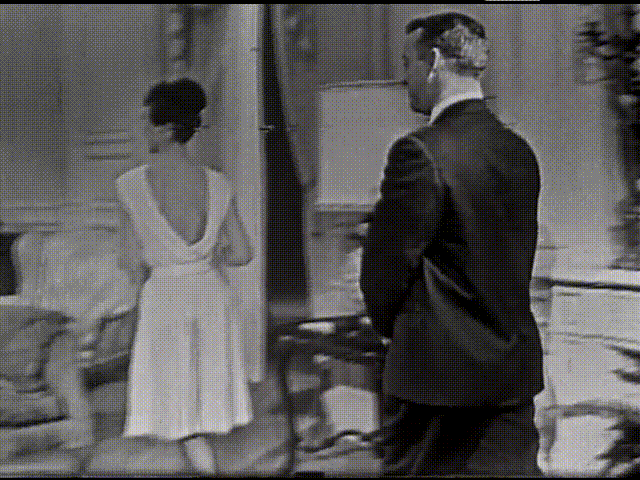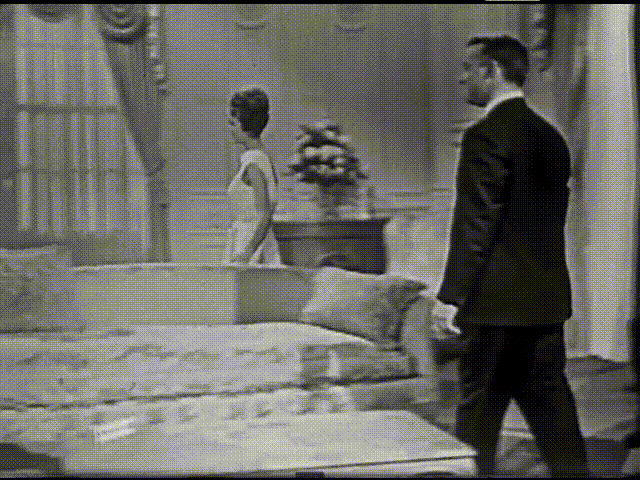
 

बिज़नेस केस:

  • एक प्रतिस्पर्धी के विज्ञापनों से बिक्री बढ़ रही है
  • क्या हमारे प्रतिस्पर्धी के विज्ञापन अधिक सकारात्मक हैं?


1950 के दशक का टूथपेस्ट विज्ञापन

1 https://repository.duke.edu/dc/adviews/dmbb37204
Hugging Face के साथ मल्टी-मोडल मॉडल्स

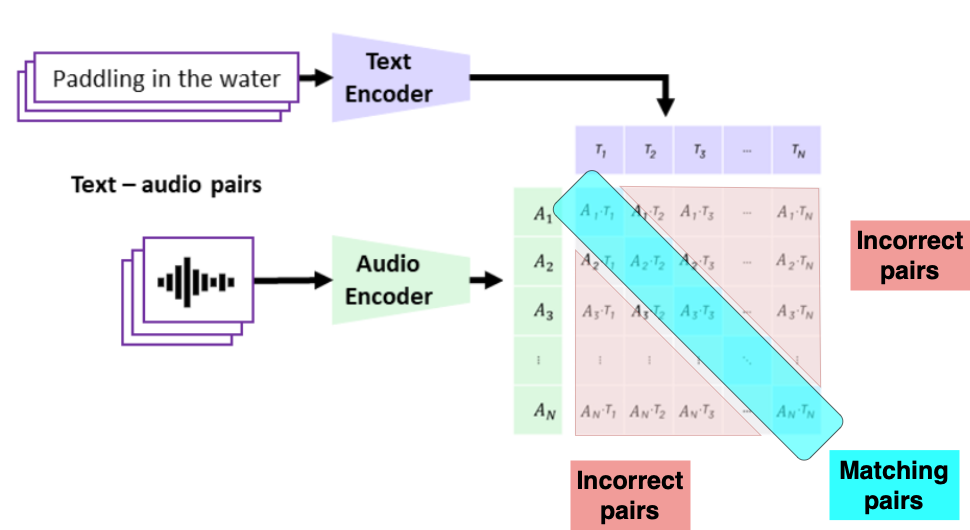
CLAP

  • Contrastive Language Audio Pretraining
  • CLIP को ट्रेन करने की विधि के समान
    • अलग टेक्स्ट एन्कोडर और ऑडियो एन्कोडर
  • 633k मेल खाते ऑडियो + विवरण पेयर्स
  • कंट्रास्टिव प्रीट्रेनिंग से ऑडियो + टेक्स्ट एम्बेडिंग्स अलाइन्ड होती हैं

CLAP डायग्राम जो एम्बेडिंग्स के मिलान को दिखाता है

1 https://arxiv.org/html/2211.06687v4
Hugging Face के साथ मल्टी-मोडल मॉडल्स

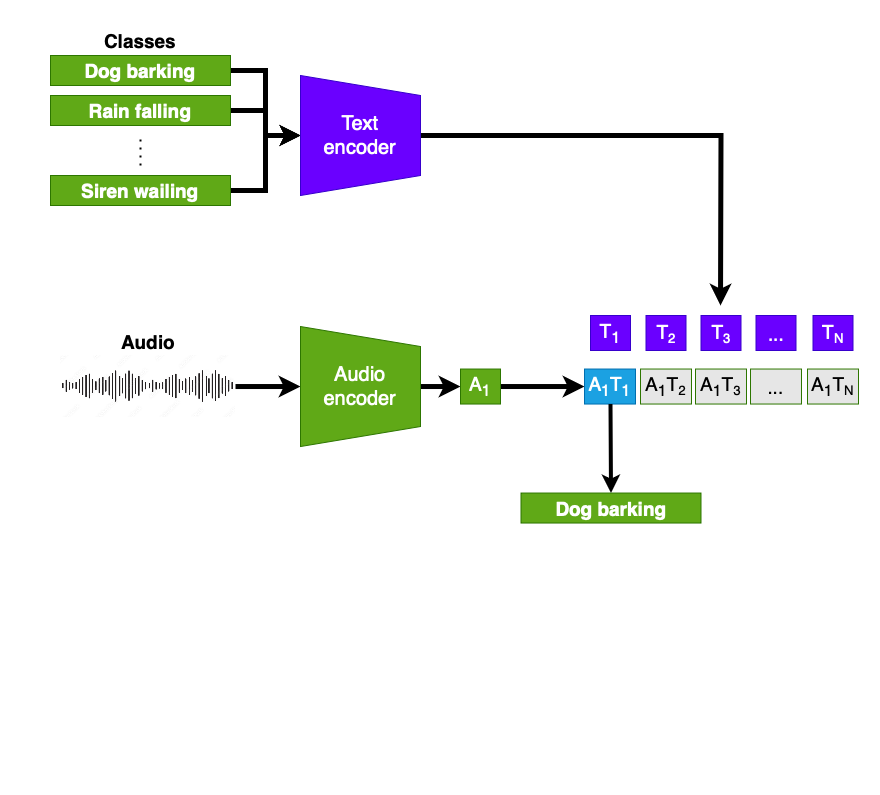
ऐप्रोच: मल्टी-मोडल ZSL

CLAP के साथ ज़ीरो-शॉट लर्निंग

लेट फ्यूजन ऐप्रोच का भाग 1: CLAP का ज़ूम-इन

1 https://arxiv.org/html/2310.02298v3
Hugging Face के साथ मल्टी-मोडल मॉडल्स

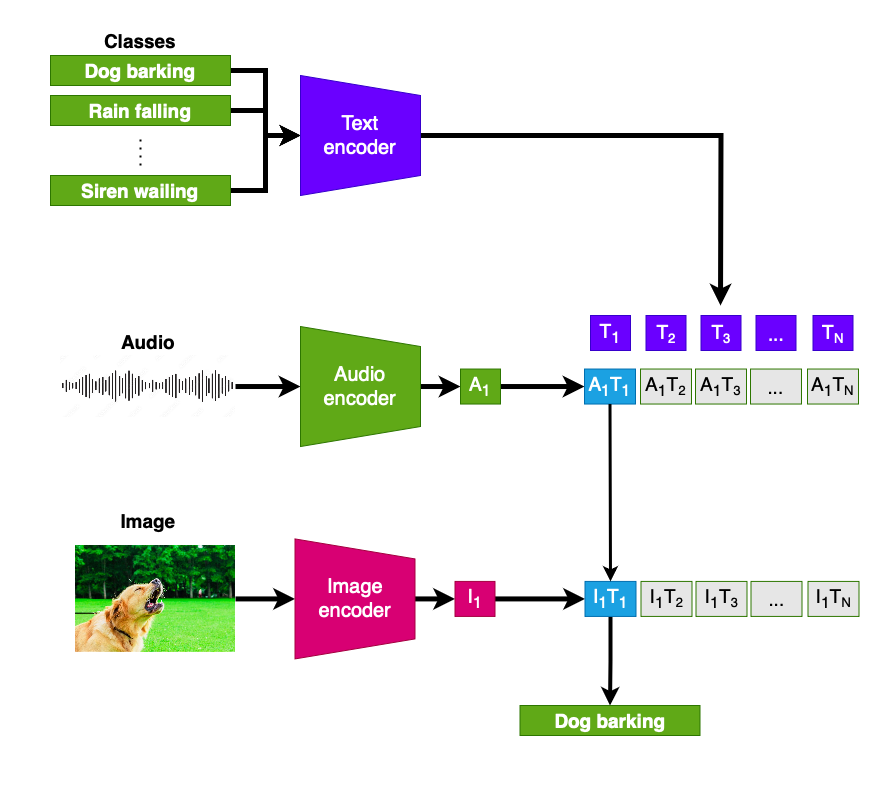
ऐप्रोच: मल्टी-मोडल ZSL

CLAP के साथ ज़ीरो-शॉट लर्निंग

+ CLIP के साथ ज़ीरो-शॉट लर्निंग

  • कॉमन टेक्स्ट क्लासेस
  • CLIP और CLAP की प्रॉबैबिलिटीज़ को मिलाया

लेट फ्यूजन ऐप्रोच का भाग 2: CLIP+CLAP का ज़ूम-इन

Hugging Face के साथ मल्टी-मोडल मॉडल्स

वीडियो और ऑडियो

moviepy से .mp4 के ऑडियो और वीडियो स्ट्रीम अलग करना:

from moviepy.editor import VideoFileClip
from moviepy.video.io.ffmpeg_tools import ffmpeg_extract_subclip

ffmpeg_extract_subclip("advert.mp4", 0, 5, "advert_5s.mp4")


video = VideoFileClip("advert_5s.mp4")
audio = video.audio
audio.write_audiofile("advert_5s.mp3")
Hugging Face के साथ मल्टी-मोडल मॉडल्स

ऑडियो और वीडियो तैयार करना

from decord import VideoReader
from PIL import Image
video_reader = VideoReader(video_path)
video = video_reader.get_batch(range(20)).asnumpy()
video = video[:, :, :, ::-1]
video = [Image.fromarray(frame) for frame in video]


from datasets import Dataset, Audio audio_dataset = Dataset.from_dict({"audio": [audio_path]}).cast_column("audio", Audio()) audio_sample = audio_dataset[0]["audio"]["array"]
Hugging Face के साथ मल्टी-मोडल मॉडल्स

वीडियो प्रेडिक्शन

emotions = ["joy", "fear", "anger", "sadness", "disgust", "surprise", "neutral"]


image_class = pipeline(model="openai/clip-vit-large-patch14", task="zero-shot-image-classification")
predictions = image_classifier(video, candidate_labels=emotions) scores = [ {l['label']: l['score'] for l in prediction} for prediction in predictions ]
avg_image_scores = {emotion: sum([s[emotion] for s in scores])/len(scores) for emotion in emotions} print(f"Average scores: {avg_image_scores}")
Average scores: {'joy': 0.10063326267991216, 'fear': 0.0868348691612482, ...}
Hugging Face के साथ मल्टी-मोडल मॉडल्स

ऑडियो प्रेडिक्शन और संयोजन

audio_class = pipeline(model="laion/clap-htsat-unfused", 
                       task="zero-shot-audio-classification")


audio_scores = audio_class(audio_sample, candidate_labels=emotions) audio_scores = {l['label']: l['score'] for l in audio_scores}
multimodal_scores = {emotion: (avg_image_scores[emotion] + audio_scores[emotion])/2 for emotion in emotions} print(f"Multimodal scores: {multimodal_scores}")
Multimodal scores: {'joy': 0.3109628591220826, 'fear': 0.09013736313208938, 
'anger': 0.011454355076421053, 'sadness': 0.06018101833760738, 'disgust': 0.07207315033301712, 
'surprise': 0.252118631079793, 'neutral': 0.2030726027674973}
Hugging Face के साथ मल्टी-मोडल मॉडल्स

अभ्यास करते हैं!

Hugging Face के साथ मल्टी-मोडल मॉडल्स

Preparing Video For Download...