Introduktion till datatekniker
Vincent Vankrunkelsven
Data Engineer, DataCamp
def extract_table_to_df(tablename, db_engine): return pd.read_sql("SELECT * FROM {}".format(tablename), db_engine)def split_columns_transform(df, column, pat, suffixes): # Converts column into str and splits it on pat...def load_df_into_dwh(film_df, tablename, schema, db_engine): return film_df.to_sql(tablename, db_engine, schema=schema, if_exists="replace")db_engines = { ... } # Behöver konfigureras def etl(): # Extract film_df = extract_table_to_df("film", db_engines["store"]) # Transform film_df = split_columns_transform(film_df, "rental_rate", ".", ["_dollar", "_cents"]) # Load load_df_into_dwh(film_df, "film", "store", db_engines["dwh"])


task eller med operatorerfrom airflow.sdk import dag
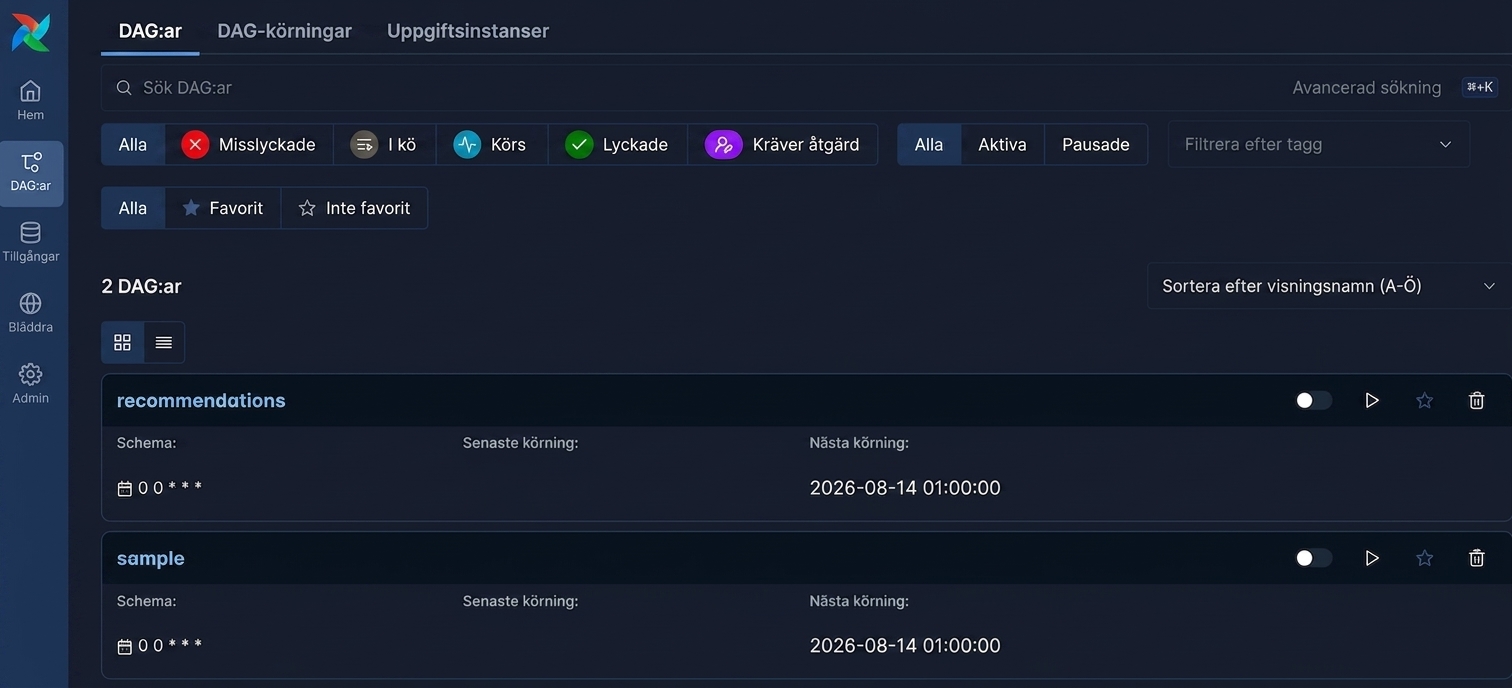
@dag(dag_id="sample", start_date=datetime(2024, 1, 1),
schedule="0 0 * * *")
def sample():
...
# .------------------------- minute (0 - 59)
# | .----------------------- hour (0 - 23)
# | | .--------------------- day of the month (1 - 31)
# | | | .------------------- month (1 - 12)
# | | | | .----------------- day of the week (0 - 6)
# * * * * * <command>
0 * * * * # Varje timme vid minut 0
from airflow.sdk import dag, task @task(task_id="etl_task") def etl(): ...@dag(dag_id="etl_pipeline", start_date=datetime(2024, 1, 1), schedule="0 0 * * *") def etl_pipeline(): wait_for_table = EmptyOperator(task_id="wait") wait_for_table >> etl()etl_pipeline()
from airflow.sdk import dag, task
...
etl_pipeline()
Sparad som etl_dag.py i ~/airflow/dags/

Introduktion till datatekniker