Textbaserade likheter

Bygga rekommendationsmotorer i Python

Rob O'Callaghan

Director of Data

Att arbeta utan tydliga attribut
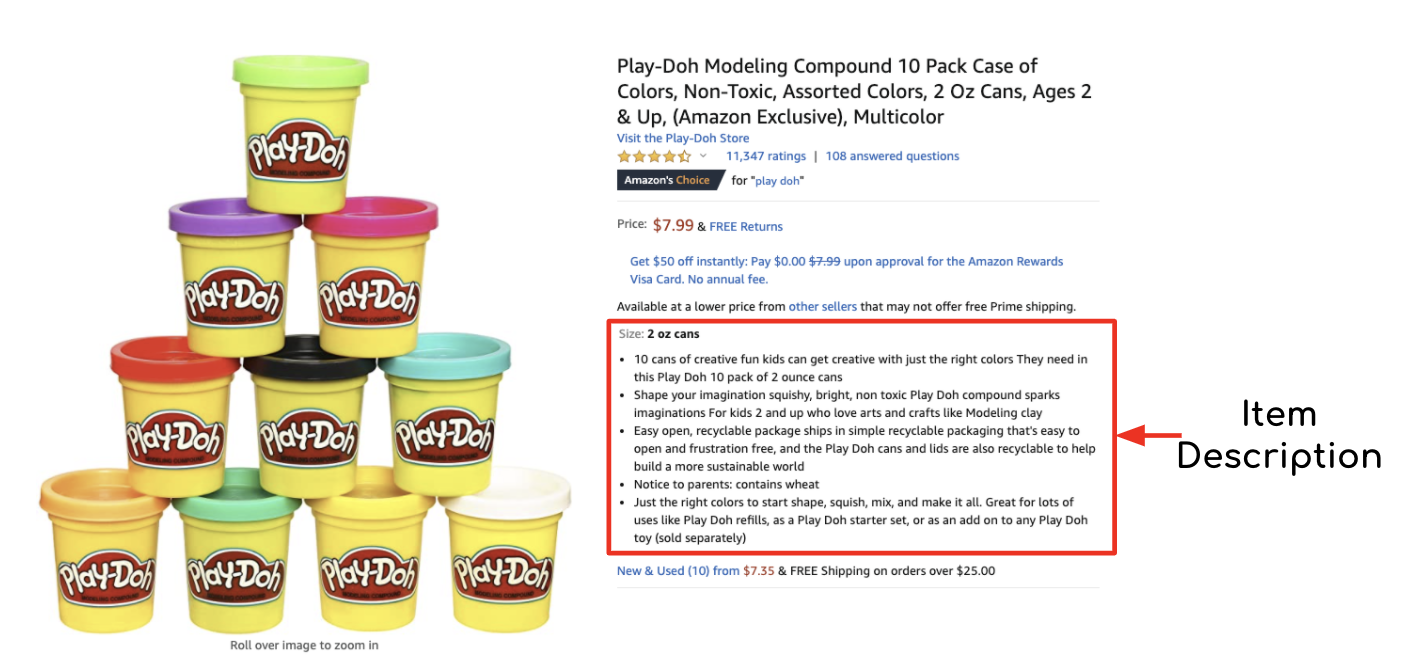
Exempel på en produktbeskrivning från Amazon.

Bygga rekommendationsmotorer i Python

Termfrekvens invers dokumentfrekvens

$$ \Large{\text{TF-IDF} = \frac{\frac{\text{Count of word occurrences}}{\text{Total words in document}}}{\log({\frac{\text{Number of docs word is in}}{\text{Total number of docs}}})}} $$

Bygga rekommendationsmotorer i Python

Våra data

book_summary_df:

Book Description
The Hobbit "Bilbo Baggins lives a simple life with his fellow hobbits in the shire..."
The Great Gatsby "Set in Jazz Age New York, the novel tells the tragic story of Jay ..."
A Game of Thrones "15 years have passed since Robert's rebellion, with a nine-year-long ..."
Macbeth "A brave Scottish general receives a prophecy from a trio of witches ..."
... ...
Bygga rekommendationsmotorer i Python

Instansiera vektorn

from sklearn.feature_extraction.text import TfidfVectorizer
tfidfvec = TfidfVectorizer(        ,           )
Bygga rekommendationsmotorer i Python

Filtrera data

from sklearn.feature_extraction.text import TfidfVectorizer
tfidfvec = TfidfVectorizer(min_df=2,           )
Bygga rekommendationsmotorer i Python

Filtrera data

from sklearn.feature_extraction.text import TfidfVectorizer
tfidfvec = TfidfVectorizer(min_df=2, max_df=0.7)
Bygga rekommendationsmotorer i Python

Vektorisera data

vectorized_data = tfidfvec.fit_transform(book_summary_df['Descriptions'])

print(tfidfvec.get_feature_names)
['age', 'ancient', 'angry', 'brave', 'battle', 'fellow', 'game', 'general', ...]
print(vectorized_data.to_array())
[[0.21,      0.53,    0.41,    0.64,     0.01,     0.02,     ...
 [0.31,      0.00,    0.42,    0.03,     0.00,     0.73,     ...
 [...,        ...,     ...,     ...,      ...,      ...,     ...
Bygga rekommendationsmotorer i Python

Formatera data

tfidf_df = pd.DataFrame(vectorized_data.toarray(),
                        columns=tfidfvec.get_feature_names())

tfidf_df.index = book_summary_df['Book']
print(tfidf_df)
                   | 'age'| 'ancient'| 'angry'| 'brave'| 'battle'| 'fellow'|...
|------------------|------|----------|--------|--------|---------|---------|...
| The Hobbit       |  0.21|      0.53|    0.41|    0.64|     0.01|     0.02|...
| The Great Gatsby |  0.31|      0.00|    0.42|    0.03|     0.00|     0.73|...
| A Game of Thrones|  0.61|      0.42|    0.77|    0.31|     0.83|     0.03|...
|               ...|   ...|       ...|     ...|     ...|      ...|      ...|...
Bygga rekommendationsmotorer i Python

Cosinuslikhet

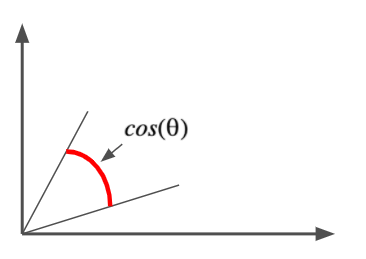
Cosinusavstånd: $$cos(\theta)=\frac{A.B }{||A||\cdot||B||}$$
Bygga rekommendationsmotorer i Python

Cosinuslikhet

from sklearn.metrics.pairwise import cosine_similarity

# Find similarity between all items
cosine_similarity_array = cosine_similarity(tfidf_summary_df)
# Find similarity between two items
cosine_similarity(tfidf_df.loc['The Hobbit'].values.reshape(1, -1),
                  tfidf_df.loc['Macbeth'].values.reshape(1, -1))
Bygga rekommendationsmotorer i Python

Nu kör vi en övning!

Bygga rekommendationsmotorer i Python

Preparing Video For Download...