文字摘要

善用 Hugging Face

Jacob H. Marquez

Lead Data Engineer

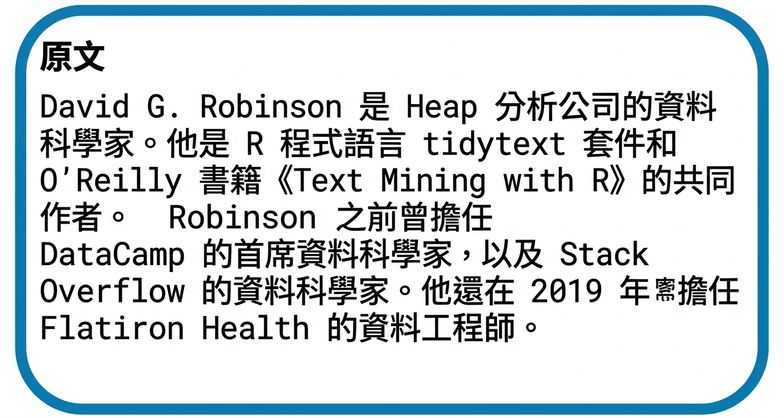
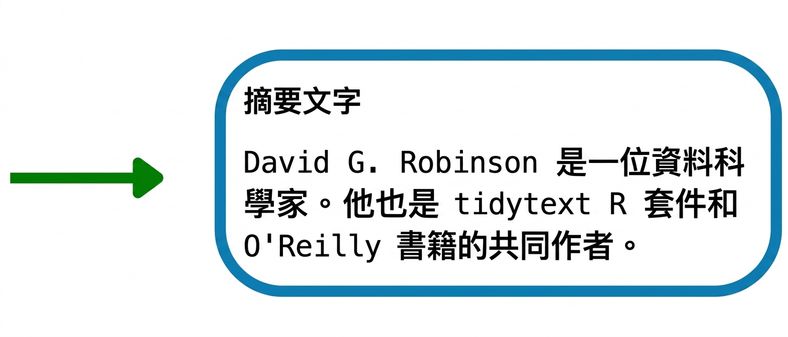
什麼是摘要?

$$

Large text

$$

part2.jpg

善用 Hugging Face

抽取式 vs. 生成式

$$

抽取式:

$$ ✅ 從文本選出關鍵句子

$$ ✅ 高效、省資源

$$ ❌ 彈性不足,可能不夠連貫

$$

生成式:

$$ ✅ 產生重述後的新文本

$$ ✅ 更清楚、可讀性高

$$ ❌ 需更多資源與處理

善用 Hugging Face

抽取式摘要的應用情境

$$

  • 📑 法律文件:標註關鍵條款

$$

$$

$$

  • 💰 財務研究:擷取洞見

Legal Documents

Financial Research

善用 Hugging Face

生成式摘要的應用情境

News Articles

Content Recommendations.jpg

$$

  • 📰 新聞文章:產生精簡摘要

$$

$$ $$

  • 📍 內容推薦:生成吸睛敘述
善用 Hugging Face

抽取式摘要實作

from transformers import pipeline

# Load the extractive summarization pipeline
summarizer = pipeline("summarization", model="nyamuda/extractive-summarization")
text = "This is my really large text about Data Science..."
summary_text = summarizer(text)
print(summary_text[0]['summary_text'])
"data science is a field that combines mathematics, statistics...."
善用 Hugging Face

生成式摘要實作

from transformers import pipeline

# Load the abstractive summarization pipeline
summarizer = pipeline("summarization", model="sshleifer/distilbart-cnn-12-6")

text = "This is my really large text about Data Science..." summary_text = summarizer(text) print(summary_text[0]['summary_text'])
"The global data science platform market is projected
 is projected to reach $140.9 billion by 2025..."
善用 Hugging Face

摘要的參數

  • min_new_tokensmax_new_tokens:控制摘要長度
summarizer = pipeline(task="summarization", min_new_tokens=10, max_new_tokens=150)
善用 Hugging Face

一起來練習吧!

善用 Hugging Face

Preparing Video For Download...