連結 DataFrame

用 Python 進行資料清理

Adel Nehme

VP of AI Curriculum, DataCamp

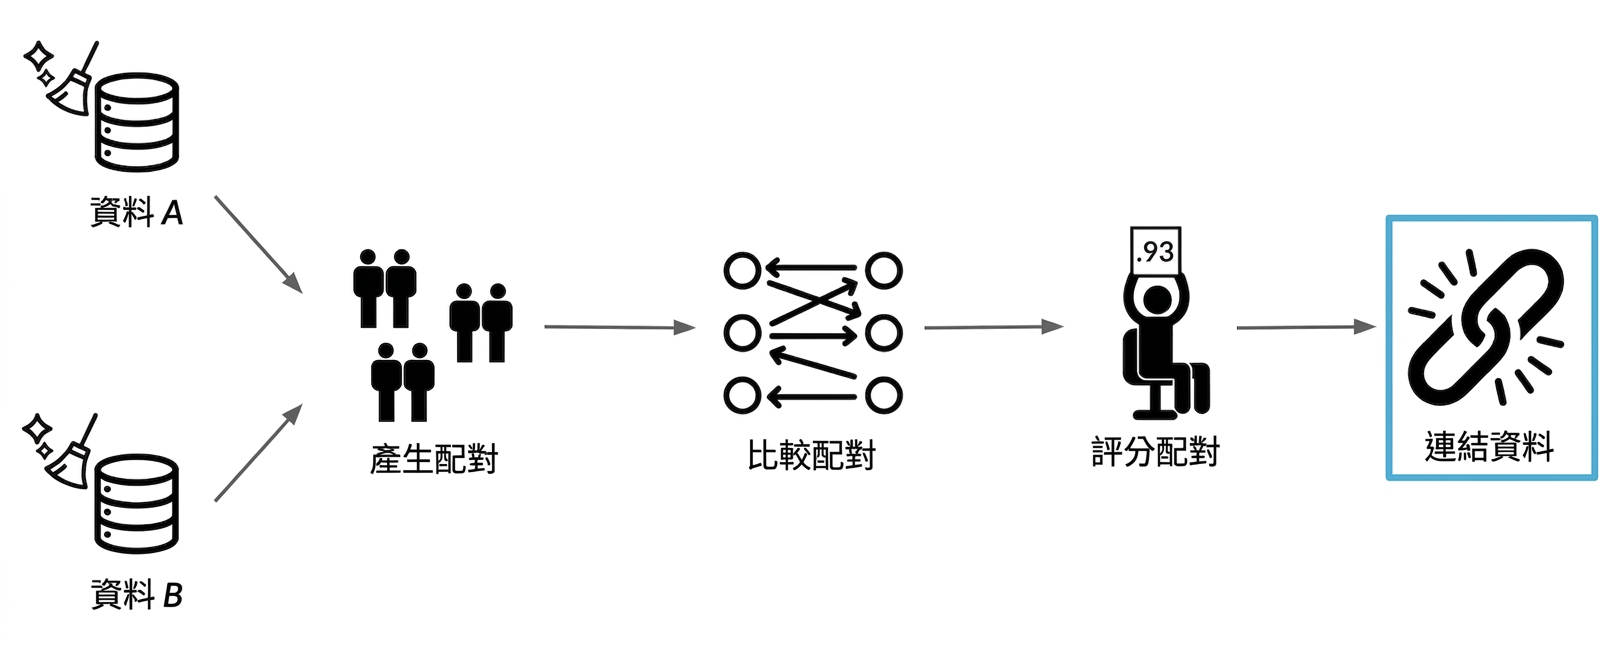
紀錄連結

用 Python 進行資料清理

紀錄連結

用 Python 進行資料清理

我們的 DataFrame

census_A

             given_name  surname date_of_birth         suburb state  address_1
rec_id                                                                
rec-1070-org   michaela  neumann      19151111  winston hills   nsw  stanley street 
rec-1016-org   courtney  painter      19161214      richlands   vic  pinkerton circuit 
...

census_B

               given_name  surname date_of_birth             suburb state  address_1
rec_id                                                                      
rec-561-dup-0       elton      NaN      19651013         windermere   vic  light setreet 
rec-2642-dup-0   mitchell    maxon      19390212         north ryde   nsw  edkins street 
...
用 Python 進行資料清理

我們已完成的步驟

# Import recordlinkage and generate full pairs
import recordlinkage
indexer = recordlinkage.Index()
indexer.block('state')
full_pairs = indexer.index(census_A, census_B)

# Comparison step compare_cl = recordlinkage.Compare() compare_cl.exact('date_of_birth', 'date_of_birth', label='date_of_birth') compare_cl.exact('state', 'state', label='state') compare_cl.string('surname', 'surname', threshold=0.85, label='surname') compare_cl.string('address_1', 'address_1', threshold=0.85, label='address_1')
potential_matches = compare_cl.compute(full_pairs, census_A, census_B)
用 Python 進行資料清理

現在要做什麼

用 Python 進行資料清理

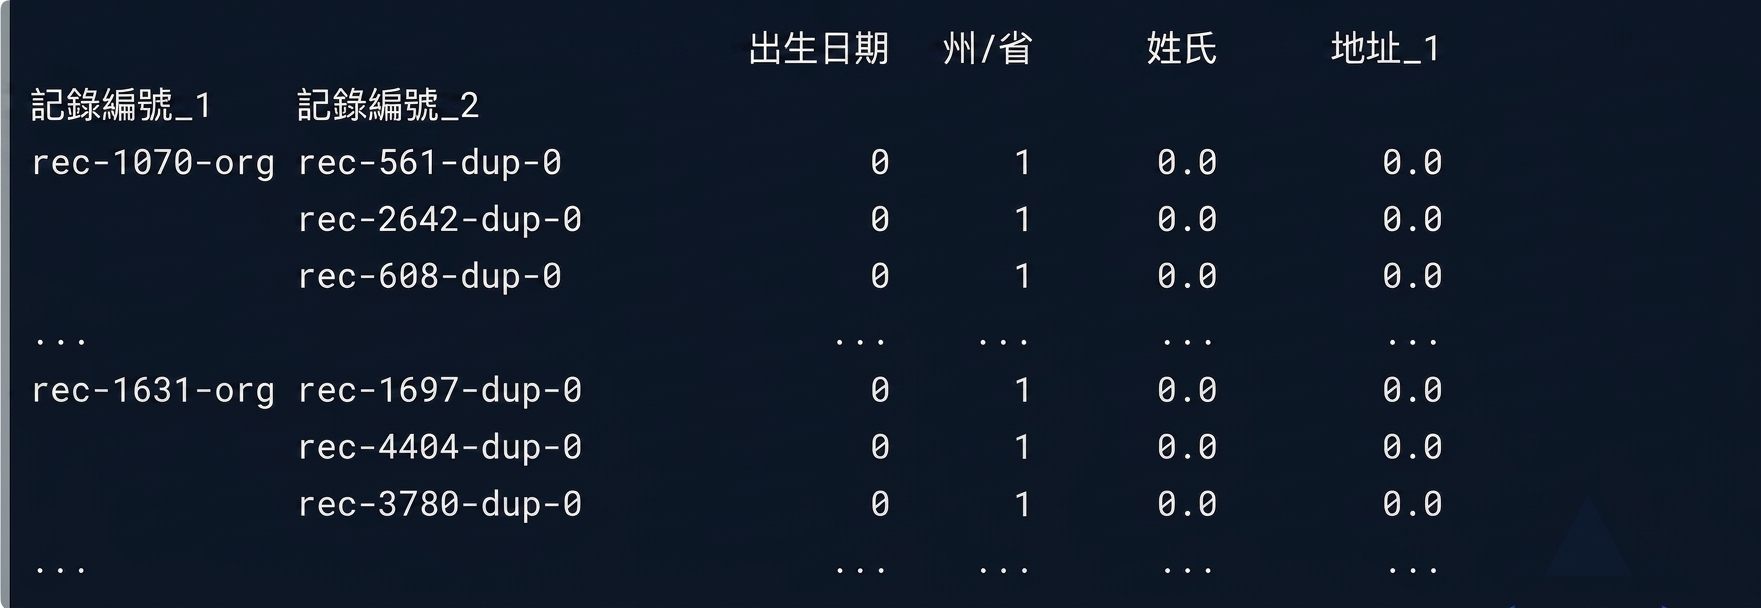
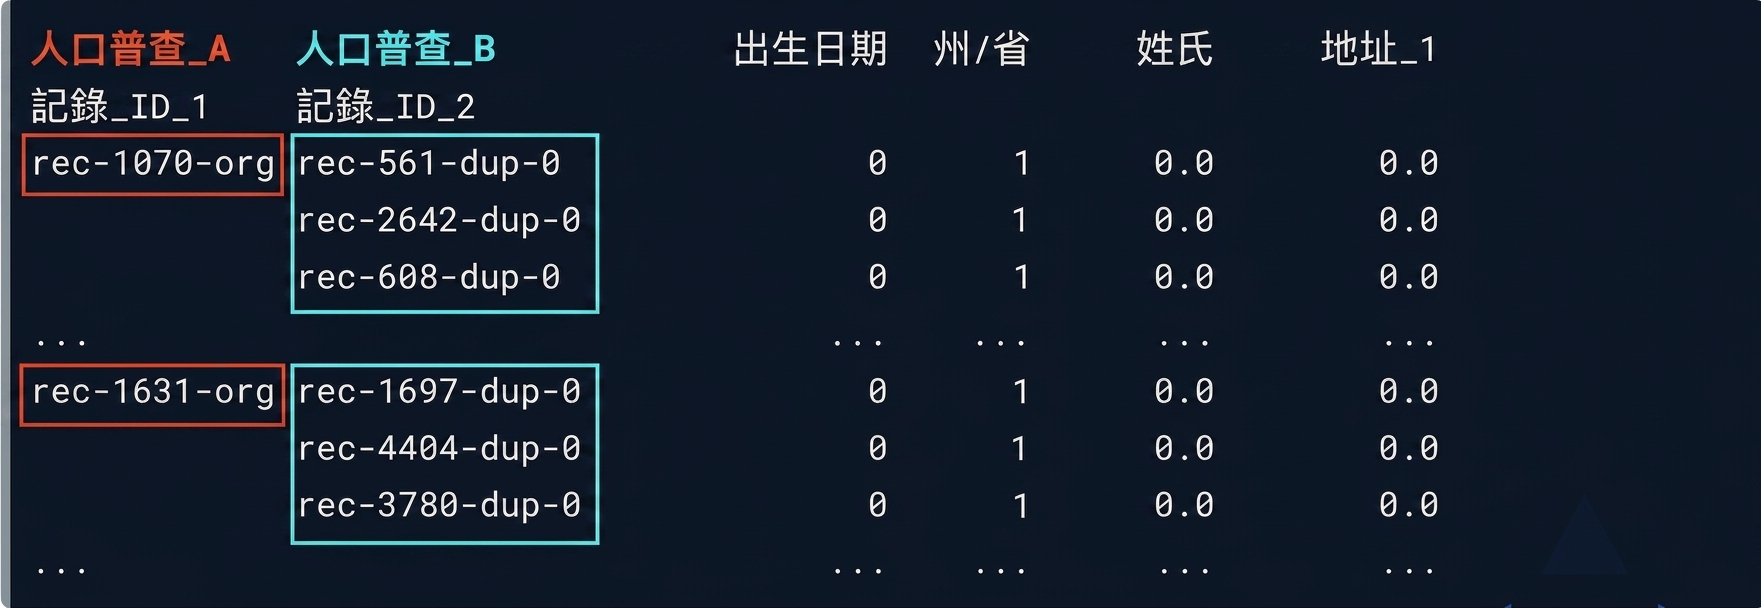
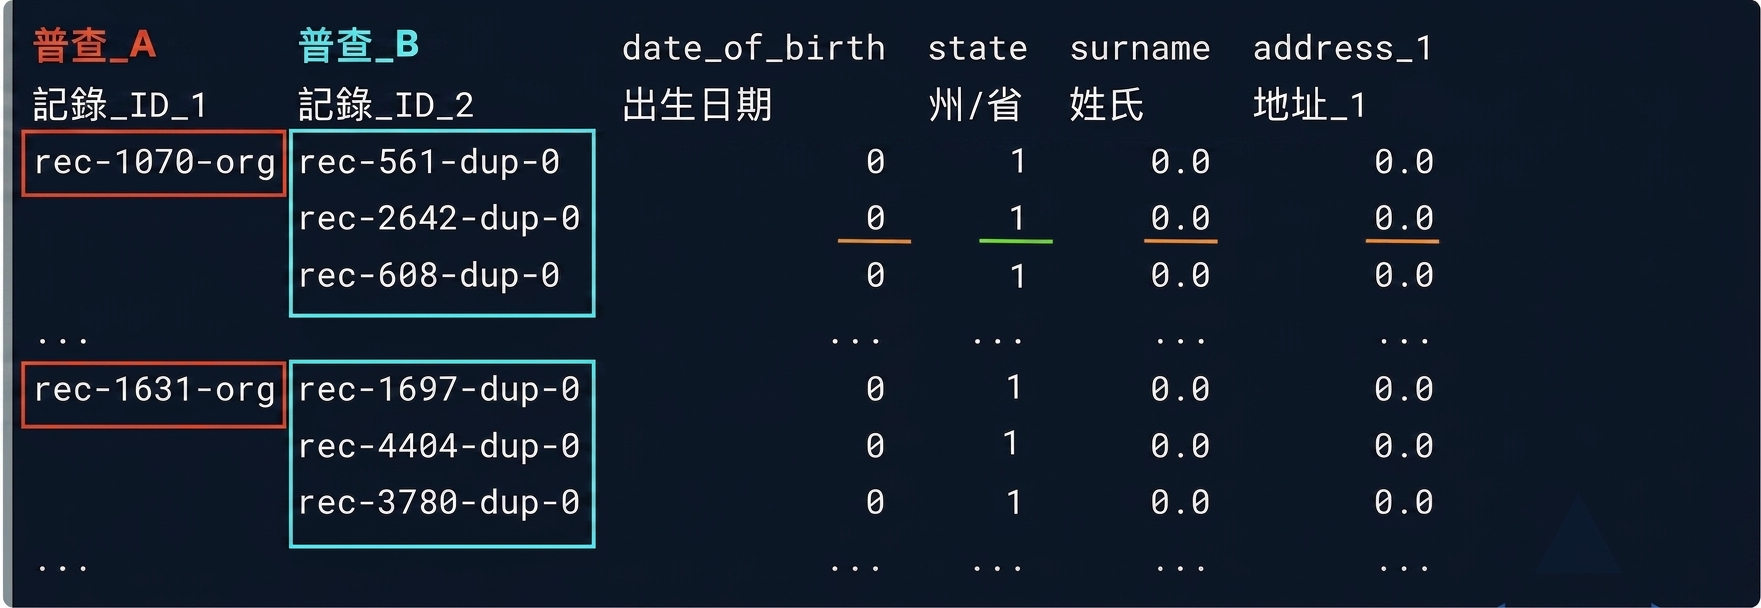
可能的配對

potential_matches

用 Python 進行資料清理

可能的配對

potential_matches

用 Python 進行資料清理

可能的配對

potential_matches

用 Python 進行資料清理

可能的配對

potential_matches

用 Python 進行資料清理

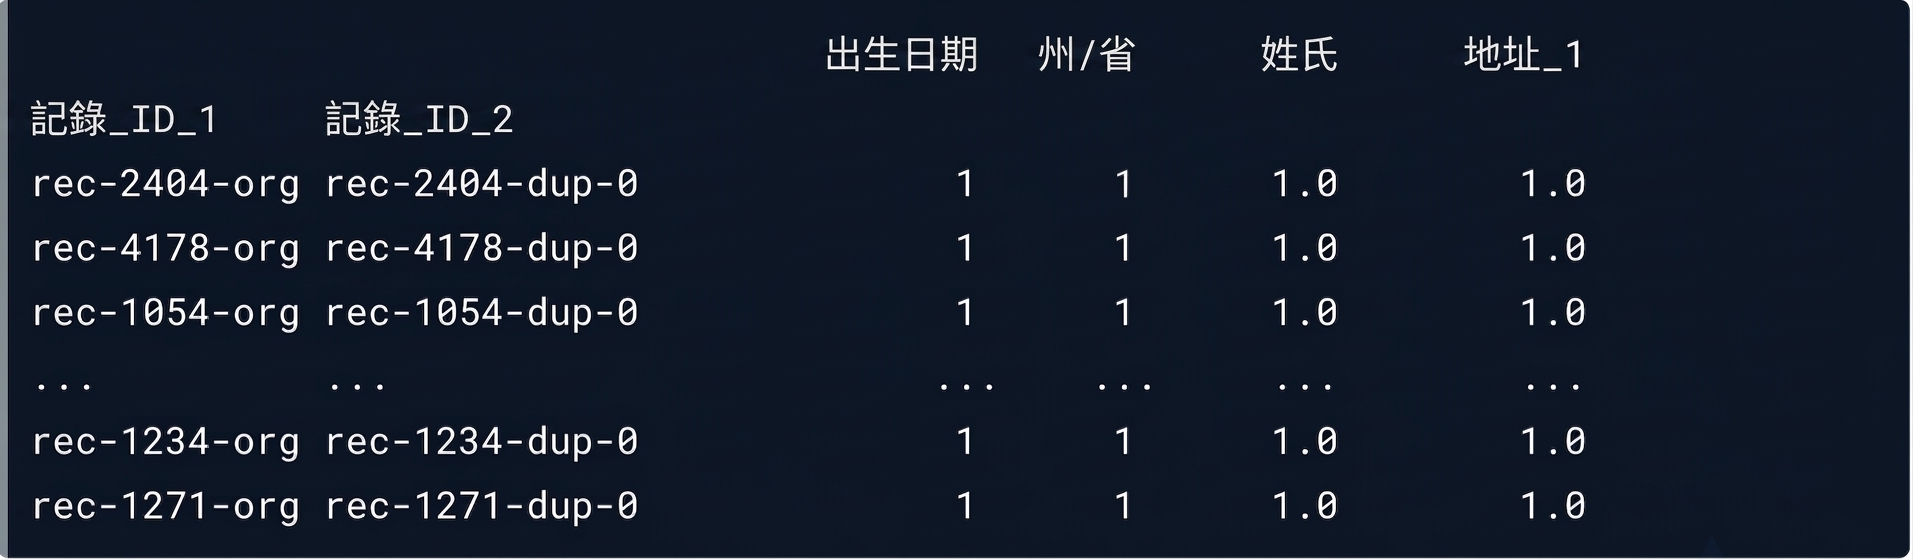
可能的相符紀錄

matches = potential_matches[potential_matches.sum(axis = 1) >= 3]
print(matches)
用 Python 進行資料清理

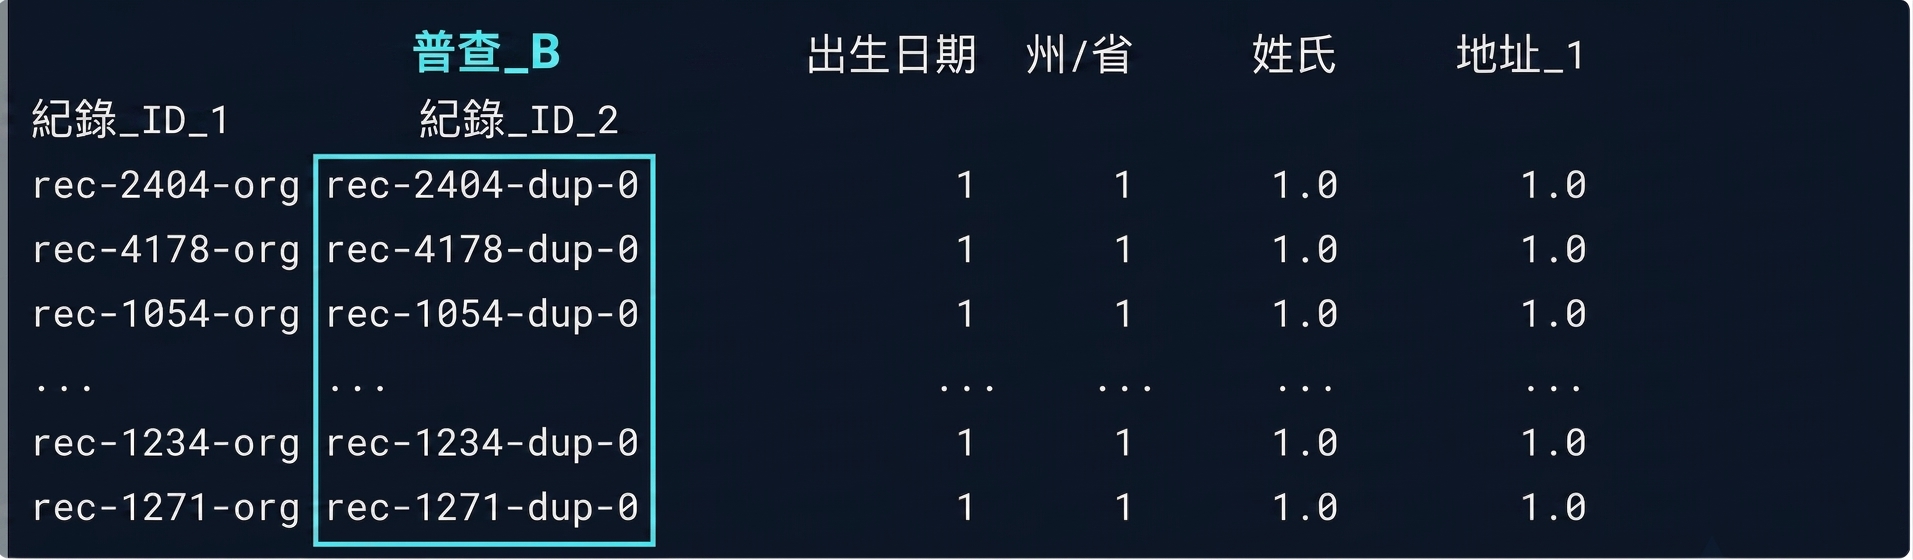
可能的相符紀錄

matches = potential_matches[potential_matches.sum(axis = 1) >= 3]
print(matches)
用 Python 進行資料清理

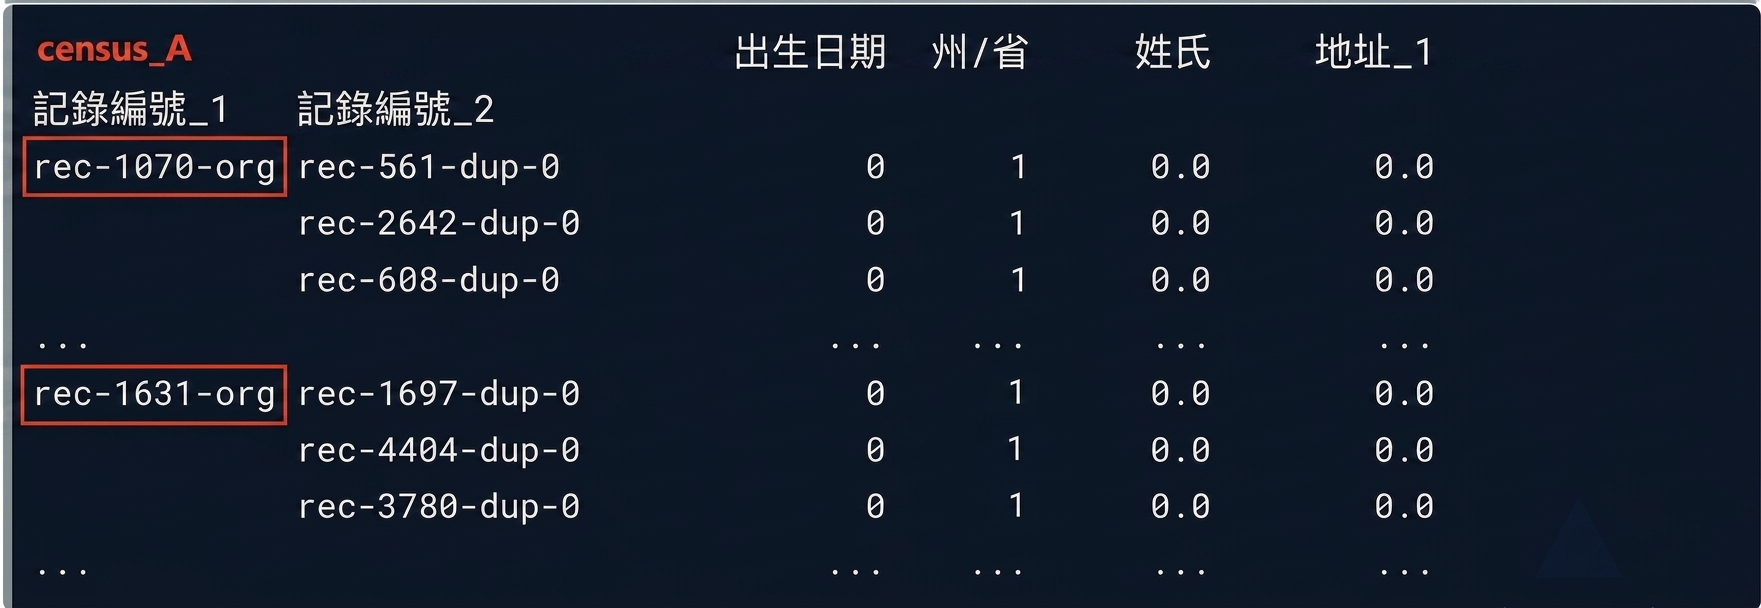
取得索引值

matches.index
MultiIndex(levels=[['rec-1007-org', 'rec-1016-org', 'rec-1054-org', 'rec-1066-org', 
'rec-1070-org', 'rec-1075-org', 'rec-1080-org', 'rec-110-org', ...
# Get indices from census_B only
duplicate_rows = matches.index.get_level_values(1)
print(census_B_index)
Index(['rec-2404-dup-0', 'rec-4178-dup-0', 'rec-1054-dup-0', 'rec-4663-dup-0',
       'rec-485-dup-0', 'rec-2950-dup-0', 'rec-1234-dup-0', ... , 'rec-299-dup-0'])
用 Python 進行資料清理

連結 DataFrame

# Finding duplicates in census_B
census_B_duplicates = census_B[census_B.index.isin(duplicate_rows)]

# Finding new rows in census_B census_B_new = census_B[~census_B.index.isin(duplicate_rows)]
# Link the DataFrames!
full_census = pd.concat([census_A, census_B_new])
用 Python 進行資料清理
# Import recordlinkage and generate pairs and compare across columns
...
# Generate potential matches
potential_matches = compare_cl.compute(full_pairs, census_A, census_B)

# Isolate matches with matching values for 3 or more columns matches = potential_matches[potential_matches.sum(axis = 1) >= 3]
# Get index for matching census_B rows only duplicate_rows = matches.index.get_level_values(1)
# Finding new rows in census_B census_B_new = census_B[~census_B.index.isin(duplicate_rows)]
# Link the DataFrames! full_census = pd.concat([census_A, census_B_new])
用 Python 進行資料清理

一起來練習吧!

用 Python 進行資料清理

Preparing Video For Download...