推薦系統

Introduction to Embeddings with the OpenAI API

Emmanuel Pire

Senior Software Engineer, DataCamp

用嵌入的推薦系統
 

  • 和語意搜尋非常相近!


流程:

  1. 將可能的推薦與資料點做嵌入

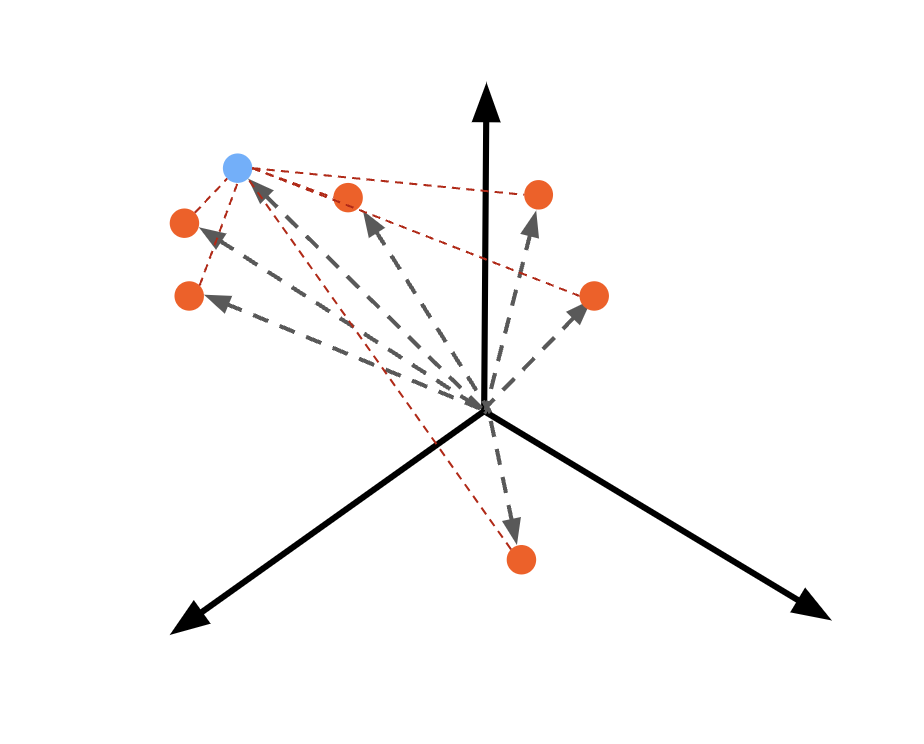
向量空間中一個藍色資料點與多個紅色資料點。

Introduction to Embeddings with the OpenAI API

用嵌入的推薦系統


  • 和語意搜尋非常相近!


流程:

  1. 將可能的推薦與資料點做嵌入
  2. 計算餘弦距離

向量空間中一個藍色資料點與多個紅色資料點。每個紅點與藍點之間畫有線表示餘弦距離。

Introduction to Embeddings with the OpenAI API

用嵌入的推薦系統


  • 和語意搜尋非常相近!


流程:

  1. 將可能的推薦與資料點做嵌入
  2. 計算餘弦距離
  3. 推薦最近的項目

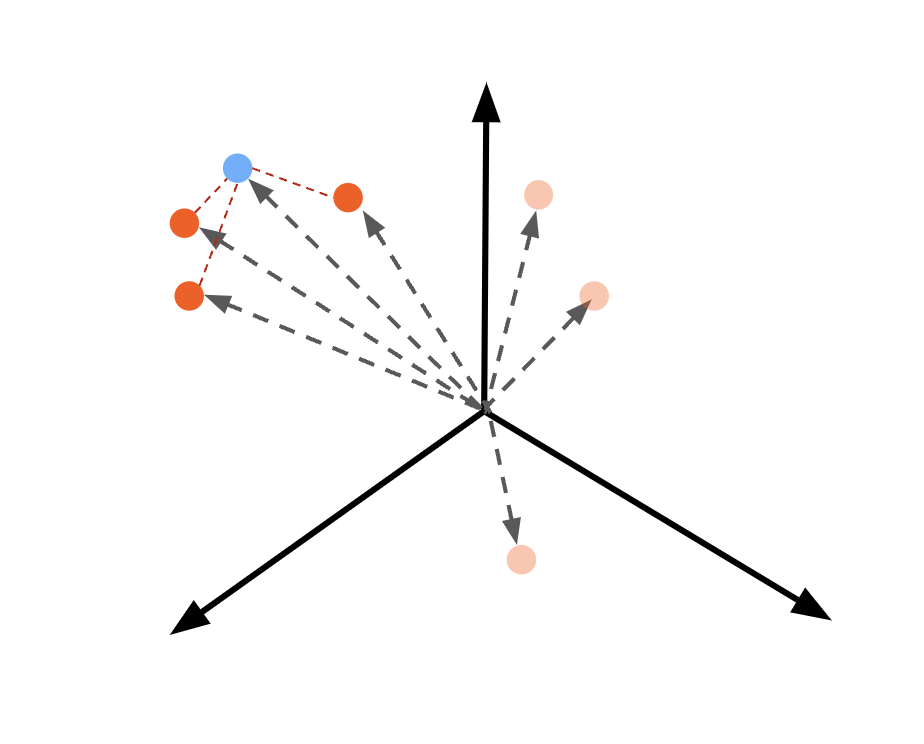
已標示出距離最近的三個紅點。

Introduction to Embeddings with the OpenAI API

範例:推薦文章

articles = [
    {"headline": "Economic Growth Continues Amid Global Uncertainty",
     "topic": "Business",
     "keywords": ["economy", "business", "finance"]},
    ...
    {"headline": "1.5 Billion Tune-in to the World Cup Final",
     "topic": "Sport",
     "keywords": ["soccer", "world cup", "tv"]}
]

current_article = {"headline": "How NVIDIA GPUs Could Decide Who Wins the AI Race", "topic": "Tech", "keywords": ["ai", "business", "computers"]}
Introduction to Embeddings with the OpenAI API

結合多種特徵

def create_article_text(article):
  return f"""Headline: {article['headline']}
Topic: {article['topic']}
Keywords: {', '.join(article['keywords'])}"""
article_texts = [create_article_text(article) for article in articles]
current_article_text = create_article_text(current_article)
print(current_article_text)
Headline: How NVIDIA GPUs Could Decide Who Wins the AI Race
Topic: Tech
Keywords: ai, business, computers
Introduction to Embeddings with the OpenAI API

建立嵌入向量

def create_embeddings(texts):
  response = openai.Embedding.create(
    model="text-embedding-3-small",
    input=texts
  )
  response_dict = response.model_dump()

  return [data['embedding'] for data in response_dict['data']]
current_article_embeddings = create_embeddings(current_article_text)[0]
article_embeddings = create_embeddings(article_texts)
Introduction to Embeddings with the OpenAI API

尋找最相似的文章

def find_n_closest(query_vector, embeddings, n=3):
  distances = []
  for index, embedding in enumerate(embeddings):
    dist = spatial.distance.cosine(query_vector, embedding)
    distances.append({"distance": dist, "index": index})
  distances_sorted = sorted(distances, key=lambda x: x["distance"])
  return distances_sorted[0:n]
hits = find_n_closest(current_article_embeddings, article_embeddings)

for hit in hits: article = articles[hit['index']] print(article['headline'])
Introduction to Embeddings with the OpenAI API

尋找最相似的文章

Tech Giant Buys 49% Stake In AI Startup
Tech Company Launches Innovative Product to Improve Online Accessibility
Scientists Make Breakthrough Discovery in Renewable Energy
Introduction to Embeddings with the OpenAI API

加入使用者歷史

user_history = [
    {"headline": "How NVIDIA GPUs Could Decide Who Wins the AI Race",
     "topic": "Tech",
     "keywords": ["ai", "business", "computers"]},
    {"headline": "Tech Giant Buys 49% Stake In AI Startup",
     "topic": "Tech",
     "keywords": ["business", "AI"]}
]
Introduction to Embeddings with the OpenAI API

多個資料點的推薦

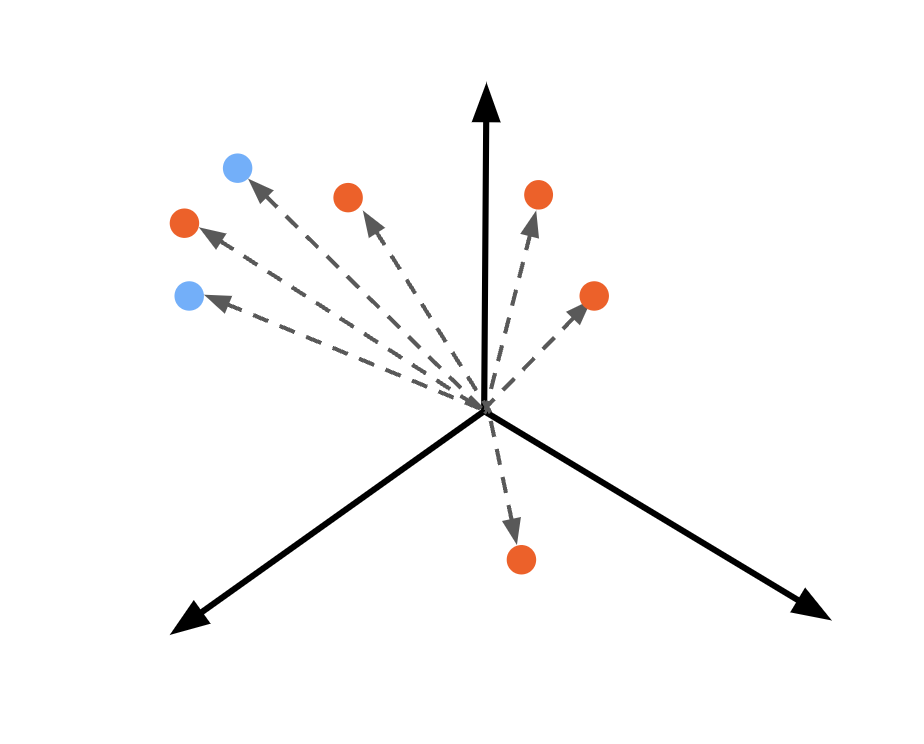
一張嵌入後的文章分佈圖,使用者歷史中的文章以藍色顯示,未閱讀的以紅色顯示。

Introduction to Embeddings with the OpenAI API

多個資料點的推薦


流程:

  • 取多個向量的平均合併為一個
  • 計算餘弦距離

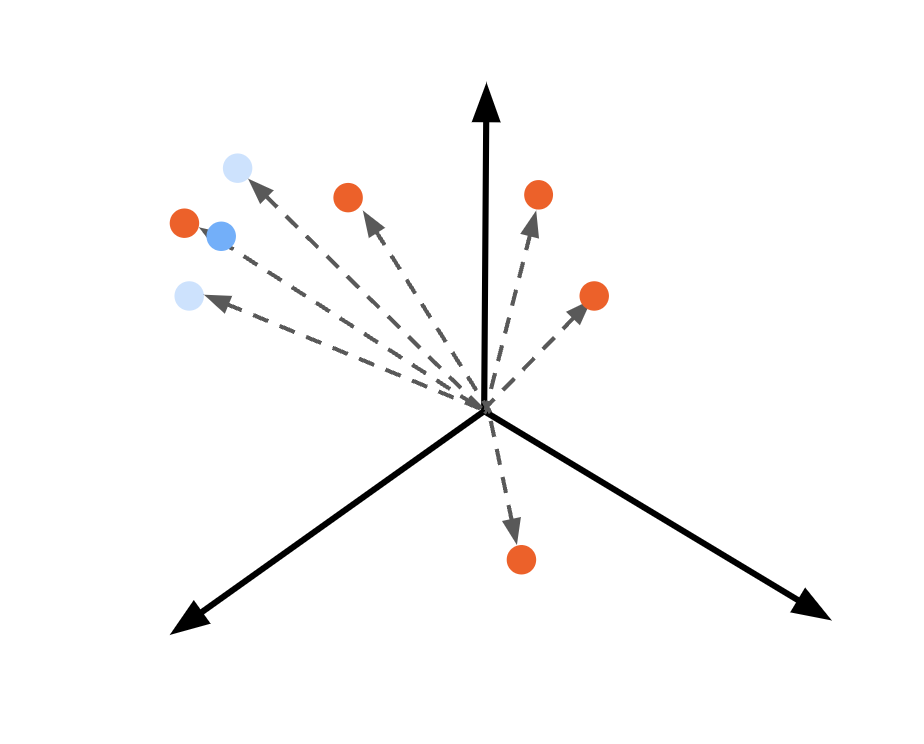
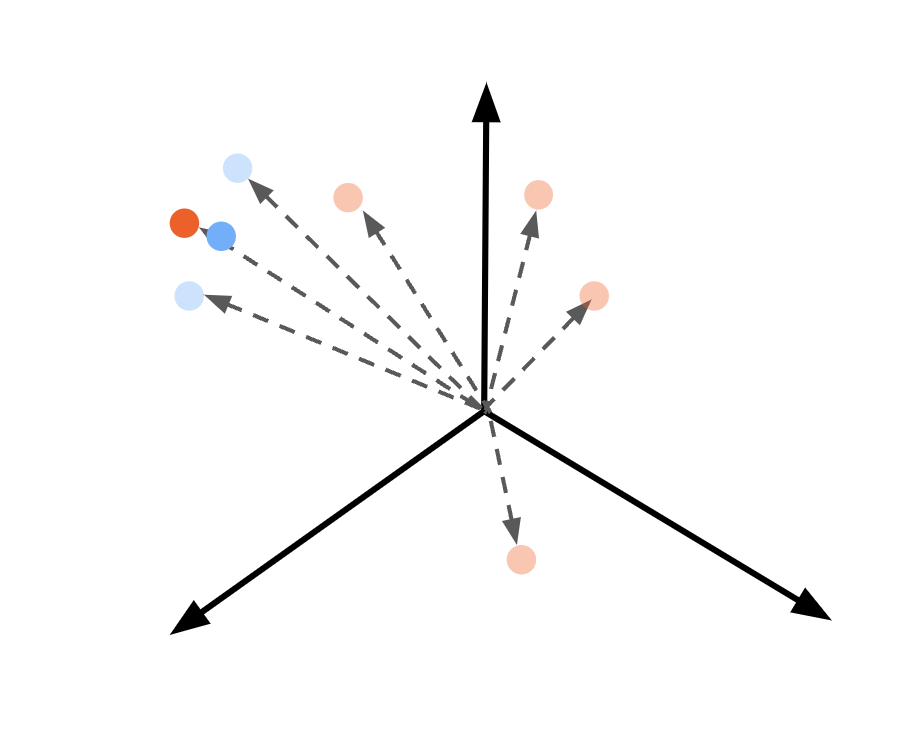
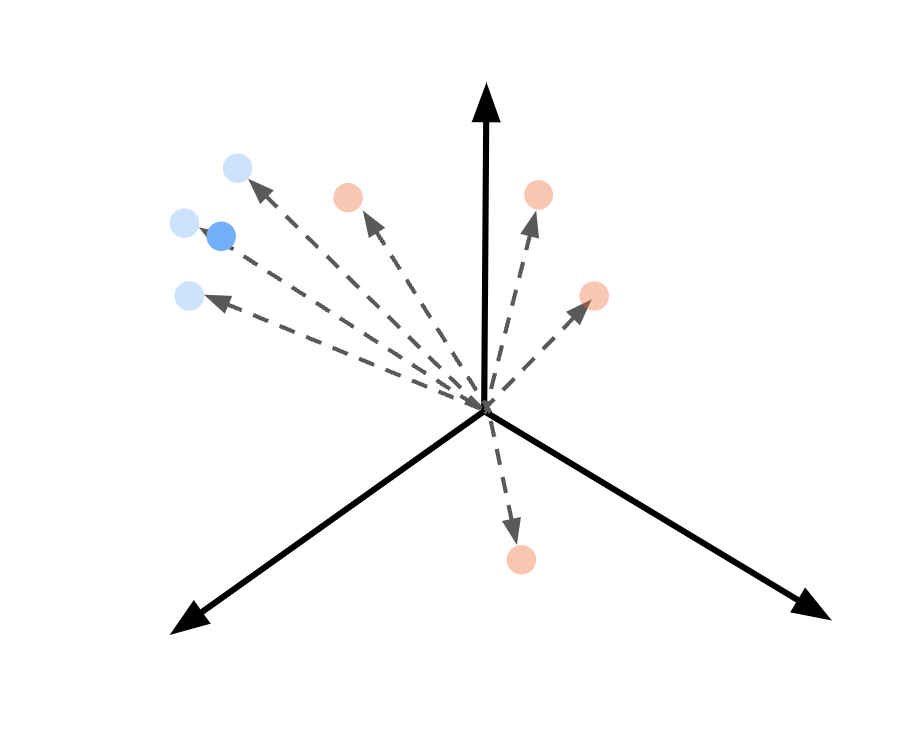
在兩點之間加入一個由兩個向量平均計算出的點。

Introduction to Embeddings with the OpenAI API

多個資料點的推薦


流程:

  • 取多個向量的平均合併為一個
  • 計算餘弦距離
  • 推薦最近的向量

已標示出最近的紅點作為推薦。

Introduction to Embeddings with the OpenAI API

多個資料點的推薦


流程:

  • 取多個向量的平均合併為一個
  • 計算餘弦距離
  • 推薦最近的向量

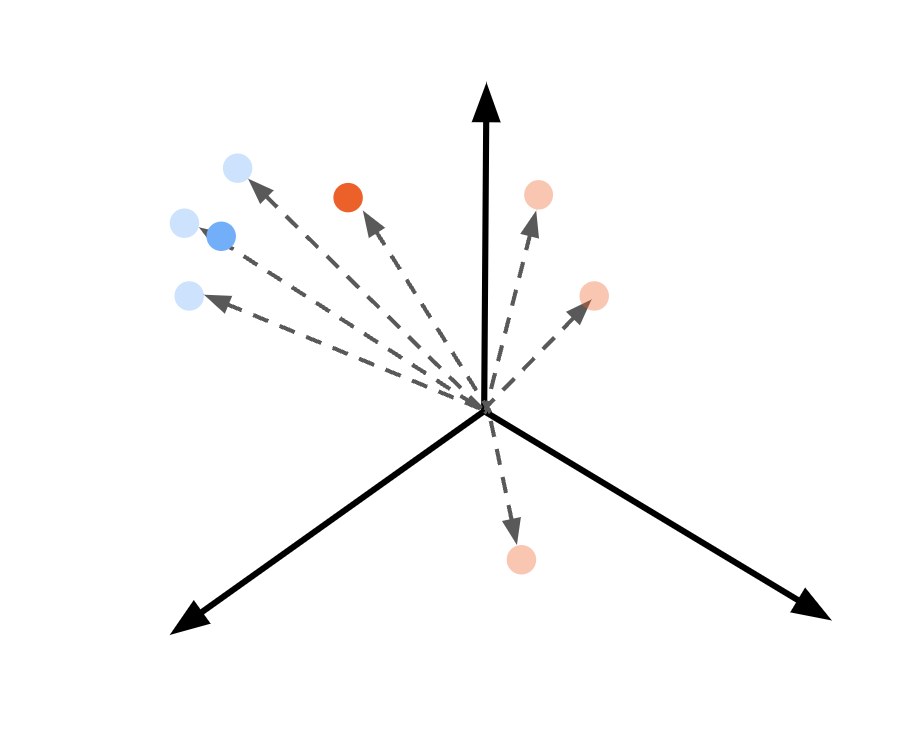
最近的點現在被標成藍色,強調程式應排除使用者已讀的文章。

Introduction to Embeddings with the OpenAI API

多個資料點的推薦


流程:

  • 取多個向量的平均合併為一個
  • 計算餘弦距離
  • 推薦最近的向量
    • 確保尚未閱讀

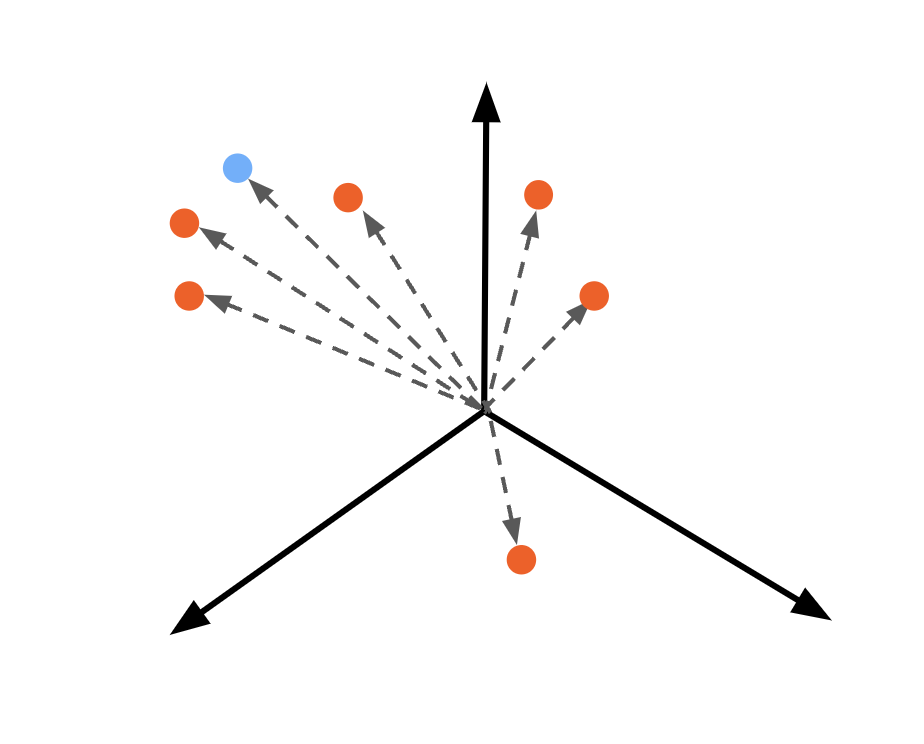
這次標示出更遠一些的最近紅點。

Introduction to Embeddings with the OpenAI API

多個資料點的推薦

def create_article_text(article):
  return f"""Headline: {article['headline']}
Topic: {article['topic']}
Keywords: {', '.join(article['keywords'])}"""

history_texts = [create_article_text(article) for article in user_history]
history_embeddings = create_embeddings(history_texts)

mean_history_embeddings = np.mean(history_embeddings, axis=0)
articles_filtered = [article for article in articles if article not in user_history]
article_texts = [create_article_text(article) for article in articles_filtered] article_embeddings = create_embeddings(article_texts)
Introduction to Embeddings with the OpenAI API

多個資料點的推薦

hits = find_n_closest(mean_history_embeddings, article_embeddings)

for hit in hits: article = articles_filtered[hit['index']] print(article['headline'])
Tech Company Launches Innovative Product to Improve Online Accessibility
New Social Media Platform Has Everyone Talking!
Scientists Make Breakthrough Discovery in Renewable Energy
Introduction to Embeddings with the OpenAI API

一起來練習吧!

Introduction to Embeddings with the OpenAI API

Preparing Video For Download...