非監督式學習

Unsupervised Learning in Python

Benjamin Wilson

Director of Research at lateral.io

非監督式學習

  • 非監督式學習從資料中找出模式
  • 例如依購買行為做「叢集」分群
  • 依購買模式壓縮資料(「降維」)
Unsupervised Learning in Python

監督式 vs 非監督式學習

  • 「監督式」學習為預測任務找出模式
  • 例如將腫瘤分類為良性或惡性(「標籤」)
  • 非監督式學習從資料中找出模式
  • ……但沒有特定的預測任務
Unsupervised Learning in Python

Iris 資料集

  • 多株鳶尾花的量測值
  • 三個鳶尾花品種:
    • setosa
    • versicolor
    • virginica
  • 花瓣長、花瓣寬、花萼長、花萼寬(資料集的「特徵」)

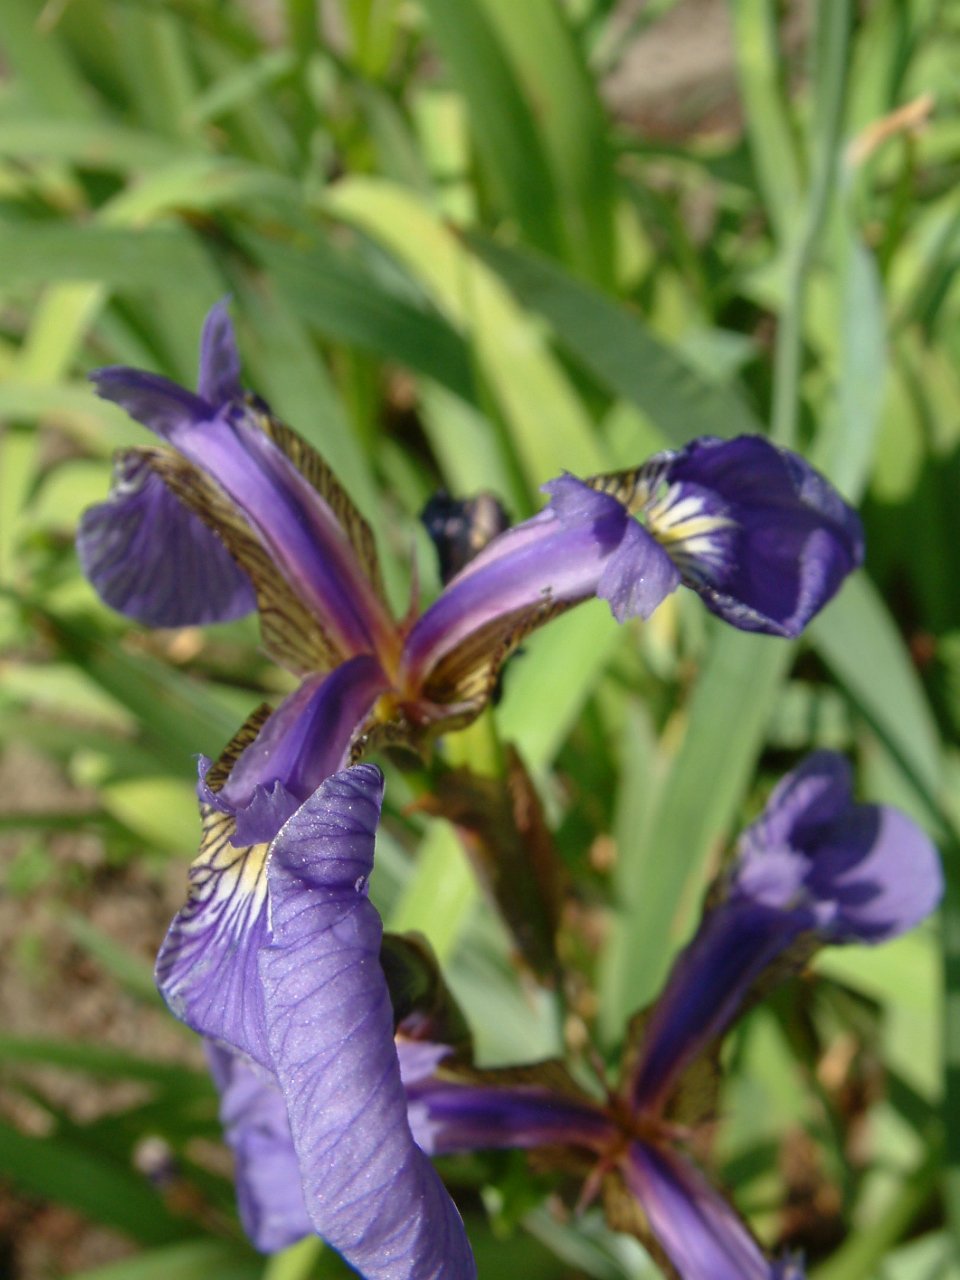
鳶尾花

1 https://scikit-learn.org/stable/modules/generated/sklearn.datasets.load_iris.html
Unsupervised Learning in Python

陣列、特徵與樣本

  • 2D NumPy 陣列
  • 欄為量測值(「特徵」)
  • 列代表鳶尾花樣本(「樣本」)
Unsupervised Learning in Python

Iris 資料為 4 維

  • 鳶尾花樣本是 4 維空間中的點
  • 維度=特徵數
  • 維度太高無法直接視覺化!
  • ……但非監督式學習可提供洞見
Unsupervised Learning in Python

k-means 分群

  • 找出樣本的叢集
  • 需先指定叢集數
  • sklearn(「scikit-learn」)實作
Unsupervised Learning in Python
print(samples)
[[ 5.   3.3  1.4  0.2]
 [ 5.   3.5  1.3  0.3]
 ...
 [ 7.2  3.2  6.   1.8]]
from sklearn.cluster import KMeans

model = KMeans(n_clusters=3)
model.fit(samples)
KMeans(n_clusters=3)
labels = model.predict(samples)

print(labels)
[0 0 1 1 0 1 2 1 0 1 ...]
Unsupervised Learning in Python

新樣本的叢集標籤

  • 可將新樣本指派到現有叢集
  • k-means 記住各叢集的平均值(「質心」)
  • 將新樣本指派到最近的質心
Unsupervised Learning in Python

新樣本的叢集標籤

print(new_samples)
[[ 5.7  4.4  1.5  0.4]
 [ 6.5  3.   5.5  1.8]
 [ 5.8  2.7  5.1  1.9]]
new_labels = model.predict(new_samples)

print(new_labels)
[0 2 1]
Unsupervised Learning in Python

散佈圖

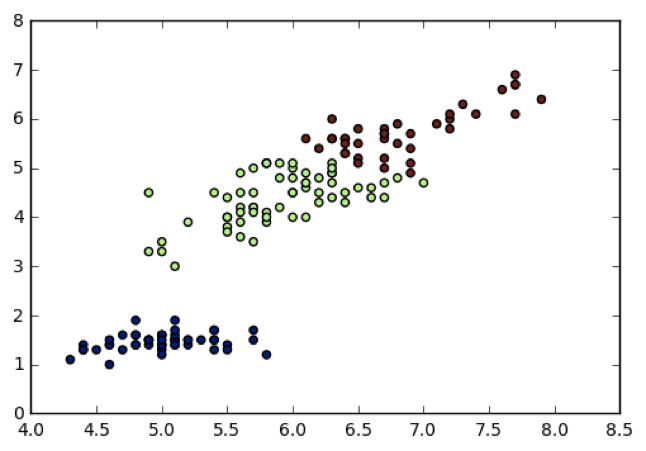
  • 花萼長 vs. 花瓣長的散佈圖
  • 每個點是一個鳶尾花樣本
  • 以叢集標籤著色
  • PyPlot(matplotlib.pyplot

散佈圖

Unsupervised Learning in Python

散佈圖

import matplotlib.pyplot as plt

xs = samples[:,0] ys = samples[:,2]
plt.scatter(xs, ys, c=labels)
plt.show()
Unsupervised Learning in Python

一起來練習吧!

Unsupervised Learning in Python

Preparing Video For Download...