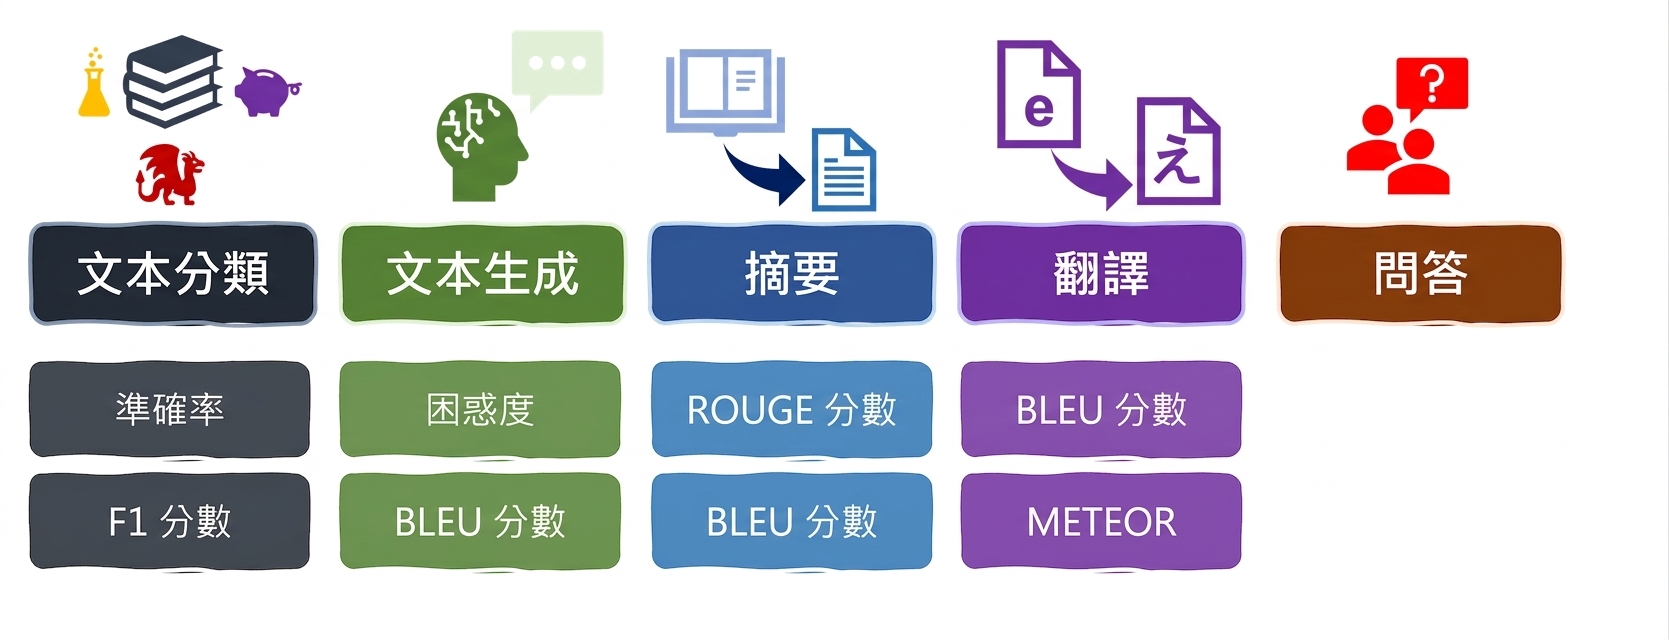
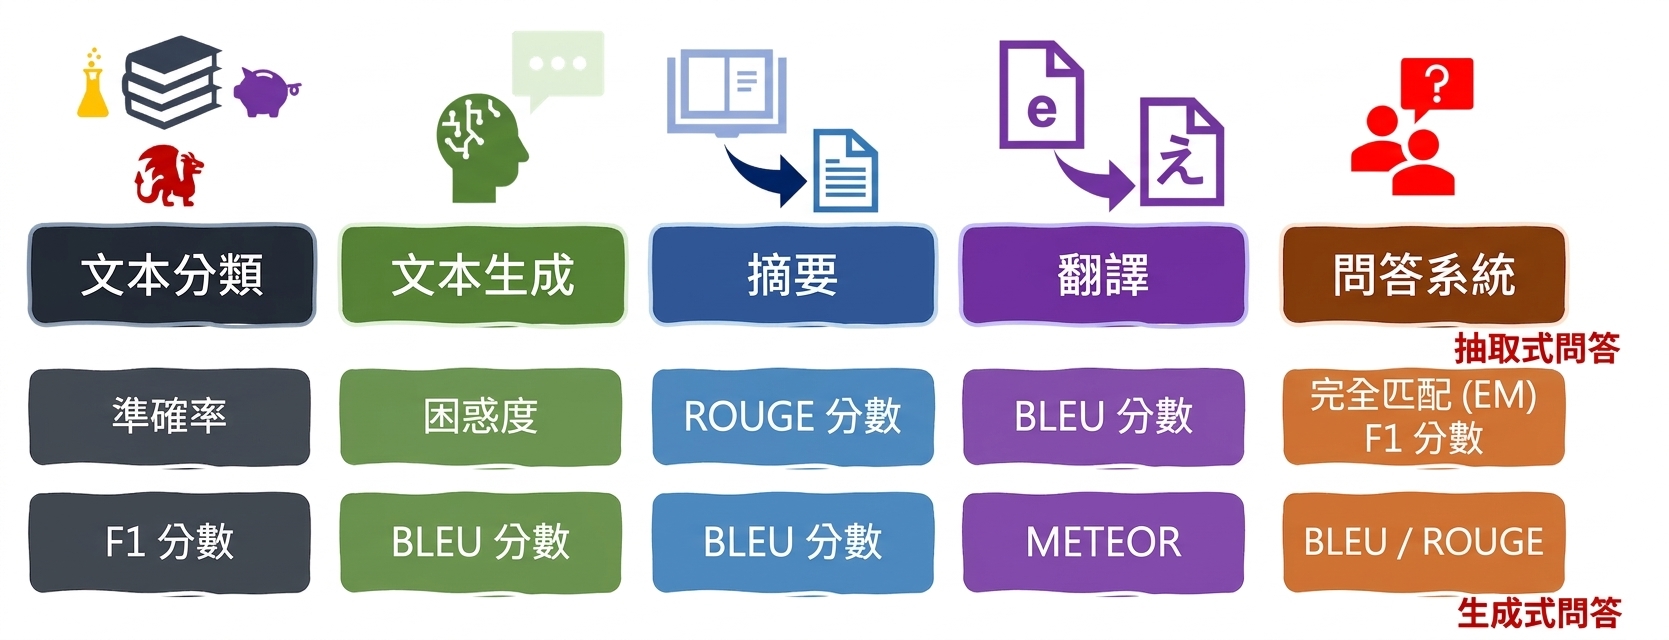
語言任務評估指標:ROUGE、METEOR、EM

Python 的 LLM 入門

Jasmin Ludolf

Senior Data Science Content Developer, DataCamp

LLM 任務與指標
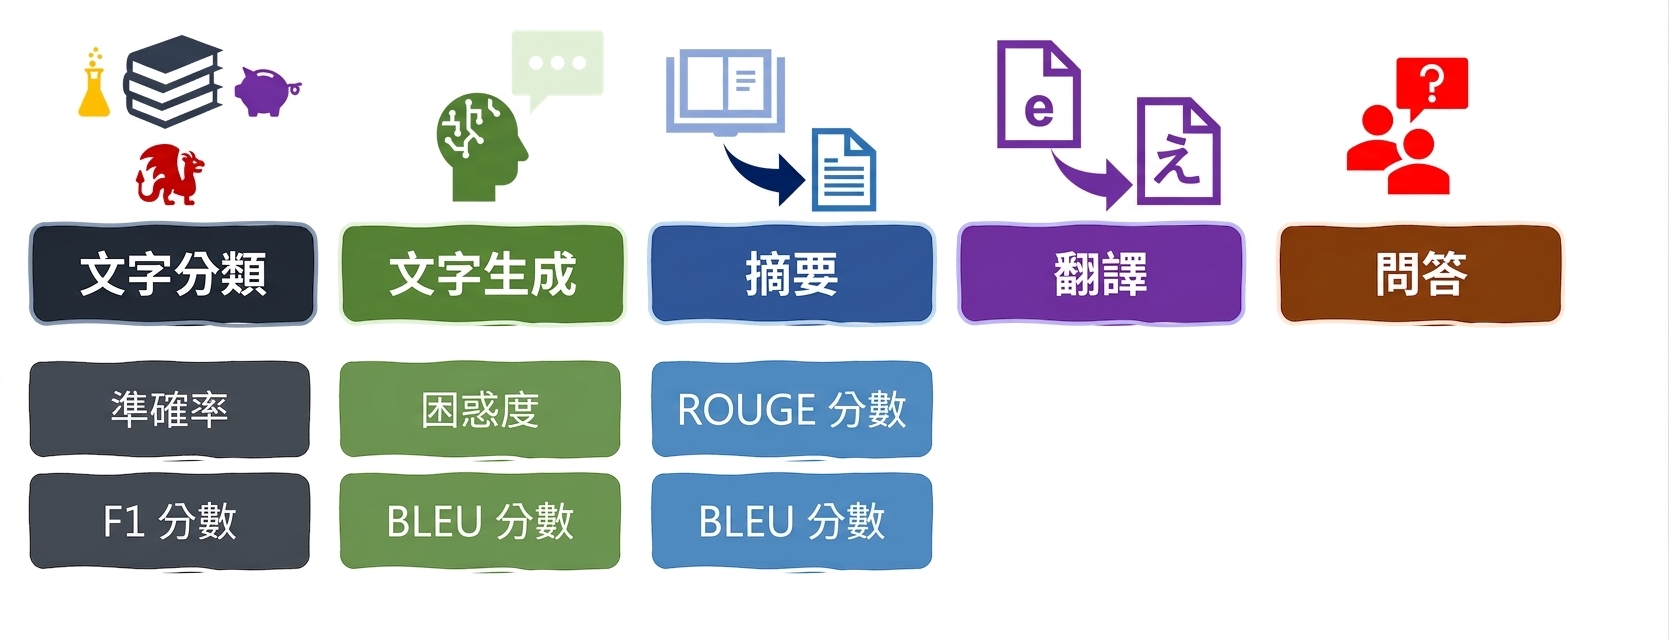
 

語言任務的評估指標

Python 的 LLM 入門

LLM 任務與指標


語言任務的評估指標

Python 的 LLM 入門

LLM 任務與指標


語言任務的評估指標

Python 的 LLM 入門

ROUGE

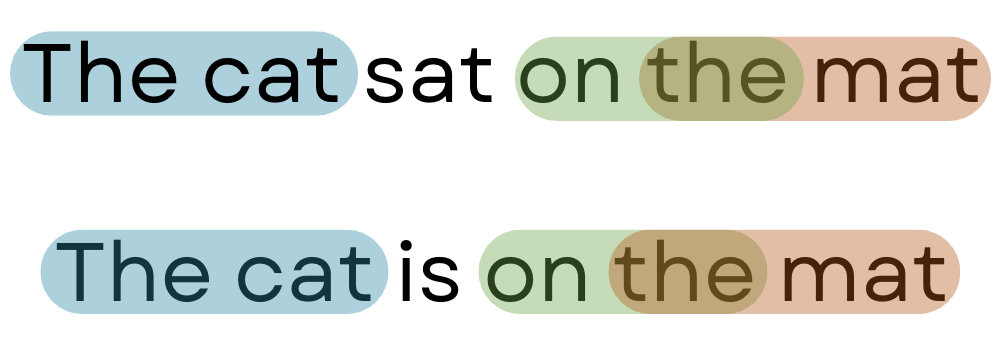
  • ROUGE: 生成摘要與參考摘要的相似度
    • 比對 n-gram 與重疊部分
    • predictions: LLM 輸出
    • references: 人工作者提供的摘要

比較 the cat sat on the mat 與 the cat is on the mat

Python 的 LLM 入門

ROUGE

rouge = evaluate.load("rouge")
predictions = ["""as we learn more about the frequency and size distribution of 
exoplanets, we are discovering that terrestrial planets are exceedingly common."""]
references = ["""The more we learn about the frequency and size distribution of 
exoplanets, the more confident we are that they are exceedingly common."""]

ROUGE 分數:

  • rouge1: unigram 重疊
  • rouge2: bigram 重疊
  • rougeL: 最長重疊子序列
Python 的 LLM 入門

ROUGE 輸出

ROUGE 分數:

  • rouge1: unigram 重疊
  • rouge2: bigram 重疊
  • rougeL: 最長重疊子序列


  • 分數介於 0-1:越高代表相似度越高
results = rouge.compute(predictions=predictions,
                         references=references)

print(results)
{'rouge1': 0.7441860465116279, 
'rouge2': 0.4878048780487805, 
'rougeL': 0.6976744186046512, 
'rougeLsum': 0.6976744186046512}
Python 的 LLM 入門

METEOR

  • METEOR: 納入字形變化、同義、詞序等語言特徵
bleu = evaluate.load("bleu")
meteor = evaluate.load("meteor")


prediction = ["He thought it right and necessary to become a knight-errant, roaming the world in armor, seeking adventures and practicing the deeds he had read about in chivalric tales."] reference = ["He believed it was proper and essential to transform into a knight-errant, traveling the world in armor, pursuing adventures, and enacting the heroic deeds he had encountered in tales of chivalry."]
Python 的 LLM 入門

METEOR

results_bleu = bleu.compute(predictions=pred, references=ref)
results_meteor = meteor.compute(predictions=pred, references=ref)
print("Bleu: ", results_bleu['bleu'])
print("Meteor: ", results_meteor['meteor'])
Bleu:  0.19088841781992524
Meteor:  0.5350702240481536
  • 0-1 分數:越高越好
Python 的 LLM 入門

問答(QA)


語言任務的評估指標

Python 的 LLM 入門

Exact Match(EM)

  • Exact Match(EM): 若 LLM 輸出與參考答案完全相同則為 1


  • 通常與 F1 分數 一起使用
from evaluate import load
em_metric = load("exact_match")

exact_match = evaluate.load("exact_match")
predictions = ["The cat sat on the mat.",
               "Theaters are great.", 
               "Like comparing oranges and apples."]
references = ["The cat sat on the mat?", 
              "Theaters are great.", 
              "Like comparing apples and oranges."]

results = exact_match.compute(
  references=references, predictions=predictions)
print(results)
{'exact_match': 0.3333333333333333}
Python 的 LLM 入門

一起來練習吧!

Python 的 LLM 入門

Preparing Video For Download...