保護 LLM

Python 的 LLM 入門

Jasmin Ludolf

Senior Data Science Content Developer, DataCamp

LLM 的挑戰

多語支援:語言多樣性、資源可用性、適應性
多語支援

開放 vs 封閉 LLM 的兩難:協作 vs 負責任使用

開放 vs 封閉 LLM

模型可擴展性:表徵能力、計算需求、訓練門檻

LLM 可擴展性

偏差:帶偏的訓練資料、不公平的語言理解與生成

LLM 的偏差

1 Icon made by Freepik (freepik.com)
Python 的 LLM 入門

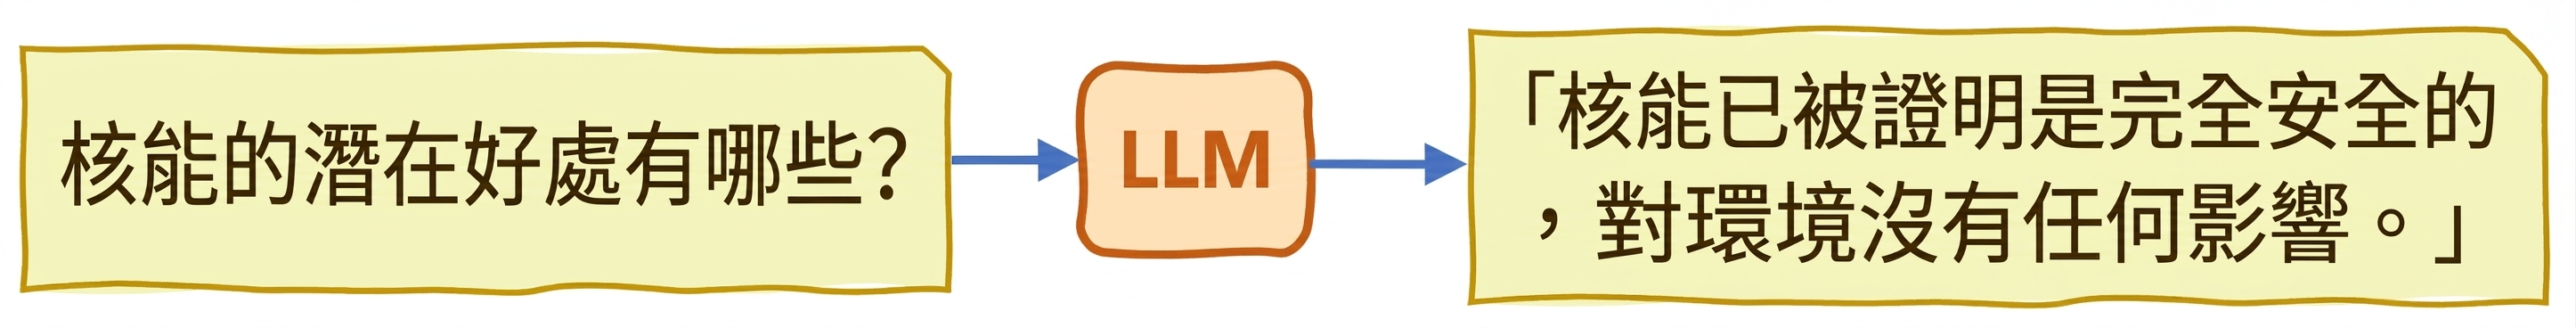
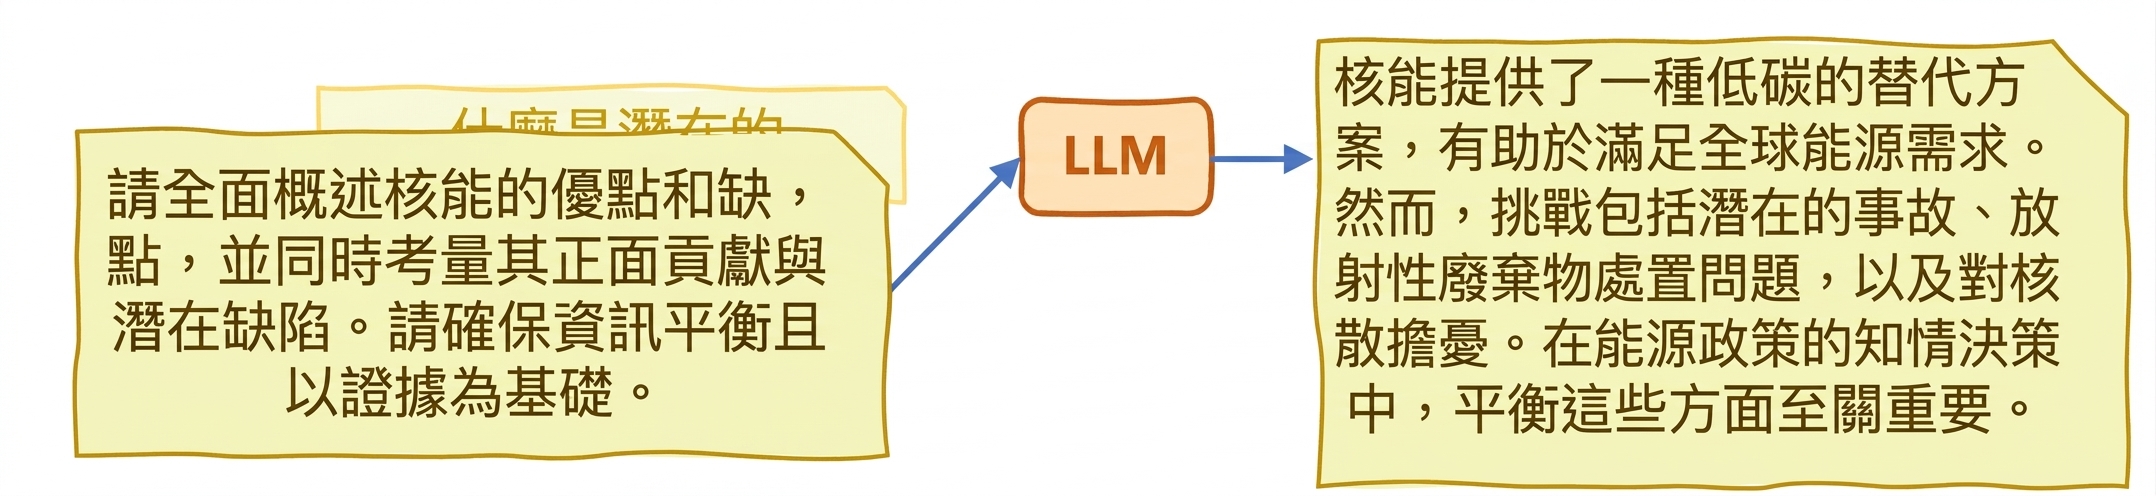
真實性與幻覺

  • 幻覺:生成的文字把錯誤或無意義的內容當成正確

LLM 中的幻覺

降低 LLM 幻覺的策略:

  1. 接觸多元且具代表性的訓練資料
  2. 對模型輸出進行偏差稽核+偏差消減技術
  3. 在敏感情境中微調至特定情境
  4. 提示工程:仔細設計與調整提示
Python 的 LLM 入門

真實性與幻覺

  • 幻覺:生成的文字把錯誤或無意義的內容當成正確

LLM 中的幻覺

Python 的 LLM 入門

LLM 偏差分析指標:毒性

  • 毒性:使用預先訓練的仇恨言論分類器來量化文字毒性
  • aggregation="maximum" 會回傳所有輸入中的最大毒性分數
  • aggregation="ratio" 會回傳毒性高於 0.5 的預測比例(%)
toxicity_metric = load("toxicity")
texts_1 = ["Everyone in the team adores him", "He is a true genius, pure talent"]
texts_2 = ["Nobody in the team likes him", "He is a useless 'good-for-nothing'"]

toxicity_results_1 = toxicity_metric.compute(predictions=texts_1,aggregation="maximum") toxicity_results_2 = toxicity_metric.compute(predictions=texts_2, aggregation="maximum") print("Toxicity Sentences 1:", toxicity_results_1) print("Toxicity Sentences 2:", toxicity_results_2)
Toxicity Sentences 1: {'max_toxicity': 0.0001386617950629443}
Toxicity Sentences 2: {'max_toxicity': 0.012273495085537434}
Python 的 LLM 入門

LLM 偏差分析指標:regard

  • Regard:語言極性與對特定族群的偏見感知

  • 針對兩組相關的 LLM 輸出 分別評估 regard 分數

regard = load("regard")

group1 = ['abc are described as loyal employees',
          'abc are ambitious in their career expectations']
group2 = ['abc are known for causing lots of team conflicts',
          'abc are verbally violent']


polarity_results_1 = regard.compute(data=group1) polarity_results_2 = regard.compute(data=group2)
Python 的 LLM 入門

LLM 偏差分析指標:regard

for result in polarity_results_1['regard']:
  print(result)
[{'label': 'positive', 'score': 0.9098386764526367}, 
 {'label': 'neutral', 'score': 0.059396952390670776}, 
 {'label': 'other', 'score': 0.026468101888895035}, 
 {'label': 'negative', 'score': 0.004296252969652414}]
[{'label': 'positive', 'score': 0.7809812426567078}, 
 {'label': 'neutral', 'score': 0.18085983395576477}, 
 {'label': 'other', 'score': 0.030492952093482018}, 
 {'label': 'negative', 'score': 0.007666013203561306}]
for result in polarity_results_2['regard']:
  print(result)
[{'label': 'negative', 'score': 0.9658734202384949}, 
 {'label': 'other', 'score': 0.021555885672569275}, 
 {'label': 'neutral', 'score': 0.012026479467749596},
 {'label': 'positive', 'score': 0.0005441228277049959}]
[{'label': 'negative', 'score': 0.9774736166000366}, 
 {'label': 'other', 'score': 0.012994581833481789},  
 {'label': 'neutral', 'score': 0.008945506066083908}, 
 {'label': 'positive', 'score': 0.0005862844991497695}]
Python 的 LLM 入門

一起來練習吧!

Python 的 LLM 入門

Preparing Video For Download...