evaluate 函式庫

Python 的 LLM 入門

Jasmin Ludolf

Senior Data Science Content Developer, DataCamp

evaluate 函式庫

import evaluate

accuracy = evaluate.load("accuracy")
print(accuracy.description)
Accuracy is the proportion of correct
predictions among the total number of cases
processed. It can be computed with:
Accuracy = (TP + TN) / (TP + TN + FP + FN)
Where:
TP: True positive
TN: True negative
FP: False positive
FN: False negative


  • 指標: 依據真實標記評估模型表現


  • 比較: 比較兩個模型


  • 量測: 掌握資料集特性
Python 的 LLM 入門

Features 屬性

print(accuracy.features)
{'predictions': Value(dtype='int32', id=None),
 'references': Value(dtype='int32', id=None)}

檢視指標所需輸入

  • 'predictions':模型輸出
  • 'references':真實標記
  • .features:指出類別標籤支援的型別,如 'int32' 或 'float32'
f1 = evaluate.load("f1")
print(f1.features)
{'predictions': Value(dtype='int32', id=None),
 'references': Value(dtype='int32', id=None)}
pearson_corr = evaluate.load("pearsonr")
print(pearson_corr.features)
{'predictions': Value(dtype='float32', id=None),
'references': Value(dtype='float32', id=None)}
Python 的 LLM 入門

LLM 任務與指標


語言任務的評估指標

Python 的 LLM 入門

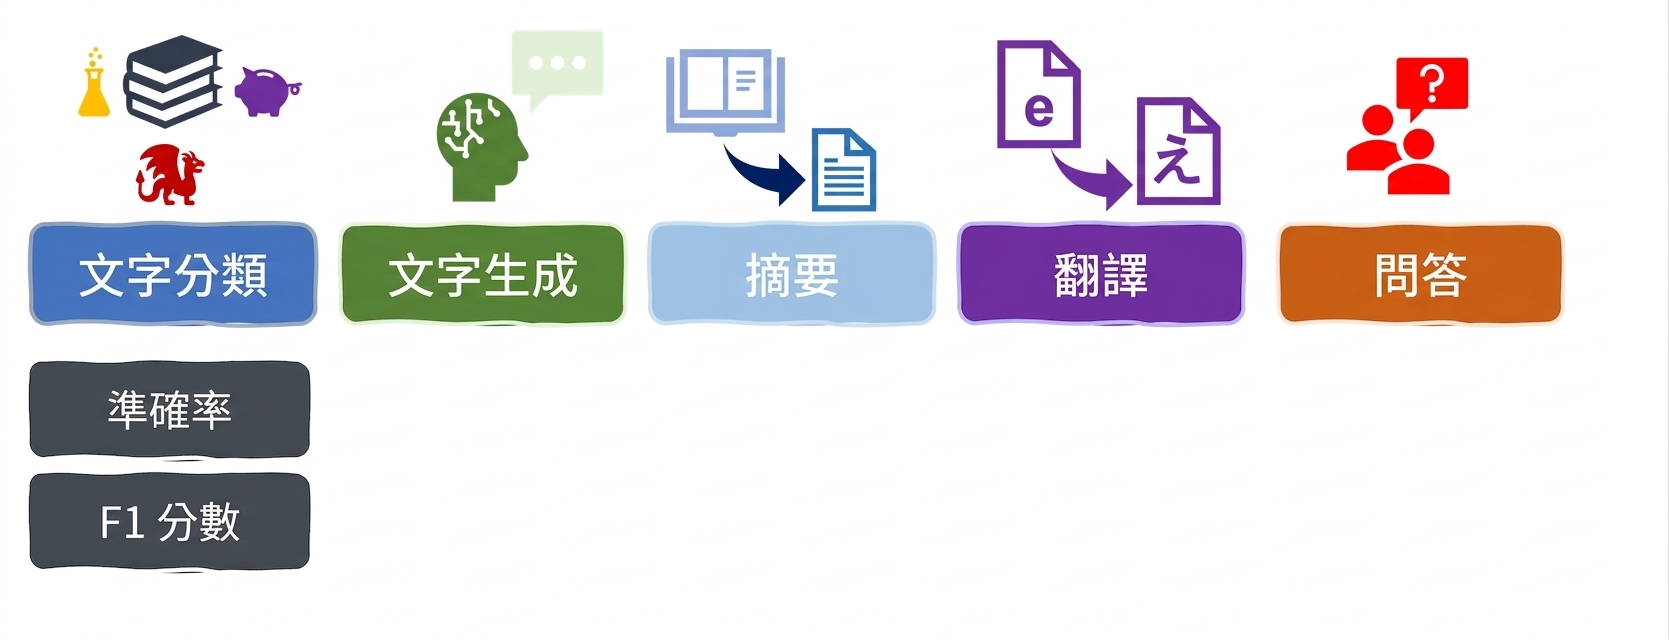
LLM 任務與指標


語言任務的評估指標

Python 的 LLM 入門

分類指標

accuracy = evaluate.load("accuracy")
precision = evaluate.load("precision")
recall = evaluate.load("recall")
f1 = evaluate.load("f1")
from transformers import pipeline

classifier = pipeline("text-classification", model=model, tokenizer=tokenizer)

predictions = classifier(evaluation_text)

predicted_labels = [1 if pred["label"] == "POSITIVE" else 0 for pred in predictions]
Python 的 LLM 入門

指標輸出

real_labels = [0,1,0,1,1]
predicted_labels = [0,0,0,1,1]

print(accuracy.compute(references=real_labels, predictions=predicted_labels))
print(precision.compute(references=real_labels, predictions=predicted_labels))
print(recall.compute(references=real_labels, predictions=predicted_labels))
print(f1.compute(references=real_labels, predictions=predicted_labels))
{'accuracy': 0.8}
{'precision': 1.0}
{'recall': 0.6666666666666666}
{'f1': 0.8}
Python 的 LLM 入門

評估我們微調後的模型

# 使用 
# .from_pretrained("my_finetuned_files") 載入已儲存的模型與 tokenizer


new_data = ["This is movie was disappointing!", "This is the best movie ever!"] new_input = tokenizer(new_data, return_tensors="pt", padding=True, truncation=True, max_length=64) with torch.no_grad(): outputs = model(**new_input) predicted = torch.argmax(outputs.logits, dim=1).tolist()
real = [0,1]
print(accuracy.compute(references=real,
                       predictions=predicted))
print(precision.compute(references=real,
                        predictions=predicted))
print(recall.compute(references=real,
                     predictions=predicted))
print(f1.compute(references=real, 
                 predictions=predicted))
{'accuracy': 1.0}
{'precision': 1.0}
{'recall': 1.0}
{'f1': 1.0}
Python 的 LLM 入門

選對評估指標


  • 請先有警覺:每個指標都帶來洞見,但也有其限制


  • 要全面:結合多種指標(必要時加入領域特定的 KPI)

腦與燈泡的插圖,象徵覺察、思考與決策。

Python 的 LLM 入門

一起來練習吧!

Python 的 LLM 入門

Preparing Video For Download...